Archives
Browse articles organized by date
September 2026 4
Master Thesis Ideas (2026/27)
Thesis Proposals for the S&DE Seminar
Places I Visited
A world map of the places I have visited, for work and for fun.
Building a RAG Pipeline on Custom Documents with Apertus
Schweizer Jugend forscht Study Week "Coding Camp 2026", hosted at USI
Engineering of Domain-Specific Languages (2026)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
August 2026 1
A Taxonomy of Design Quality in Super Mario Maker 2
Thanks to its popularity, Super Mario Maker 2 (SMM2) features myriad user-designed platforming levels that span a broad range of styles, genres, difficulty, and quality. This paper is a first attempt at charting out this vast landscape of levels, with the goal of exploring the main concepts that characterize design quality. To this end, we first selected 500 videos by popular YouTube streamers that play SMM2 levels. With the help of an LLM, we extracted and clustered by topic segments where the streamer comments about the design of the level they are playing. Then, we applied a grounded theory coding process to extract the concepts emerging in these segments, and we combined and organized them hierarchically. The resulting taxonomy identifies the main abstract concepts that pertain to the design of a level in SMM2 and its resulting quality, as well as several concrete elements of the game that belong to each abstract category. Besides illustrating the underlying dimensions that characterize design quality in SMM2, our results also illuminate the diverse landscape of player-designed levels in the game.
June 2026 7
Software Atelier 4: Software Engineering Project (2026)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
Cortex: A Role-Based Transaction Traceability System for High-Volume Walk-In Barbershops
Robert Gomez Cueva · Bachelor of Science in Informatics
Reconstructing Narrative Complexity in Fallout 4
Andrey Kan · Bachelor of Science in Informatics
The new USI Room Management System
Francesc Jordi Sacco Cremonesi · Bachelor of Science in Informatics
Bridging the Gap: Designing Decision-Support Tools for Small Hotel Management
Theodor Vavassori · Bachelor of Science in Informatics
FairLex: AI-Based Assistant for Legal Compliance and Sustainability Challenges in the Fashion Industry
Francesco De Vito · Master of Science in Software & Data Engineering
A Customized RAG-Based Chatbot for iCorsi
Gianluca Maragliano · Master of Science in Software & Data Engineering
February 2026 1
No Pandas Were Harmed: Elegant and Efficient Data Analytics with Polars
Voxxed Days Ticino 2026
January 2026 2
Large Language Models for Automated Requirement Classification
Loren Shukry · Bachelor of Science in Informatics
A Simple DSL to Query Challenging Patterns on Platformer Levels
Boris Bezzola · Master of Science in Software & Data Engineering
December 2025 1
Engineering of Domain-Specific Languages (2025)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
November 2025 2
Full-Stack Web Development Study Day for High-School Students
Study day (giornata di approfondimento) for Liceo di Mendrisio, USI Faculty of Informatics
September 2025 1
AI-Driven Analysis and Optimization of Fairness in Competitive Video Games
Federico Lagrasta · Master of Science in Informatics
August 2025 2
Mining a Century of Swiss Trademark Data
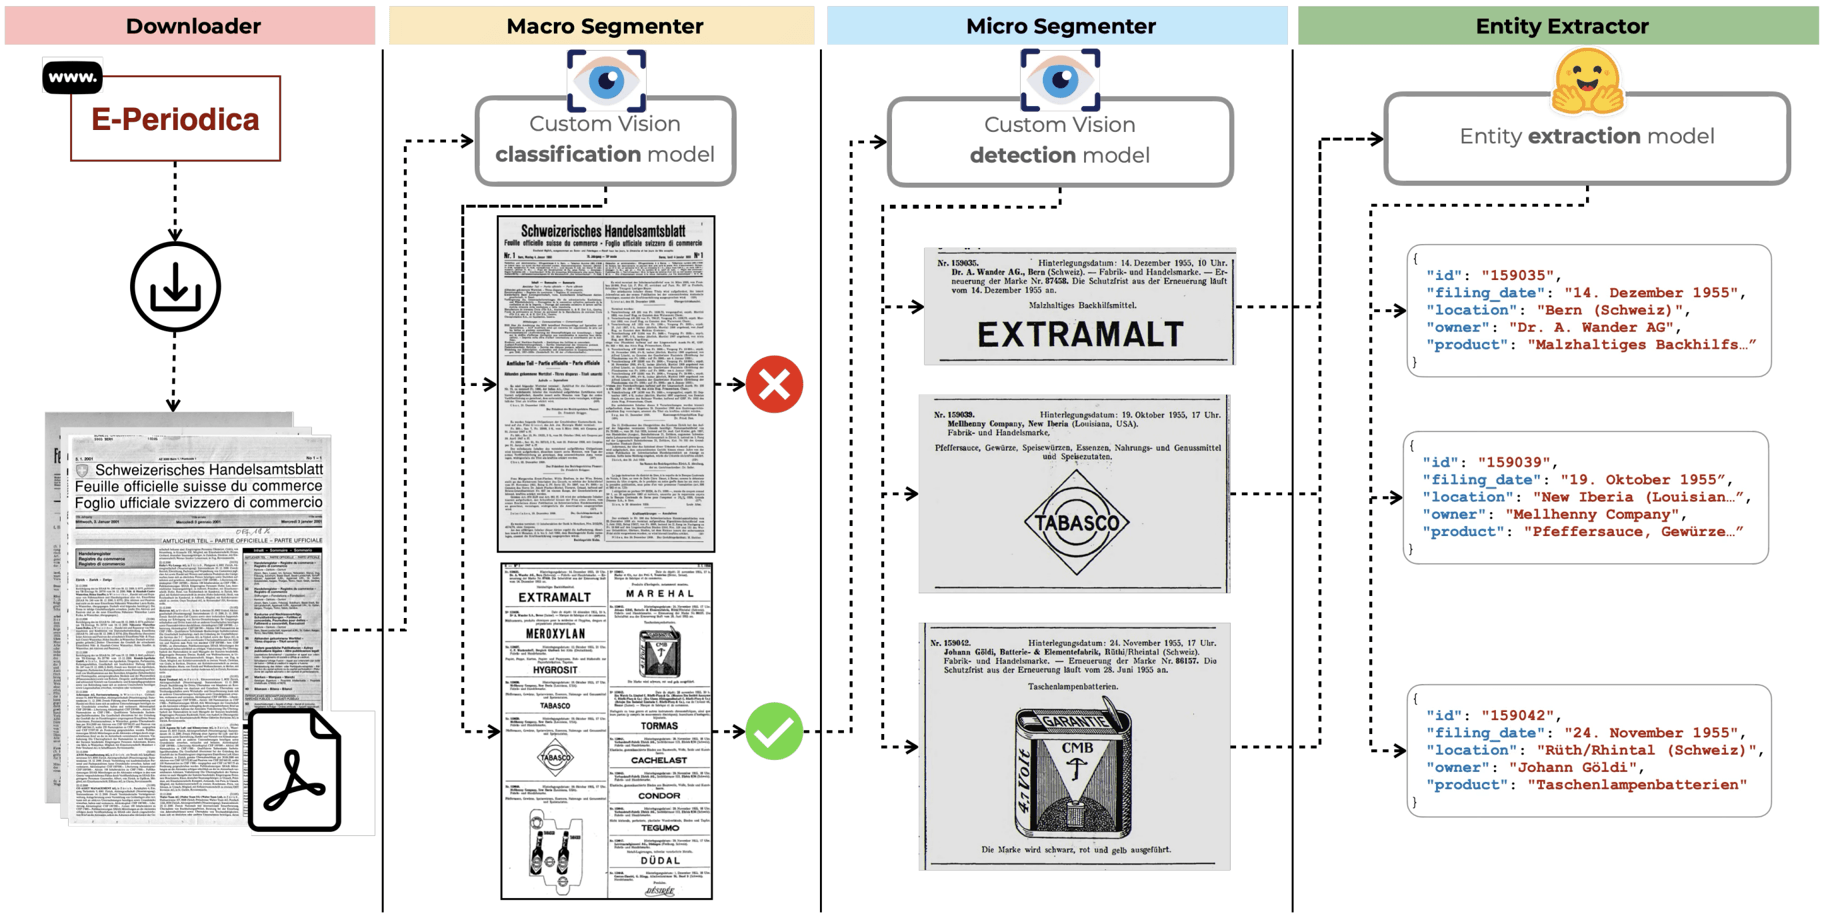
This paper presents an approach for extracting trademark registration events from the Swiss Official Gazette of Commerce (SOGC), an official daily journal published by the Swiss Confederation since January 1883. Until 2001, the data is only available as scanned documents, which constitute the target dataset of this study. Our approach is composed of a chain of three steps based on state-of-the-art deep learning techniques. We leverage image classification to identify pages containing trademarks (macro segmentation); we apply object detection to identify the portion of the page corresponding to a registration event (micro segmentation); last, we perform information extraction using a document AI technique. We obtain a dataset of ca. 500,000 trademark registration events, extracted from a corpus of 430,000 pages. Each step of our workflow has relatively high accuracy: the macro and micro segmentation steps show precision and recall greater than 95% on a manually constructed dataset. The dataset offers a unique historical perspective on trademark registrations in Switzerland that is not available from any other source. Showcasing what can be achieved with the extracted information, we provide answers to a set of preliminary economics questions.
What Makes a Level Hard in Super Mario Maker 2?
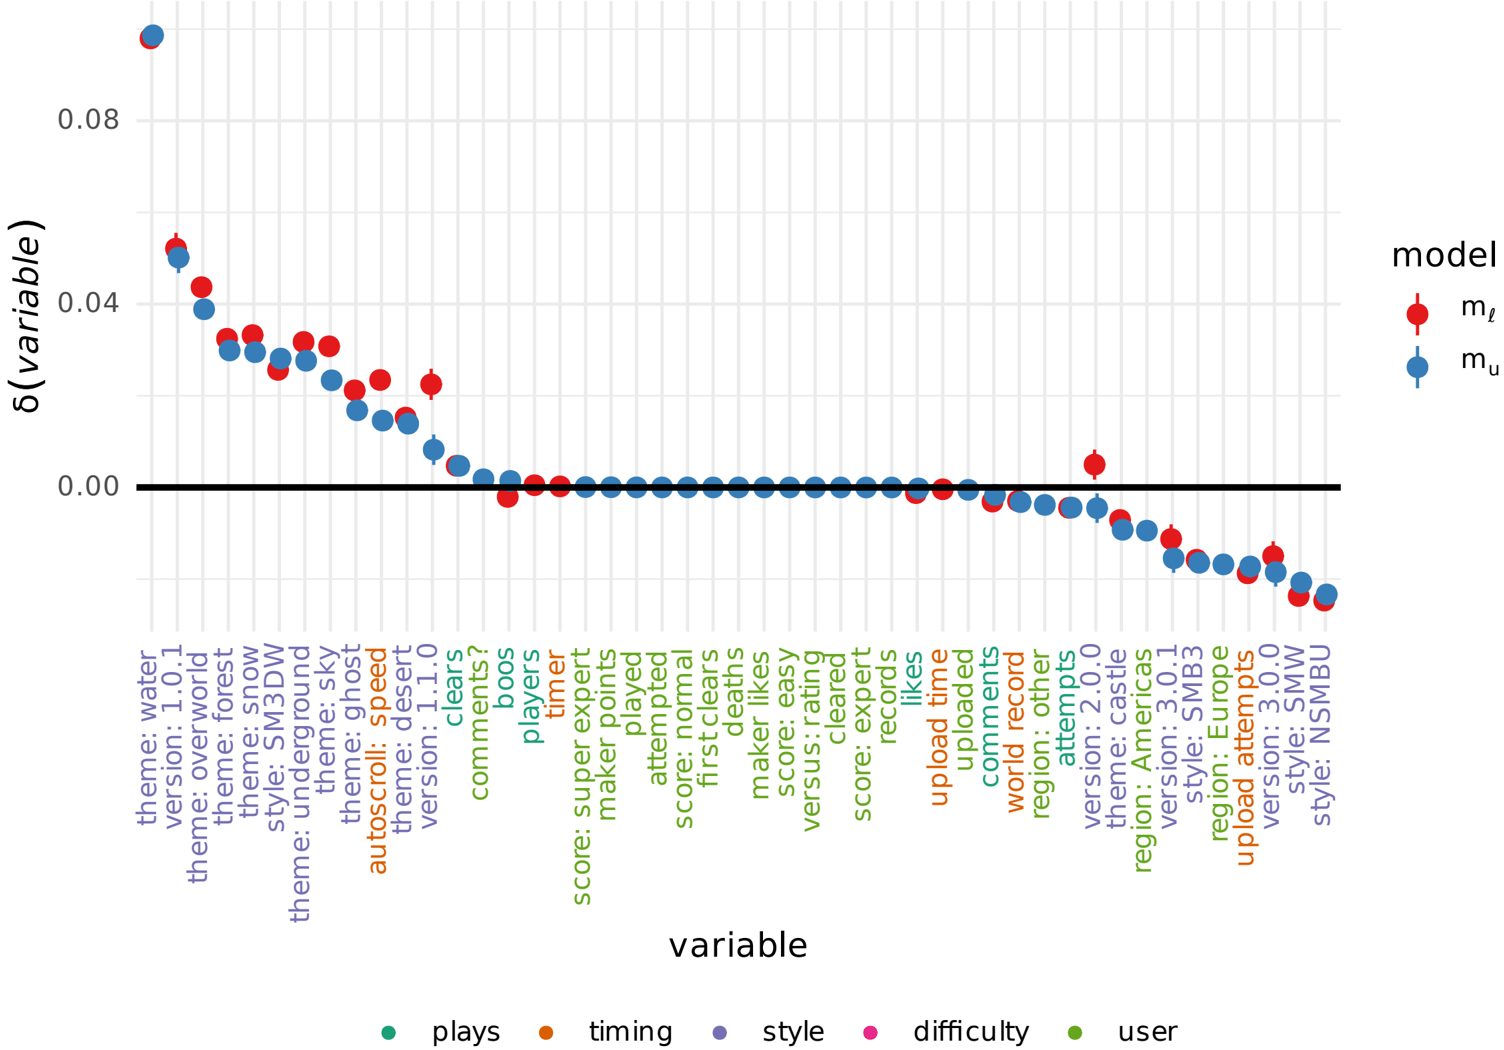
Games like Super Mario Maker 2 (SMM2) lower the barrier for casual users to become level designers. In this paper, we set out to analyze a vast amount of data about SMM2 user-written levels, in order to understand what factors affect a level's difficulty as experienced by other users. To this end, we perform two kinds of analyses: one based on regression models and one using natural language processing techniques. The main results shed light on which level characteristics (e.g., its style, popularity, timing) and which topics and sentiments have a consistent association with easier or harder levels. While none of our findings are startling, they help distill some key differences between easy and hard SMM2 levels, which, in turn, can pave the way for a better understanding of end-user level design.
June 2025 1
Software Atelier 4: Software Engineering Project (2025)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
May 2025 1
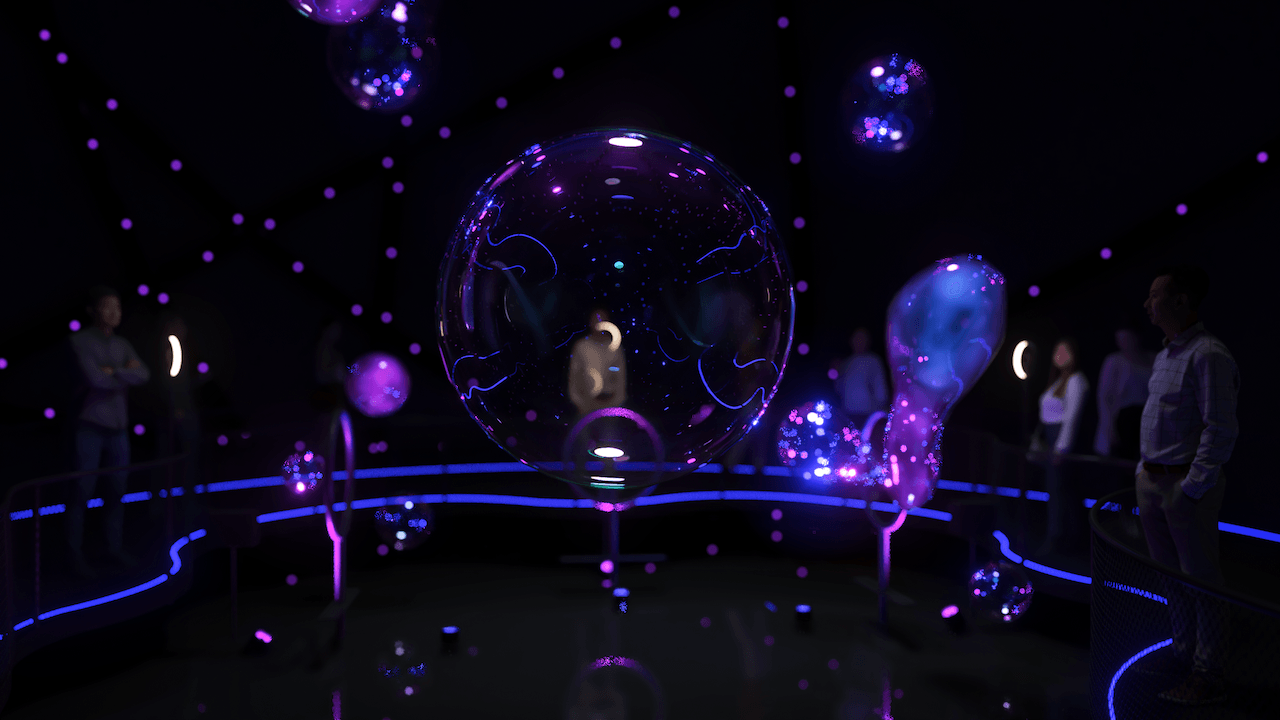
Sphere Two: Swiss Pavilion @ Expo 2025
An interactive art-science installation for the Swiss Pavilion at Expo 2025 that turns visitors' spoken wishes into floating soap bubbles.
March 2025 1
January 2025 1
Spatio-Temporal Visualization of Evolving Company Networks
Francesco Bresciani · Master of Science in Software & Data Engineering
December 2024 1
Engineering of Domain-Specific Languages (2024)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
November 2024 1
Sphere Two: Swiss Pavilion @ Expo 2025
An interactive art-science installation for the Swiss Pavilion at Expo 2025 that turns visitors' spoken wishes into floating soap bubbles.
August 2024 1
Serious Game for Urban Economics Education
A Serious Game to teach Urban Economics built by students of Informatics for students of Economics
June 2024 1
Software Atelier 4: Software Engineering Project (2024)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
March 2024 4
Post-Conference Notes on Voxxed Days Zurich 2024
A little report on Voxxed Days Zurich 2024
Minimize your Python Discomfort: A tour of NLP with Spacy, ScalaPy, and Scala 3
Scalar 2024
Firms and tax competition in the digital economy: a data platform for geo-temporal network analysis
Building a data platform on the network of firms that supports geo and temporal analysis
December 2023 1
Engineering of Domain-Specific Languages (2023)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
September 2023 2
The Rise of the Stochastic Parrots for Developers
3rd International Software Engineering Summer School
Serious Game for Urban Economics Education
A Serious Game to teach Urban Economics built by students of Informatics for students of Economics
June 2023 5
Software Atelier 4: Software Engineering Project (2023)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
Modeling and Analyzing Time-Dependent Network of Firms
Federico Lombardo · Master of Science in Software & Data Engineering
Mining A Century of Swiss Trademarks
Daniel Travaglia · Master of Science in Software & Data Engineering
Post-Conference Notes on Scala Days 2023 Seattle
A short report on Scala Days 2023.
April 2023 1
Alfred
A Discord bot that helps the CodeLounge team with server maintenance: it follows Icinga monitoring alerts, calls in whoever is on duty, and keeps the weekly maintenance rotation
December 2022 2
Engineering of Domain-Specific Languages (2022)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
Software quality assessment for Justitia 4.0
In-depth analysis of a large software system from multiple perspectives
October 2022 1
Software quality assessment for Justitia 4.0
In-depth analysis of a large software system from multiple perspectives
September 2022 3
Branching Scenarios in Interacting Video Tutorials
Davide Ciulla · Master of Science in Software & Data Engineering
Institutional Foundations of Industrialization, Financialization, and Globalization of the Swiss Economy
Leveraging NLP and ML to transform historical corpora into structured geocoded data
REFLEX Data Pipeline & REFLEXplorer
The software backbone of the REFLEX project: a document-AI and NLP pipeline turning 140 years of scanned Swiss commercial registry into structured, geocoded data, and a web platform to explore it
June 2022 2
Software Atelier 4: Software Engineering Project (2022)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
Encoding Program Comprehension Tasks as Role Playing Games: a Prototype Framework Aiming to Produce Serious Games
Lazar Najdenov · Master of Science in Software & Data Engineering
February 2022 1
Rearchitecting Stormed for Scalability
Martino Giorgi · Bachelor of Science in Informatics
December 2021 1
Engineering of Domain-Specific Languages (2021)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
June 2021 2
Software Atelier 4: Software Engineering Project (2021)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
GITGLASS: Data Analysis and Visualization of Collaborative Development Platforms
Gabriele Zorloni · Master of Science in Software & Data Engineering
April 2021 1
December 2020 2
Engineering of Domain-Specific Languages (2020)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
Beyond Watching: Next Generation Programming Tutorials Leveraging Interaction Data
Making video tutorials fully interactive by leveraging IDE interaction data
September 2020 2
Visualizing Interaction Data Inside & Outside the IDE to Characterize Developer Productivity
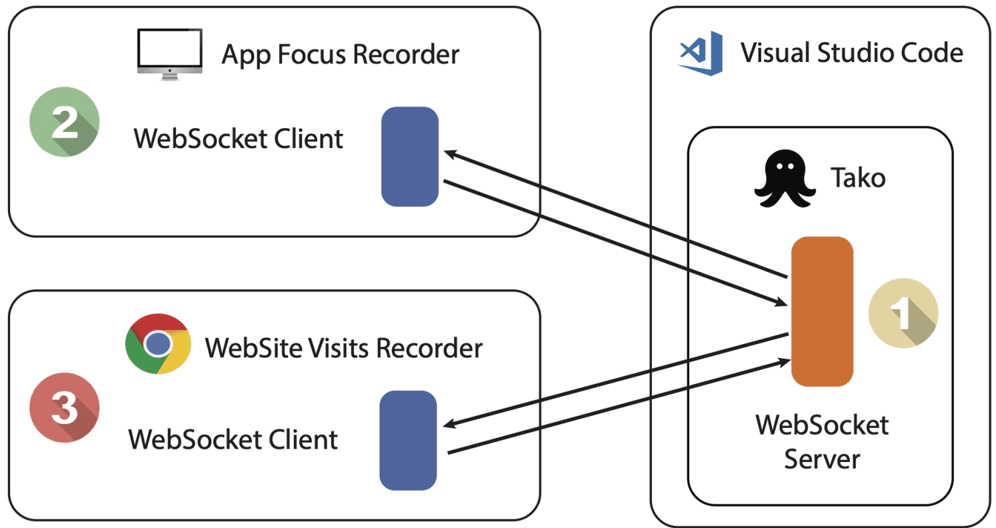
Work fragmentation is a common phenomenon in the workspace, and is detrimental to the actual work taking place. To measure and study the impact of work fragmentation in software development, several studies exploited interaction data, i.e., the data generated by the events performed by the developers in the IDE. However, the absence of information on activities performed outside the IDE could lead to a misclassification of development time. In fact, sometimes leaving the IDE is not an interruption of the task at hand, e.g., when consulting API documentation, or when discussing with colleagues in ad-hoc collaboration applications. In this paper, we propose Ferax, a data analytics platform that developers can leverage for retrospection and possibly to improve their productivity. The capabilities of Ferax are twofold: First, it extends Tako, a profiler to record IDE interaction data for Visual Studio Code, with information about which applications were used and which websites were visited. Second, to enable the understanding of productivity and interruptions on developer sessions, Ferax provides interactive visualizations that show the detailed sequence of events inside and outside the IDE, the switches the developer performs by classifying them as productive or possible interruptions, and the time distribution for application usage. As a preliminary evaluation of Ferax we have collected and analyzed real development sessions from a set of master students and two professional developers. We illustrate how a developer can leverage Ferax to characterize her usual habits, to elicit the impact of interruptions, and to better characterize sessions which were only apparently unproductive.
Automatic Classification of Development Artifact Contents
Alexander Fischer · Master of Science in Software & Data Engineering
June 2020 3
Software Atelier 4: Software Engineering Project (2018-2020) (2020)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
SITRA - Simple Traffic: Support Decision-Making in a Real Context with Traffic Simulation
Valerie Burgener · Master of Science in Software & Data Engineering
Characterizing and Visualizing Development Fragmentation with Interaction Data
Aldo Gabriele Di Rosa · Master of Science in Software & Data Engineering
February 2020 1
Firms and tax competition in the digital economy: a data platform for geo-temporal network analysis
Building a data platform on the network of firms that supports geo and temporal analysis
January 2020 2
Viralscale: Leveraging Virality to Predict and React to Traffic Spikes
Lucas Pennati · Master of Science in Software & Data Engineering
Beyond Watching: Next Generation Programming Tutorials Leveraging Interaction Data
Making video tutorials fully interactive by leveraging IDE interaction data
December 2019 2
Engineering of Domain-Specific Languages (2019)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
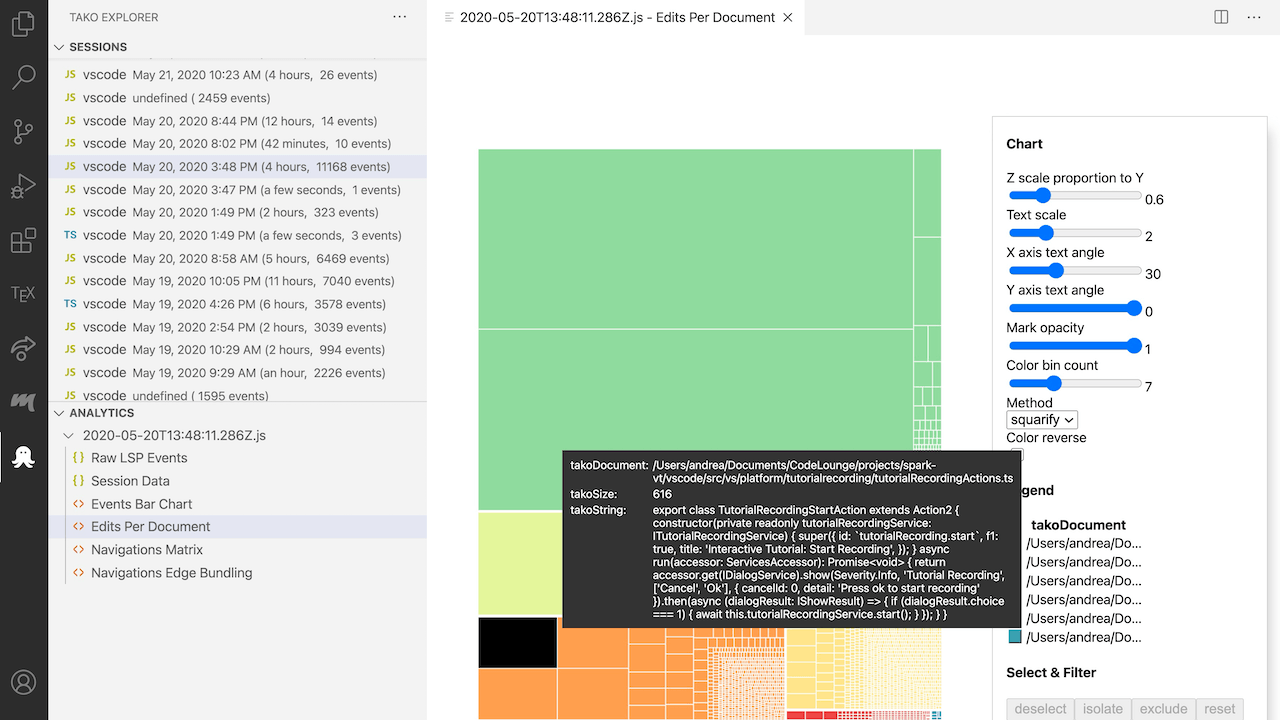
Collecting and Visualizing Development Activities in Visual Studio Code
Tracking low-level IDE interaction events and transforming them into meaningful data to understand our own productivity
November 2019 1
USI Hackathon 2019: Making Data Alive
USI Hackathon 2019, organized by CodeLounge (Software Institute, USI)
October 2019 1
Design and Effectiveness of Internal DSLs in Scala
Voxxed Days Ticino 2019
July 2019 2
Collecting and Visualizing Development Activities in Visual Studio Code
Tracking low-level IDE interaction events and transforming them into meaningful data to understand our own productivity
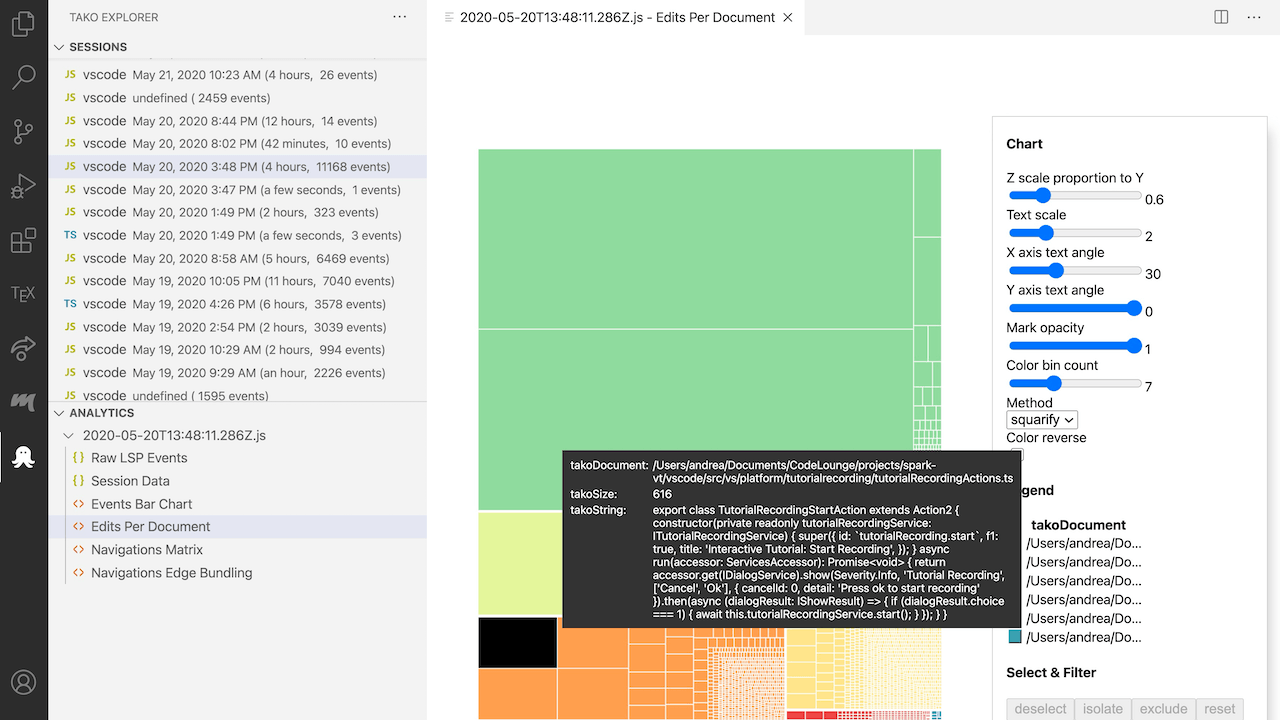
Tako
A Visual Studio Code extension that records, aggregates, and visualizes IDE interaction data — entirely on the developer's own machine
June 2019 3
Software Atelier 4: Software Engineering Project (2018-2020) (2019)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
Testing Modern Web Applications Written in TypeScript and React
Armend Azizi · Bachelor of Science in Informatics
myUSI Research & Teaching Support Platform
Management and analytics for the University
May 2019 1
Automatic Identification and Classification of Software Development Video Tutorial Fragments
Software development video tutorials have seen a steep increase in popularity in recent years. Their main advantage is that they thoroughly illustrate how certain technologies, programming languages, etc. are to be used. However, they come with a caveat: there is currently little support for searching and browsing their content. This makes it difficult to quickly find the useful parts in a longer video, as the only options are watching the entire video, leading to wasted time, or fast-forwarding through it, leading to missed information. We present an approach to mine video tutorials found on the web and enable developers to query their contents as opposed to just their metadata. The video tutorials are processed and split into coherent fragments, such that only relevant fragments are returned in response to a query. Moreover, fragments are automatically classified according to their purpose, such as introducing theoretical concepts, explaining code implementation steps, or dealing with errors. This allows developers to set filters in their search to target a specific type of video fragment they are interested in. In addition, the video fragments in CodeTube are complemented with information from other sources, such as Stack Overflow discussions, giving more context and useful information for understanding the concepts.
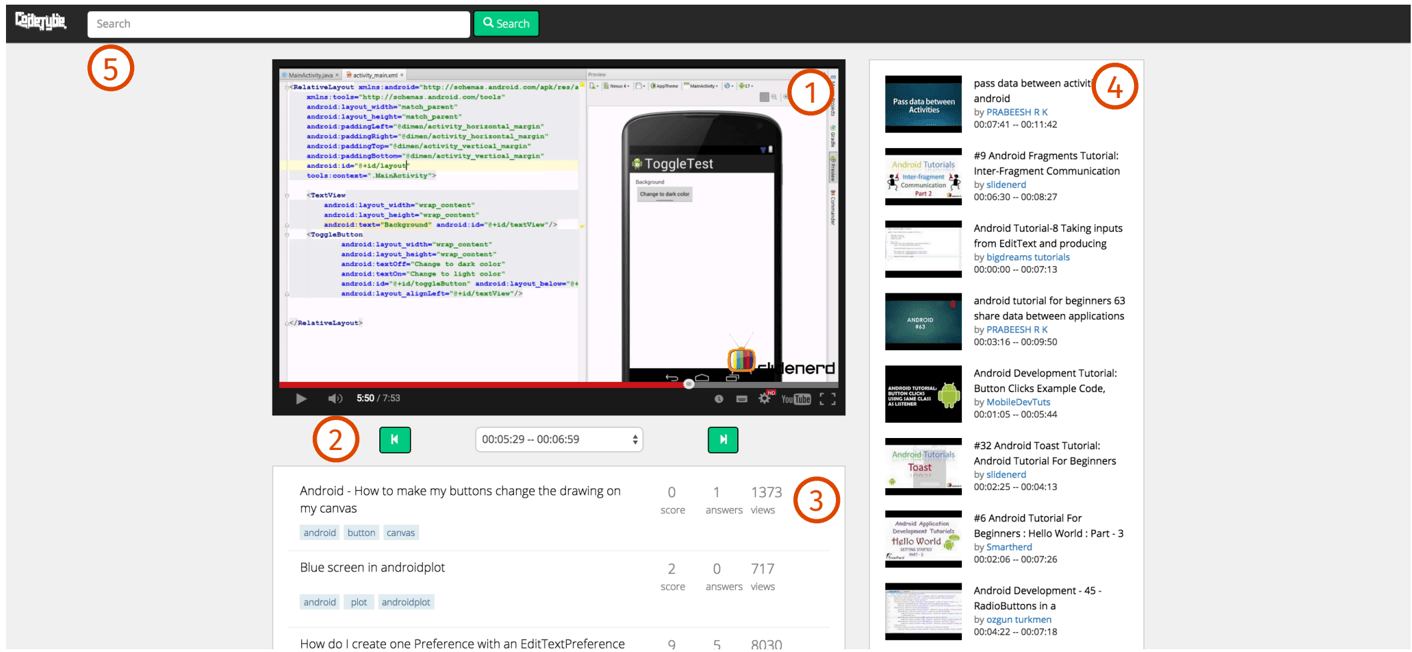
December 2018 1
Engineering of Domain-Specific Languages (2018)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
September 2018 1
jSicko
A Java SImple Contract checKer: a compiler plugin that turns contract annotations written in plain Java into runtime checks
June 2018 3
Software Atelier 4: Software Engineering Project (2018-2020) (2018)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
Research Data Visual Analytics
Lorenzo Ferri · Bachelor of Science in Informatics
University timetable scheduling
Aron Fiechter · Bachelor of Science in Informatics
January 2018 2
myUSI Research & Teaching Support Platform
Management and analytics for the University
MyUSI Platform
A modular platform for managing the academic life of a university: a GraphQL-based, actor-oriented backend and a component-based frontend, piloted on the research service
December 2017 2
Engineering of Domain-Specific Languages (2017)
Domain-Specific Languages (DSLs) are programming languages that are tailored to a particular application domain. This essential focus of DSLs allows one to write more concise and understandable programs, with tight stakeholder integration, and, when done properly, to improve code quality. The course will feature the current state of the art in both the design and implementation of DSLs. The course will emphasize the different design dimensions of DSLs, the involved language paradigms and features, and the drawbacks with respect to simple API modeling.
Mining structured data in natural language artifacts with island parsing
Software repositories typically store data composed of structured and unstructured parts. Researchers mine this data to empirically validate research ideas and to support practitioners' activities. Structured data (e.g., source code) has a formal syntax and is straightforward to analyze; unstructured data (e.g., documentation) is a mix of natural language, noise, and snippets of structured data, and it is harder to analyze. Especially the structured content (e.g., code snippets) in unstructured data contains valuable information. Researchers have proposed several approaches to recognize, extract, and analyze structured data embedded in natural language. We analyze these approaches and investigate their drawbacks. Subsequently, we present two novel methods, based on scannerless generalized LR (SGLR) and Parsing Expression Grammars (PEGs), to address these drawbacks and to mine structured fragments within unstructured data. We validate and compare these approaches on development emails and Stack Overflow posts with Java code fragments. Both approaches achieve high precision and recall values, but the PEG-based one achieves better computational performances and simplicity in engineering.
November 2017 2
Interaction-Aware Development Environments: Recording, Mining, and Leveraging IDE Interactions to Analyze and Support the Development Flow
Roberto Minelli · Doctor of Philosophy in Informatics
Investigating the Use of Code Analysis and NLP to Promote a Consistent Usage of Identifiers
Meaningless identifiers as well as inconsistent use of identifiers in the source code might hinder code readability and result in increased software maintenance efforts. Over the past years, effort has been devoted to promoting a consistent usage of identifiers across different parts of a system through approaches exploiting static code analysis and Natural Language Processing (NLP). These techniques have been evaluated in small-scale studies, but it is unclear how they compare to each other and how they complement each other. Furthermore, a full-fledged larger empirical evaluation is still missing.,,We aim at bridging this gap. We asked developers of five projects to assess the meaningfulness of the recommendations generated by three techniques, two already existing in the literature (one exploiting static analysis, one using NLP) and a novel one we propose. With a total of 922 rename refactorings evaluated, this is, to the best of our knowledge, the largest empirical study conducted to assess and compare rename refactoring tools promoting a consistent use of identifiers. Our study sheds light on the current state-of-the-art in rename refactoring recommenders, and indicates directions for future work.
October 2017 2
Sympathy for the Devil: Reified Collection of Runtime Errors
Software development involves iterations of writing, running, testing, and debugging code. When fixing a defect, developers construct a mental model of the system that explains the defect and eventually identifies its cause. However, filtering complete, coherent, and reliable information from a running system is not an easy task: Using a simple approach, like generic logging, is often ineffective because it deconstructs and flattens the state into textual data, thus requiring ad-hoc understanding and processing. On the other hand, collecting structured information in form of objects to observe and understand a precise property of the system requires specialized ad-hoc code, decoupled from the system's domain, and usually not reusable. We present ShoreLine, a domain-specific data collection framework that enables the developers to extract selected information about a running system. The developer is able to take a snapshot of all the information deemed relevant about a piece of code by writing few lines of code, thus enabling structured and effective logging and reporting of errors. We detail our framework in the context of a bug reporting platform, and illustrate how such an approach can be used to create in-depth and reliable domain-specific bug reports.
An Annotation-based API for Supporting Runtime Code Annotation Reading
Code annotations are the core of the main APIs and frameworks for enterprise development, and are widely used on several applications. However, despite these APIs and frameworks made advanced uses of annotations, the language API for annotation reading is far from their needs. In particular, annotation reading is still a relatively complex task, that can consume a lot of development time and that can couple the framework internal structure to its annotations. This paper proposes an annotation-based API to retrieve metadata from code annotations and populate an instance with meta-information ready to be used by the framework. The proposed API is based on best practices and approaches for metadata definition documented on patterns, and has been implemented by a framework named Esfinge Metadata. We evaluated the approach by refactoring an existing framework to use it through Esfinge Metadata. The original and the refactored versions are compared using several code assessment techniques, such as software metrics, and bad smells detection, followed by a qualitative analysis based on source code inspection. As a result, the case study revealed that the usage of the proposed API can reduce the coupling between the metadata reading code and the annotations.
September 2017 1
Assessing Software Documents by Comprehension Effort
Talal El Afchal · Master of Science in Informatics
August 2017 1
Parsing and Modeling Software Engineering Artifacts
IPSJ/SIGSE Software Engineering Symposium 2017
June 2017 7
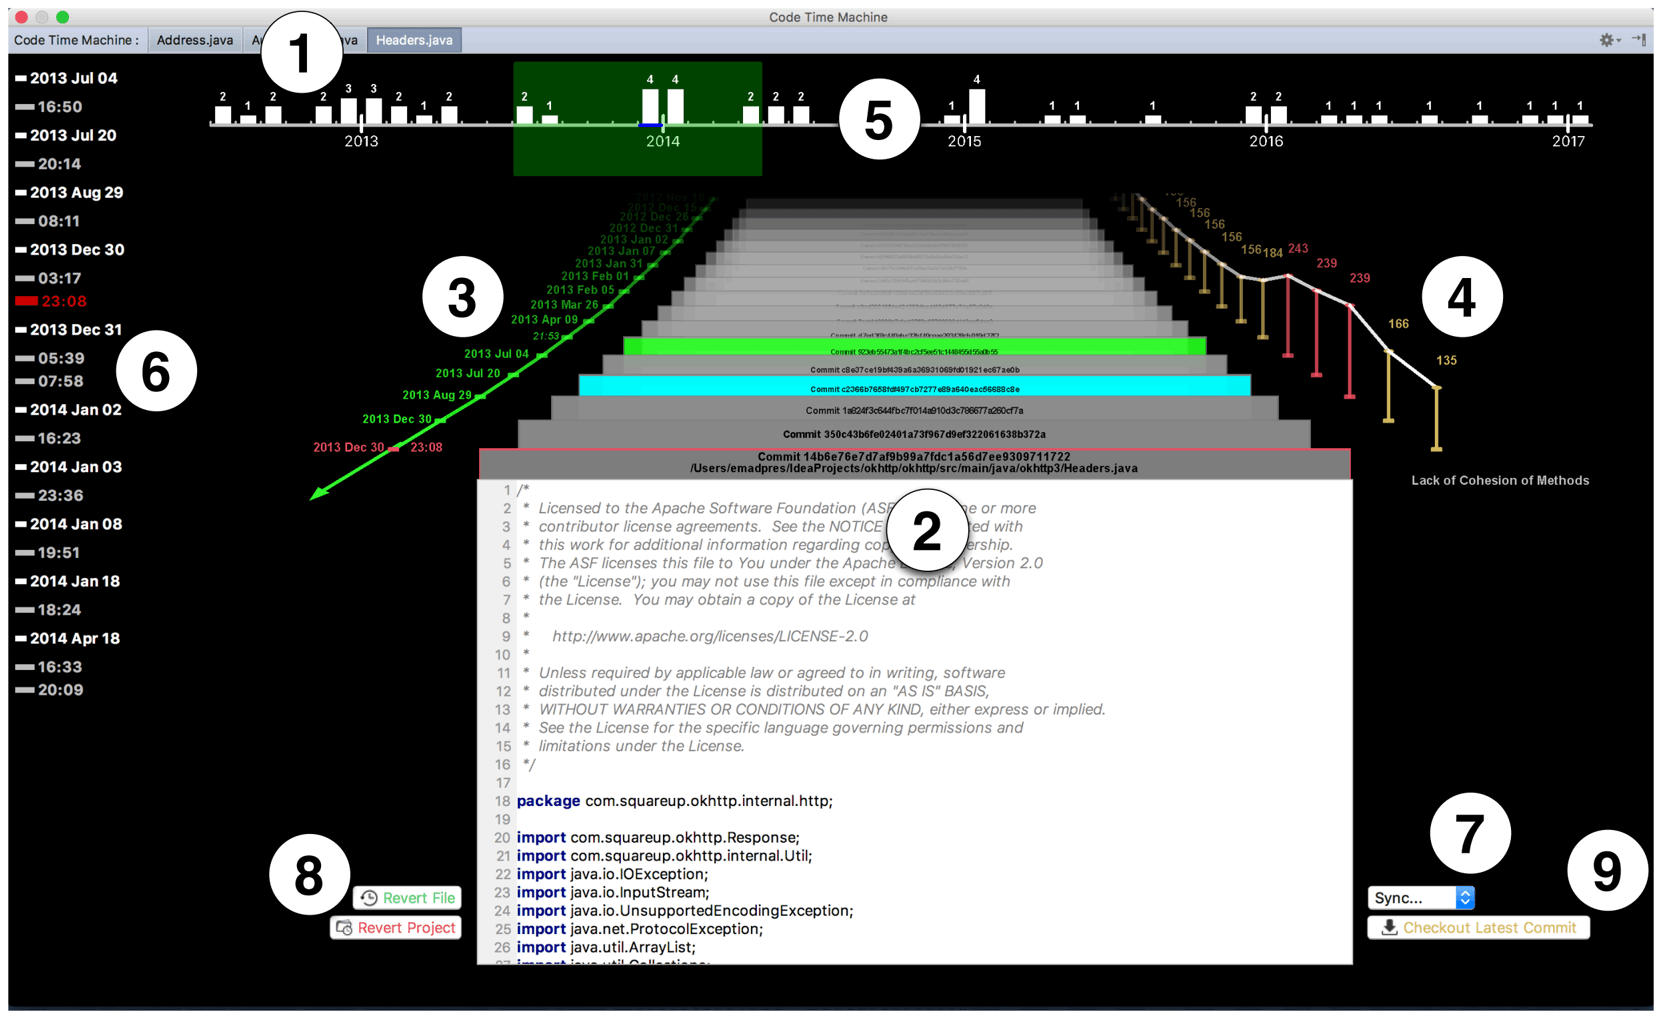
The Code Time Machine
Exploring and analyzing the history of changes is an intrinsic part of software evolution comprehension. Existing tools that exploit the data residing in version control repositories provide only limited support for the intuitive navigation of code changes from a historical perspective. We present the Code Time Machine, a lightweight IDE plugin which uses visualization techniques to depict the history of any chosen file augmented with information mined from the underlying versioning system. Inspired by Apple's Time Machine, our tool allows both developers and the system itself to seamlessly move through time.
On the Uniqueness of Code Redundancies
Code redundancy widely occurs in software projects. Researchers have investigated the existence, causes, and impacts of code redundancy, showing that it can be put to good use, for example in the context of code completion. When analyzing source code redundancy, previous studies considered software projects as sequences of tokens, neglecting the role of the syntactic structures enforced by programming languages. However, differences in the redundancy of such structures may jeopardize the performance of applications leveraging code redundancy. We present a study of the redundancy of several types of code constructs in a large-scale dataset of active Java projects mined from GitHub, unveiling that redundancy is not uniform and mainly resides in specific code constructs. We further investigate the implications of the locality of redundancy by analyzing the performance of language models when applied to code completion. Our study discloses the perils of exploiting code redundancy without taking into account its strong locality in specific code constructs.
How Developers Document Pull Requests with External References
Online resources of formal and informal documentation-such as reference manuals, forum discussions and tutorials-have become an asset to software developers, as they allow them to tackle problems and to learn about new tools, libraries, and technologies. This study investigates to what extent and for which purpose developers refer to external online resources when they contribute changes to a repository by raising a pull request. Our study involved (i) a quantitative analysis of over 150k URLs occurring in pull requests posted in GitHub, (ii) a manual coding of the kinds of software evolution activities performed in commits related to a statistically significant sample of 2,130 pull requests referencing external documentation resources, (iii) a survey with 69 participants, who provided feedback on how they use online resources and how they refer to them when filing a pull request. Results of the study indicate that, on the one hand, developers find external resources useful to learn something new or to solve specific problems, and they perceive useful referring such resources to better document changes. On the other hand, both interviews and repository mining suggest that external resources are still rarely referred in document changes.
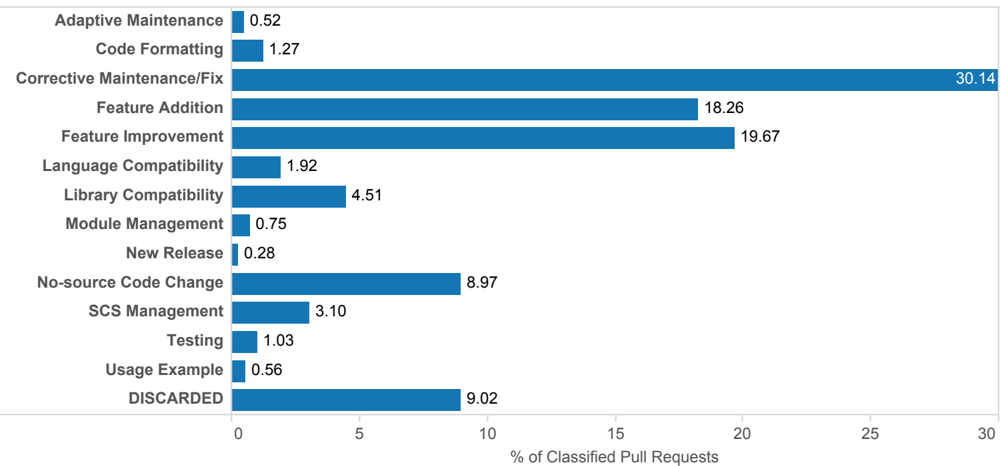
A Voxel-based Approach to Earthquake Simulation
Leonardo Iandiorio · Bachelor of Science in Informatics
May 2017 1
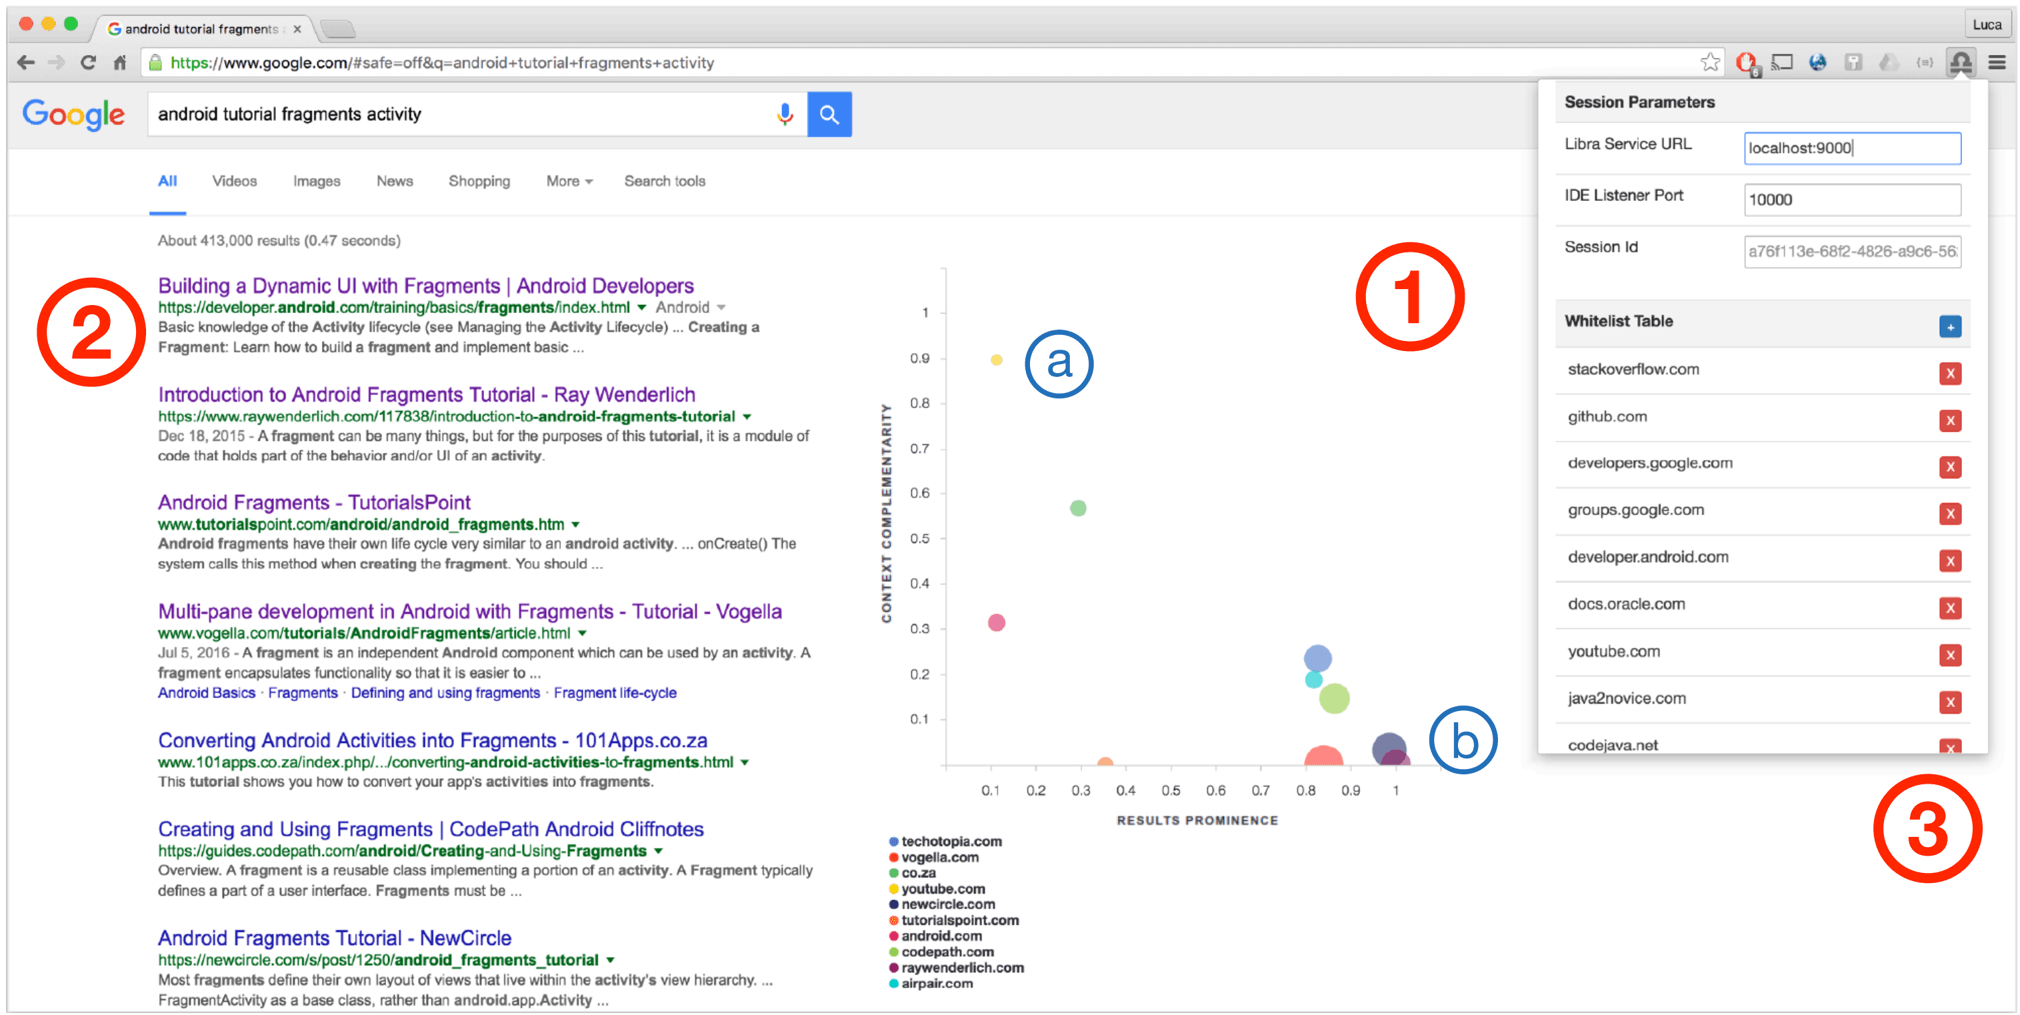
Supporting Software Developers with a Holistic Recommender System
The promise of recommender systems is to provide intelligent support to developers during their programming tasks. Such support ranges from suggesting program entities to taking into account pertinent QnA pages. However, current recommender systems limit the context analysis to change history and developers' activities in the IDE, without considering what a developer has already consulted or perused, e.g., by performing searches from the Web browser. Given the faceted nature of many programming tasks, and the incompleteness of the information provided by a single artifact, several heterogeneous resources are required to obtain the broader picture needed by a developer to accomplish a task. We present Libra, a holistic recommender system. It supports the process of searching and navigating the information needed by constructing a holistic meta-information model of the resources perused by a developer, analyzing their semantic relationships, and augmenting the web browser with a dedicated interactive navigation chart. The quantitative and qualitative evaluation of Libra provides evidence that a holistic analysis of a developer's information context can indeed offer comprehensive and contextualized support to information navigation and retrieval during software development.
March 2017 3
ESSENTIALS: People-centric Essentials for Software Evolution
Shifting the focus of software evolution research to the people-centric 'evolutionary essentials' that stakeholders need in their current working context.
HI-SEA: Holistic Immersive Software Evolution Ambient
A holistic immersive ambient for software evolution, integrating the data around a project into a visual environment for analysis and intelligent recommendations.
Holistic Recommender Systems for Software Engineering
Luca Ponzanelli · Doctor of Philosophy in Informatics
February 2017 1
How to Gamify Software Engineering
Software development, like any prolonged and intellectually demanding activity, can negatively affect the motivation of developers. This is especially true in specific areas of software engineering, such as requirements engineering, test-driven development, bug reporting and fixing, where the creative aspects of programming fall short. The developers' engagement might progressively degrade, potentially impacting their work's quality. Gamification, the use of game elements and game design techniques in non-game contexts, is hailed as a means to boost the motivation of people for a wide range of rote activities. Indeed, well-designed games deeply involve gamers in a positive loop of production, feedback, and reward, eliciting desirable feelings like happiness and collaboration. The question we investigate is how the seemingly frivolous context of games and gamification can be ported to the technically challenging and sober domain of software engineering. Our investigation starts with a review of the state of the art of gamification, supported by a motivating scenario to expose how gamification elements can be integrated in software engineering. We provide a set of basic building blocks to apply gamification techniques, present a conceptual framework to do so, illustrated in two usage contexts, and critically discuss our findings.
December 2016 1
Software Atelier 1: Fundamentals of Informatics (2016)
The first of the ateliers, which are a crucial part of our Bachelor curriculum is roughly divided into three main pieces. On the one hand the students will obtain first-hand experience with a variety of tools of the trade, such as LaTeX, HTML, Versioning, and the unix shell. Second, the students will get an overview of the history of computer science since its very beginning up to the present day. The third part of the atelier is dedicated to a group project, in which students will put into practice what they learned in the course.
November 2016 1
The Tragedy of Defect Prediction, Prince of Empirical Software Engineering Research
If measured by the number of published papers, defect prediction has become an important research field over the past decade, with many researchers continuously proposing novel approaches to predict defects in software systems. However, most of these approaches have had a noticeable lack of impact on industrial practice. This lack of impact is because something is intrinsically wrong in how defect prediction approaches are evaluated.
October 2016 1
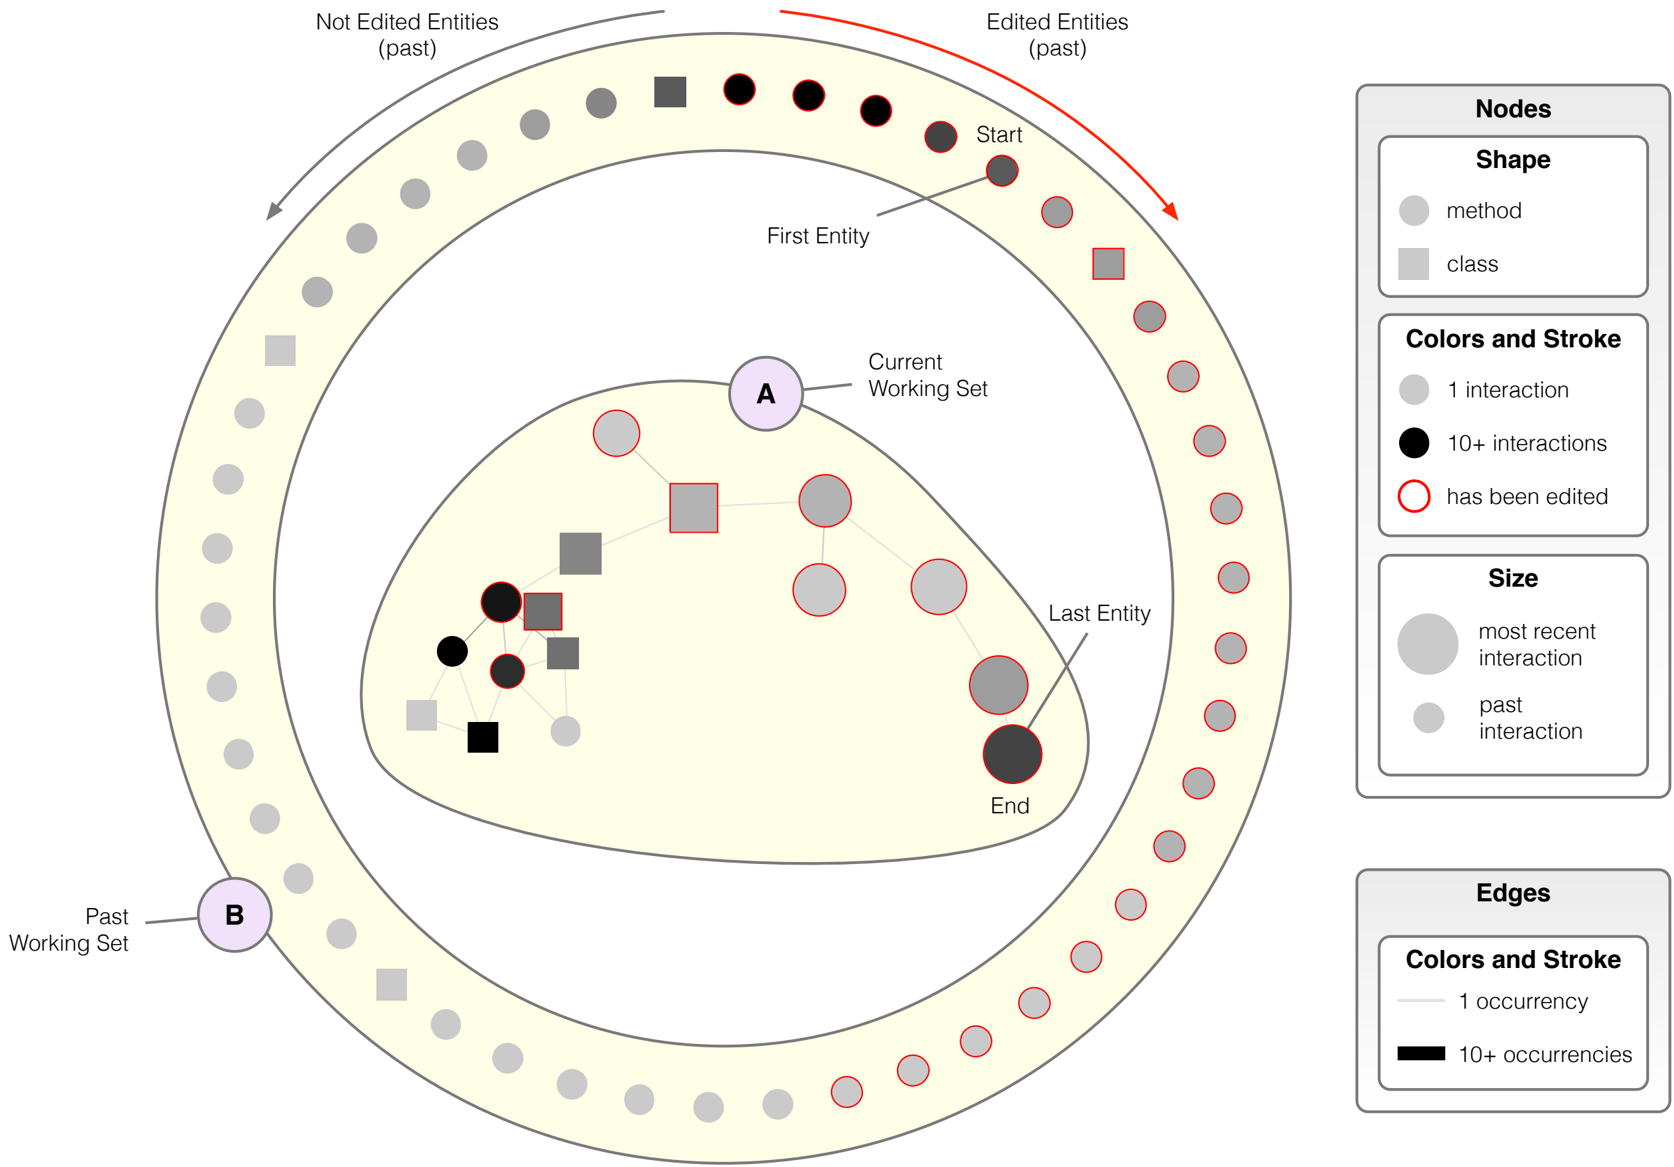
Visualizing the Evolution of Working Sets
As part as their daily work, developers interact with Integrated Development Environments (IDE), generating thousands of events. Together with other aspects of development, this data also captures the modus operandi of the developer, including all the program entities she interacted with during a development session. This \"working set" (or context) is leveraged by developers to create and maintain their mental model of the software system at hand. Understanding how developers navigate and interact with source code during a development session is an open question. We present a novel visual approach to understand how working sets evolve during a development session. The visualization incrementally depicts all the program entities involved in a development session, the intensity of the developer activity on them, and the navigation paths that occurred between them. We visualized more than a thousand development sessions, and categorized them according to their visual properties.
September 2016 1
Mining and Modelling Unstructured Data
31st IEEE/ACM International Conference on Automated Software Engineering (ASE 2016)
August 2016 1
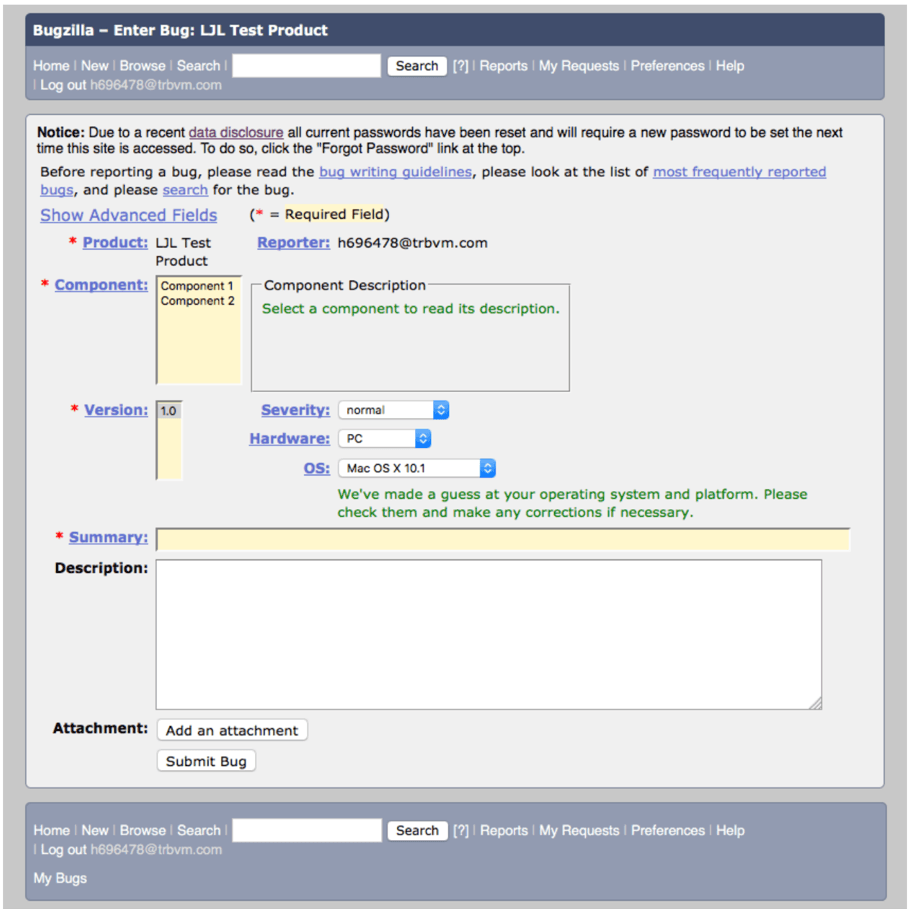
What Makes a Satisficing Bug Report?
To ensure quality of software systems, developers use bug reports to track defects. It is in the interest of users and developers that bug reports provide the necessary information to ease the fixing process. Past research found that users do not provide the information that developers deem ideally useful to fix a bug. This raises an interesting question: What is the satisficing information to speed up the bug fixing process? We conducted an observational study on the relation between provided report information and its lifetime, considering more than 650,000 reports from open-source systems using popular bug trackers. We distilled a meta-model for a minimal bug report, establishing a basic layer of core features. We found that few fields influence the resolution time and that customized fields have little impact on it. We performed a survey to investigate what users deem easy to provide in a bug report.
June 2016 1
May 2016 3
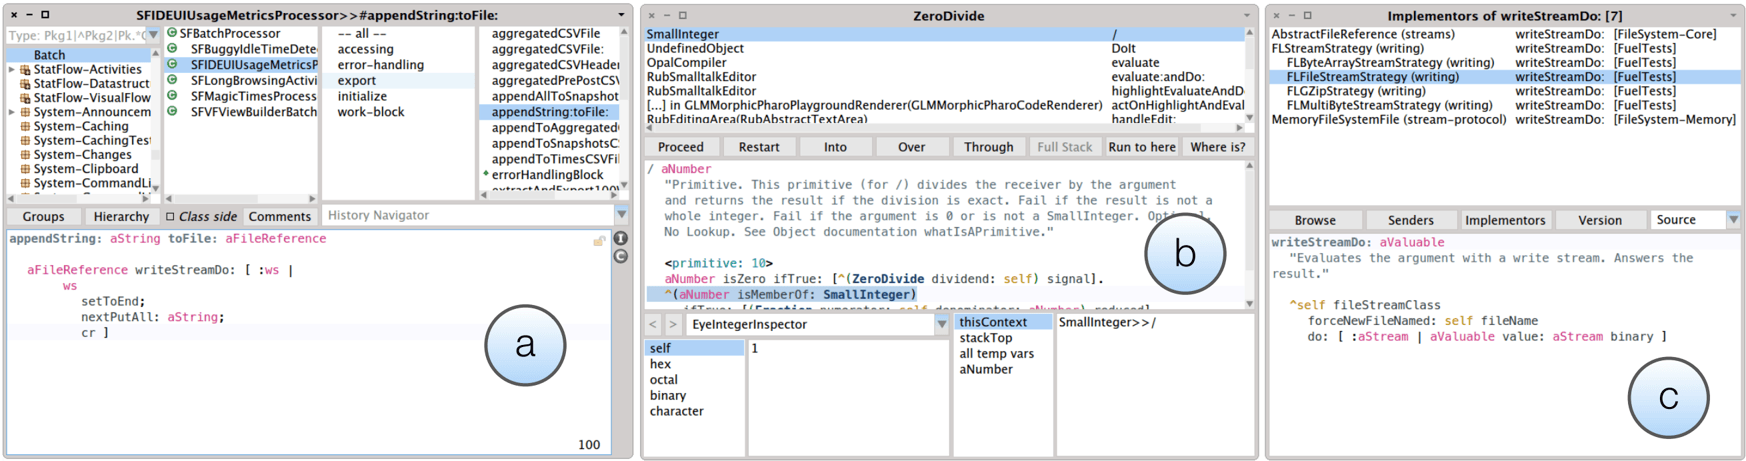
Taming the IDE with Fine-grained Interaction Data
Integrated Development Environments (IDEs) lack effective support to browse complex relationships between source code elements. As a result, developers are often forced to exploit multiple user interface components at the same time, bringing the IDE into a complex, \"chaotic" state. Keeping track of these relationships demands increased source code navigation and cognitive load, leading to productivity deficits documented in observational studies. Beyond small-scale studies, the amount and nature of the chaos experienced by developers in the wild is unclear, and more importantly it is unclear how to tame it. Based on a dataset of fine-grained interaction data, we propose several metrics to characterize and quantify the "level of chaos" of an IDE. Our results suggest that developers spend, on average, more than 30% of their time in a chaotic environment, and that this may affect their productivity. To support developers, we devise and evaluate simple strategies that automatically alter the UI of the IDE. We find that even simple strategies may considerably reduce the level of chaos both in terms of effective space occupancy and time spent in a chaotic environment.
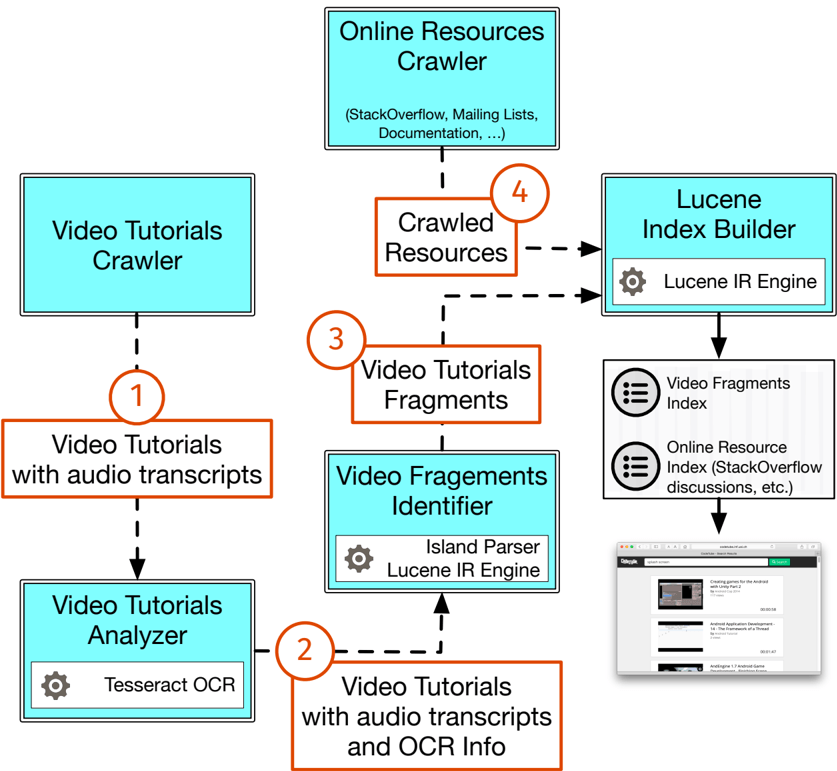
Too Long; Didn't Watch! Extracting Relevant Fragments from Software Development Video Tutorials
When knowledgeable colleagues are not available, developers resort to offline and online resources, e.g. tutorials, mailing lists, and Q&A websites. These, however, need to be found, read, and understood, which takes its toll in terms of time and mental energy. A more immediate and accessible resource are video tutorials found on the web, which in recent years have seen a steep increase in popularity. Nonetheless, videos are an intrinsically noisy data source, and finding the right piece of information might be even more cumbersome than using the previously mentioned resources. We present CodeTube, an approach which mines video tutorials found on the web, and enables developers to query their contents. The video tutorials are split into coherent fragments, to return only fragments related to the query. These are complemented with information from additional sources, such as Stack Overflow discussions. The results of two studies to assess CodeTube indicate that video tutorials - if appropriately processed - represent a useful, yet still under-utilized source of information for software development.
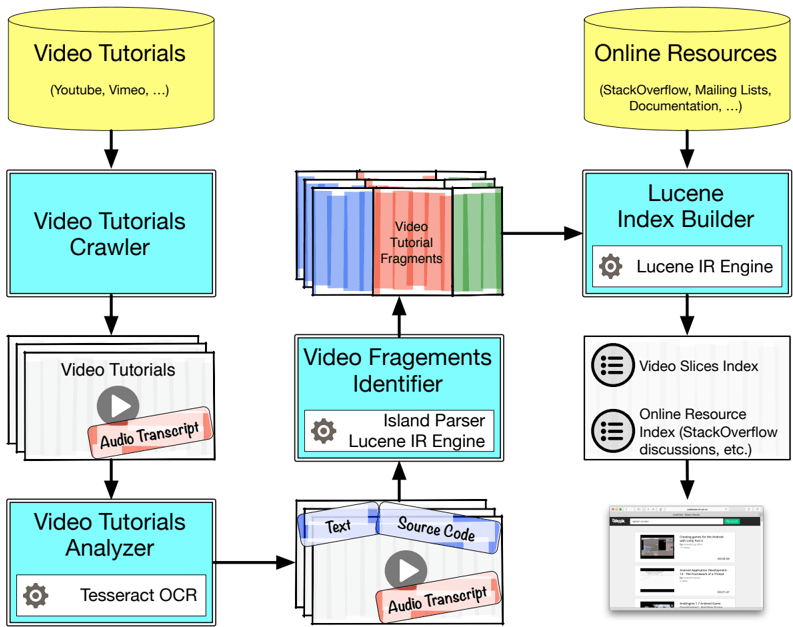
CodeTube: Extracting Relevant Fragments from Software Development Video Tutorials
Nowadays developers heavily rely on sources of informal documentation. Examples include Q&A forums, slides, or video tutorials, the latter being particularly useful to provide introductory notions for a piece of technology. The current practice is that developers have to browse sources individually, which in the case of video tutorials is cumbersome, as they are lengthy and cannot be searched based on their contents. We present CodeTube, a Web-based recommender system that analyzes the contents of video tutorials and is able to provide, given a query, cohesive and self-contained video fragments, along with links to relevant Stack Overflow discussions. CodeTube relies on a combination of textual analysis and image processing applied on video tutorial frames and speech transcripts to split videos into cohesive fragments, index them and identify related Stack Overflow discussions.
March 2016 2
Measuring Navigation Efficiency in the IDE
While coding, developers construct and maintain mental models of software systems to support the task at hand. Although source code is the main product of software development, the process involves navigating and inspecting entities beyond the ones that are edited by the end of a task. Developers use various user interfaces (UI) offered by the Integrated Development Environment (IDE) to navigate the complex, and often hidden, relationships between program entities. These UIs impose fixed navigation costs, in terms of the number of interactions that a developer is required to perform to reach an entity of interest. It is unclear to what extent the actual navigation effort differs from an ideal setting, and if there is any room for actual improvement. We present a preliminary empirical study, where we analyzed a corpus of IDE interaction data coming from 6 developers totaling more than 20 days of development activity. To measure the navigation efficiency, we compute a combination of different ideal settings and compare them against the observed navigation events. Our findings reveal that, on average, developers perform 1.5 to 19 times more navigation events than the ideal case. While different factors make the ideal setting unfeasible, we believe that this calls for novel approaches to support the navigation in integrated development environments.
December 2015 2
Software Atelier 1: Fundamentals of Informatics (2015)
The first of the ateliers, which are a crucial part of our Bachelor curriculum is roughly divided into three main pieces. On the one hand the students will obtain first-hand experience with a variety of tools of the trade, such as LaTeX, HTML, Versioning, and the unix shell. Second, the students will get an overview of the history of computer science since its very beginning up to the present day. The third part of the atelier is dedicated to a group project, in which students will put into practice what they learned in the course.
Software Engineering (2015)
Software engineering is the discipline of engineering large software systems, that is developing software systems that are available in multiple versions and whose design, development and maintenance involve multiple people. Modern software engineering requires to manage methods, tools and techniques to develop systems on time and on schedule. The course provides the fundamental skills to engineer large software systems, manage a software process, elicit, specify and analyze software requirements, architect and design dependable and maintainable software, validate and verify software systems.
October 2015 1
Use at Your Own Risk: The Java Unsafe API in the Wild
Java is a safe language. Its runtime environment provides strong safety guarantees that any Java application can rely on. Or so we think. We show that the runtime actually does not provide these guarantees—for a large fraction of today's Java code. Unbeknownst to many application developers, the Java runtime includes a \"backdoor" that allows expert library and framework developers to circumvent Java's safety guarantees. This backdoor is there by design, and is well known to experts, as it enables them to write high-performance systems-level code in Java. For much the same reasons that safe languages are preferred over unsafe languages, these powerful but unsafe capabilities in Java should be restricted. They should be made safe by changing the language, the runtime system, or the libraries. At the very least, their use should be restricted. This paper is a step in that direction. We analyzed 74 GB of compiled Java code, spread over 86,479 Java archives, to determine how Java’s unsafe capabilities are used in real-world libraries and applications. We found that 25% of Java bytecode archives depend on un- safe third-party Java code, and thus Java's safety guarantees cannot be trusted. We identify 14 different usage patterns of Java’s unsafe capabilities, and we provide supporting evidence for why real-world code needs these capabilities. Our long-term goal is to provide a foundation for the design of new language features to regain safety in Java.
September 2015 3
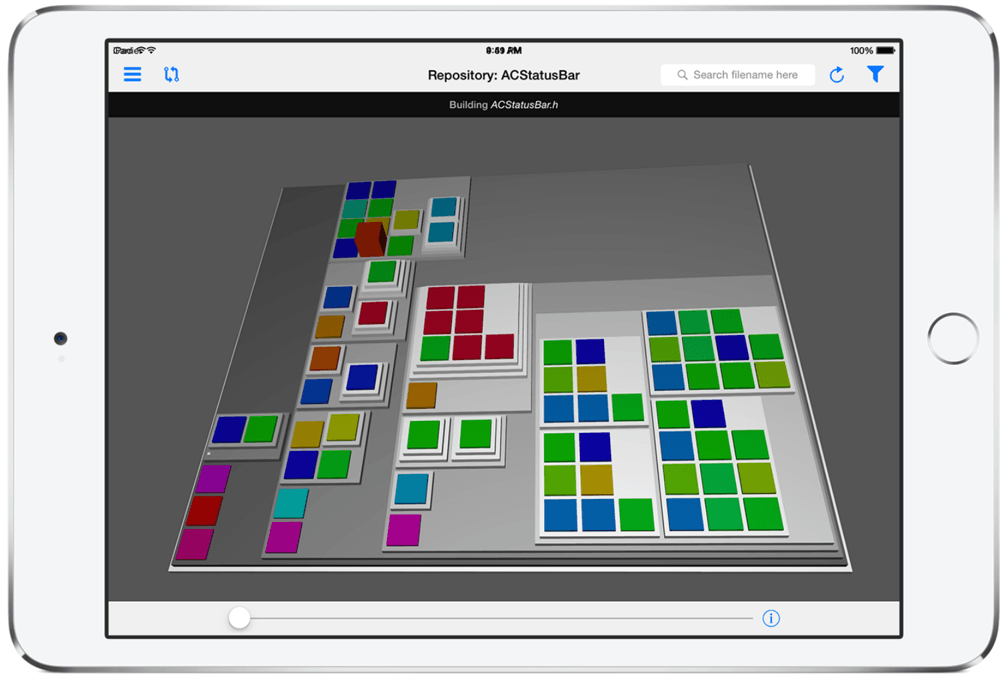
UrbanIt: Visualizing Repositories Everywhere
Software evolution is supported by a variety of tools that help developers understand the structure of a software system, analyze its history and support specific classes of analyses. However, the increasingly distributed nature of software development requires basic repository analyses to be always available to developers, even when they cannot access their workstation with full-fledged applications and command-line tools. We present UrbanIt, a gesture-based tablet application for the iPad that supports the visualization of software repositories together with useful evolutionary analyses (e.g., version diff) and basic sharing features in a portable and mobile setting. UrbanIt is paired with a web application that manages synchronization of multiple repositories.
SODA: The Stack Overflow Dataset Almanac
Stack Overflow has become a fundamental resource for developers, becoming the de facto Question and Answer (Q&A) website, and one of the standard unstructured data sources for software engineering research to mine knowledge about development. We present SODA, the Stack Overflow Dataset Almanac, a tool that helps researchers and developers to better understand the trends of discussion topics in Stack Overflow, based on the available tagging system. SODA provides an effective visualization to support the analysis of topics in different time intervals and frames, leveraging single or co-occurrent tags. We show, through simple usage scenarios, how SODA can be used to find interesting peculiar moments in the evolution of Stack Overflow discussions that closely match specific recent events in the area of software development. SODA is available at http://rio.inf.usi.ch/soda/
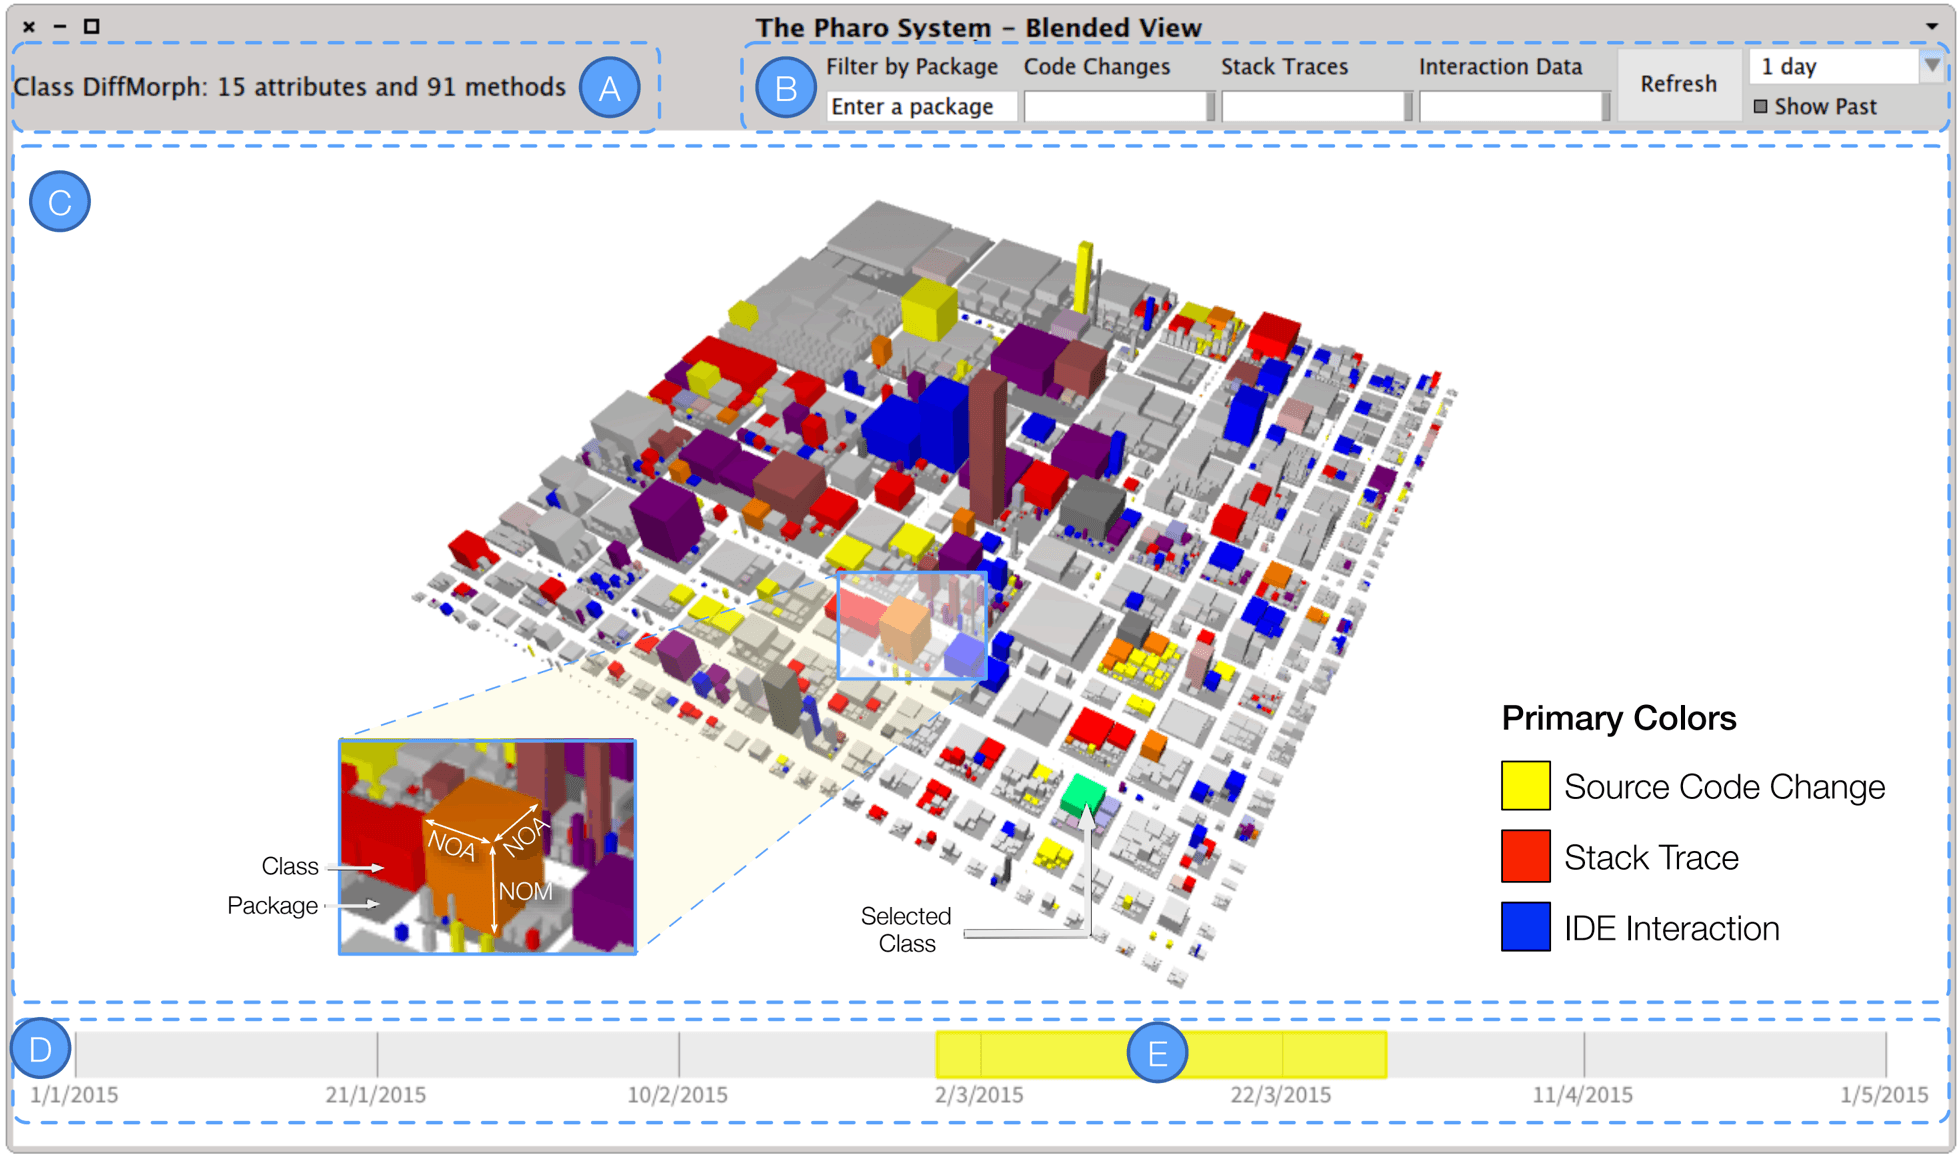
Blended, Not Stirred: Multi-concern Visualization of Large Software Systems
While constructing and evolving software systems, developers generate directly and indirectly a large amount of data of diverse nature, such as source code changes, bug tracking information, IDE interactions, stack traces, etc. Often these diverse data sources are processed and visualized in isolation, leading to a partial view of systems. We present a blended approach to visualize several data \"ingredients" at once, to give as complete an answer as possible to the question "What happened to the system in the last few days?". The goal is to enable a quick and comprehensive assessment of what happened to a software system in any given time frame.
May 2015 9
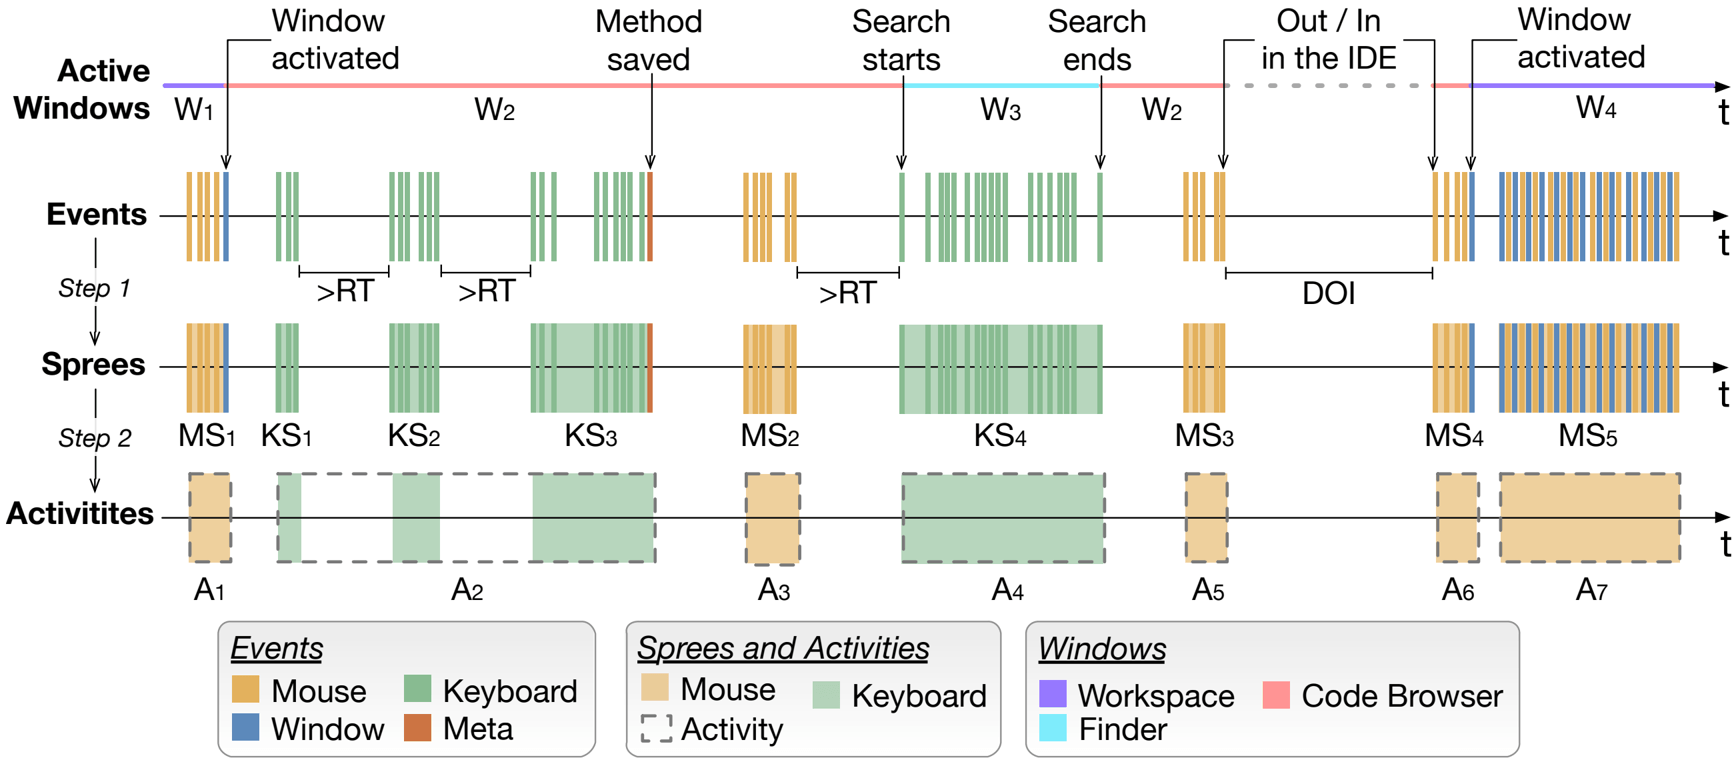
I Know What You Did Last Summer -- An Investigation of How Developers Spend Their Time
Developing software is a complex mental activity, requiring extensive technical knowledge and abstraction capabilities. The tangible part of development is the use of tools to read, inspect, edit, and manipulate source code, usually through an IDE (integrated development environment). Common claims about software development include that program comprehension takes up half of the time of a developer, or that certain UI (user interface) paradigms of IDEs offer insufficient support to developers. Such claims are often based on anecdotal evidence, throwing up the question of whether they can be corroborated on more solid grounds. We present an in-depth analysis of how developers spend their time, based on a fine-grained IDE interaction dataset consisting of ca. 740 development sessions by 18 developers, amounting to 200 hours of development time and 5 million of IDE events. We propose an inference model of development activities to precisely measure the time spent in editing, navigating and searching for artifacts, interacting with the UI of the IDE, and performing corollary activities, such as inspection and debugging. We report several interesting findings which in part confirm and reinforce some common claims, but also disconfirm other beliefs about software development.
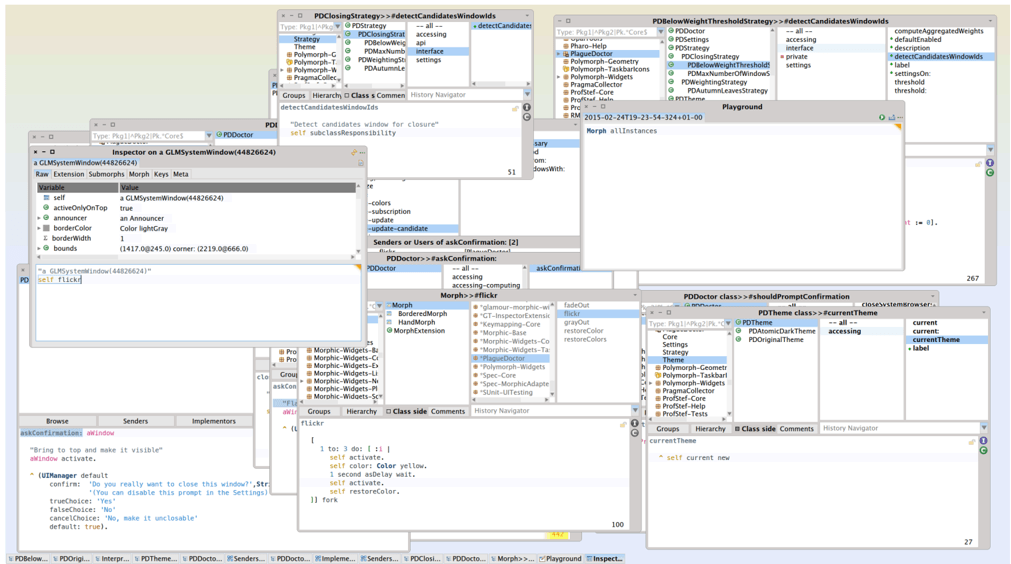
The Plague Doctor: A Promising Cure for the Window Plague
Modern Integrated Development Environments (IDEs) are often affected by the \"window plague", an overly crowded workspace with many open windows and tabs. The main cause is the lack of navigation support in IDEs, also due to the many - and not always obvious - complex relationships that exist between program entities. Researchers have shown that it is possible to mitigate the window plague by exploiting the data obtained by monitoring how developers interact with the user interface of the IDE. However, despite initial results the approach was never fully integrated in an IDE. In our previous work, we implemented DFLOW, an automatic interaction profiler that monitors all the fine-grained interactions of the developer with the IDE. Here we present a first prototype of the PLAGUE DOCTOR, a tool that seamlessly detects the windows that are less likely to be used in the future and automatically closes them. We discuss our long term vision on how to fully exploit the interaction data recorded by DFLOW to provide a more effective cure for the window plague.
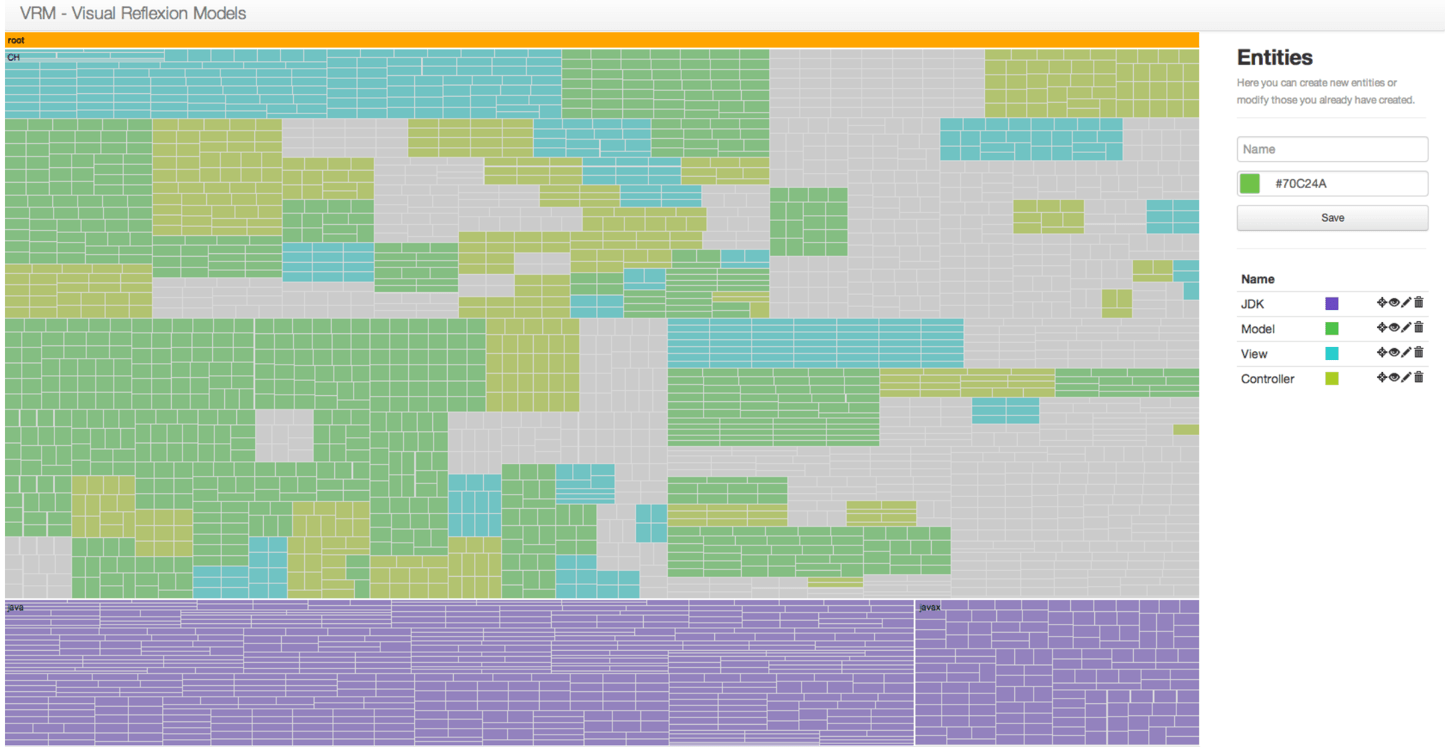
Towards Visual Reflexion Models
Source code and models of a software system, like architectural views, tend to evolve separately and drift apart over time. Previous research has shown that it is possible to effectively relate them through a reflexion model, defined as a \"summarization of a software system from the viewpoint of a particular high-level model". While effective, the process of constructing and analyzing reflexion models was supported by text-based tools with limited visual representation. With the original approach, it was relatively hard to understand which parts of the system were represented, and which parts of the system contributed to specific relations in the reflexion model. We present our vision on augmenting the construction and analysis of reflexion models with visual support, effectively providing the basis for visual reflexion models. We describe our approach, implemented as a web-based application, and two promising case studies involving two open-source projects.
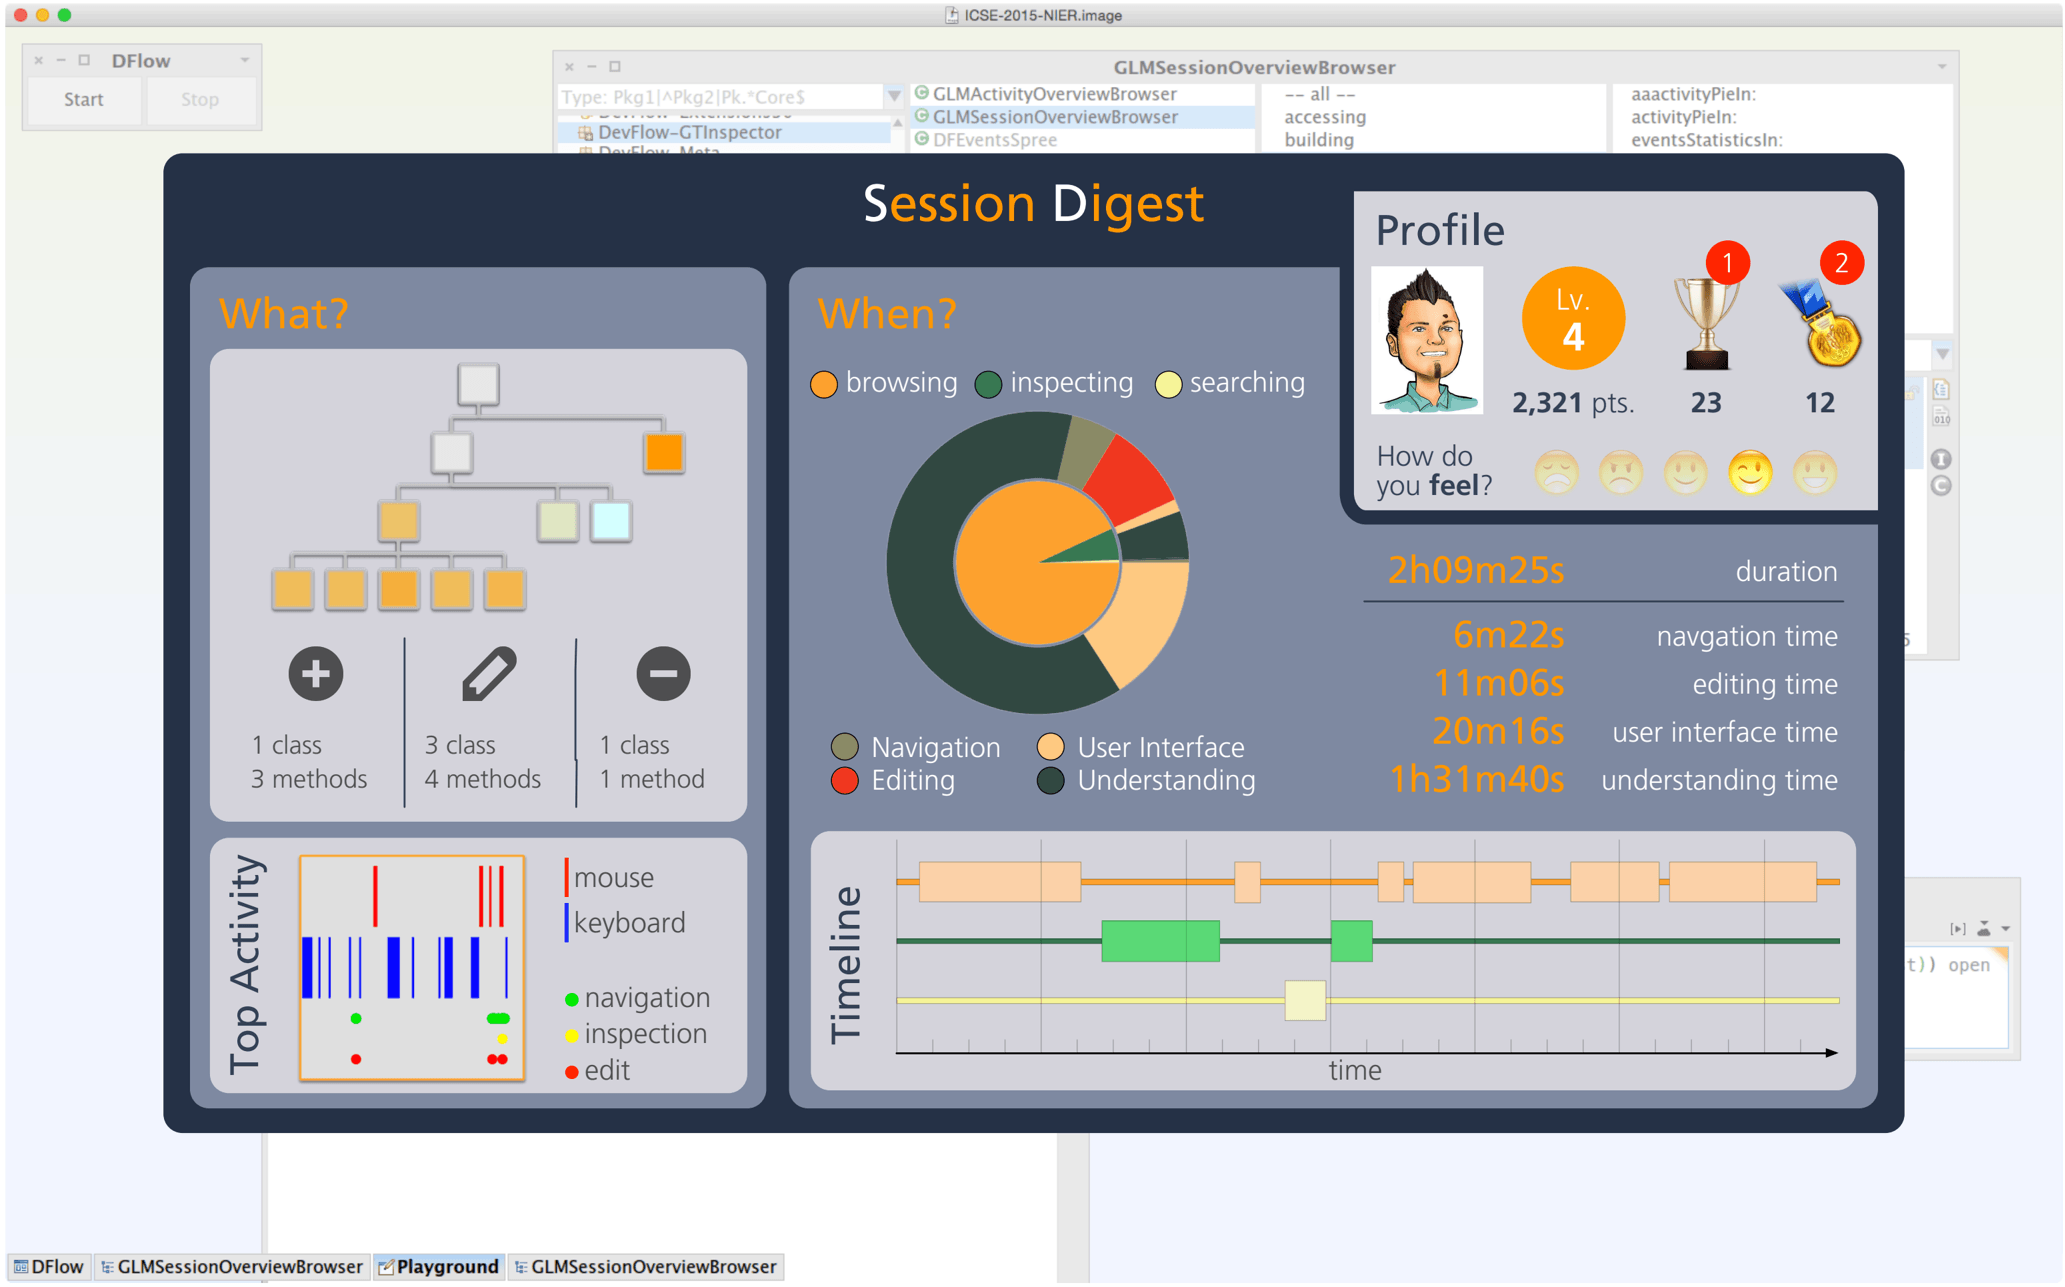
Free Hugs: Praising Developers For Their Actions
Developing software is a complex, intrinsically intellectual, and therefore ephemeral activity, also due to the intangible nature of the end product, the source code. There is a thin red line between a productive development session, where a developer actually does something useful and productive, and a session where the developer essentially produces “fried air”, pieces of code whose quality and usefulness are doubtful at best. We believe that well-thought mechanisms of gamification built on fine-grained interaction information mined from the IDE can crystallize and reward good coding behavior. We present our preliminary experience with the design and implementation of a micro-gamification layer built into an object-oriented IDE, which at the end of each development session not only helps the developer to understand what he actually produced, but also praises him in case the development session was productive. Building on this, we envision an environment where the IDE reflects on the deeds of the developers and by providing a historical view also helps to track and reward long-term growth in terms of development skills, not dissimilar from the mechanics of role-playing games.
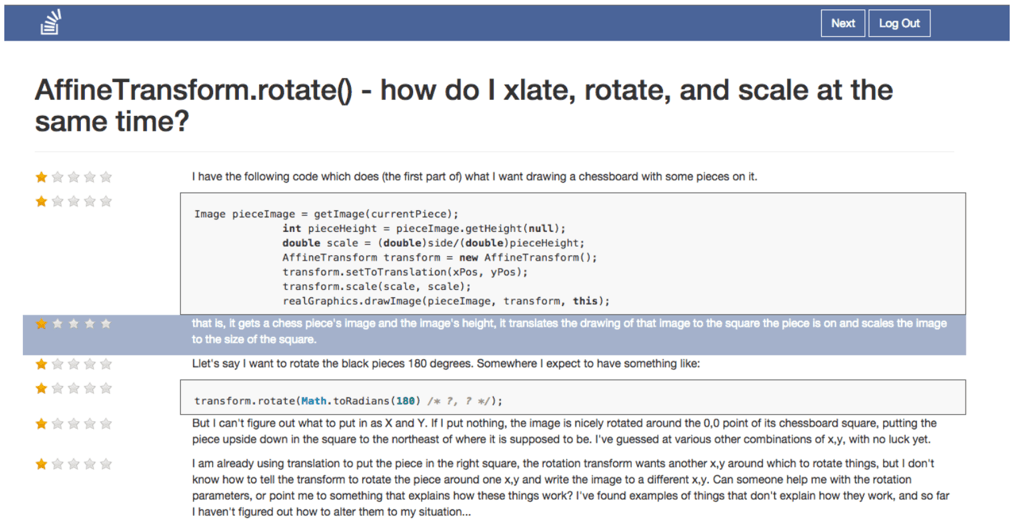
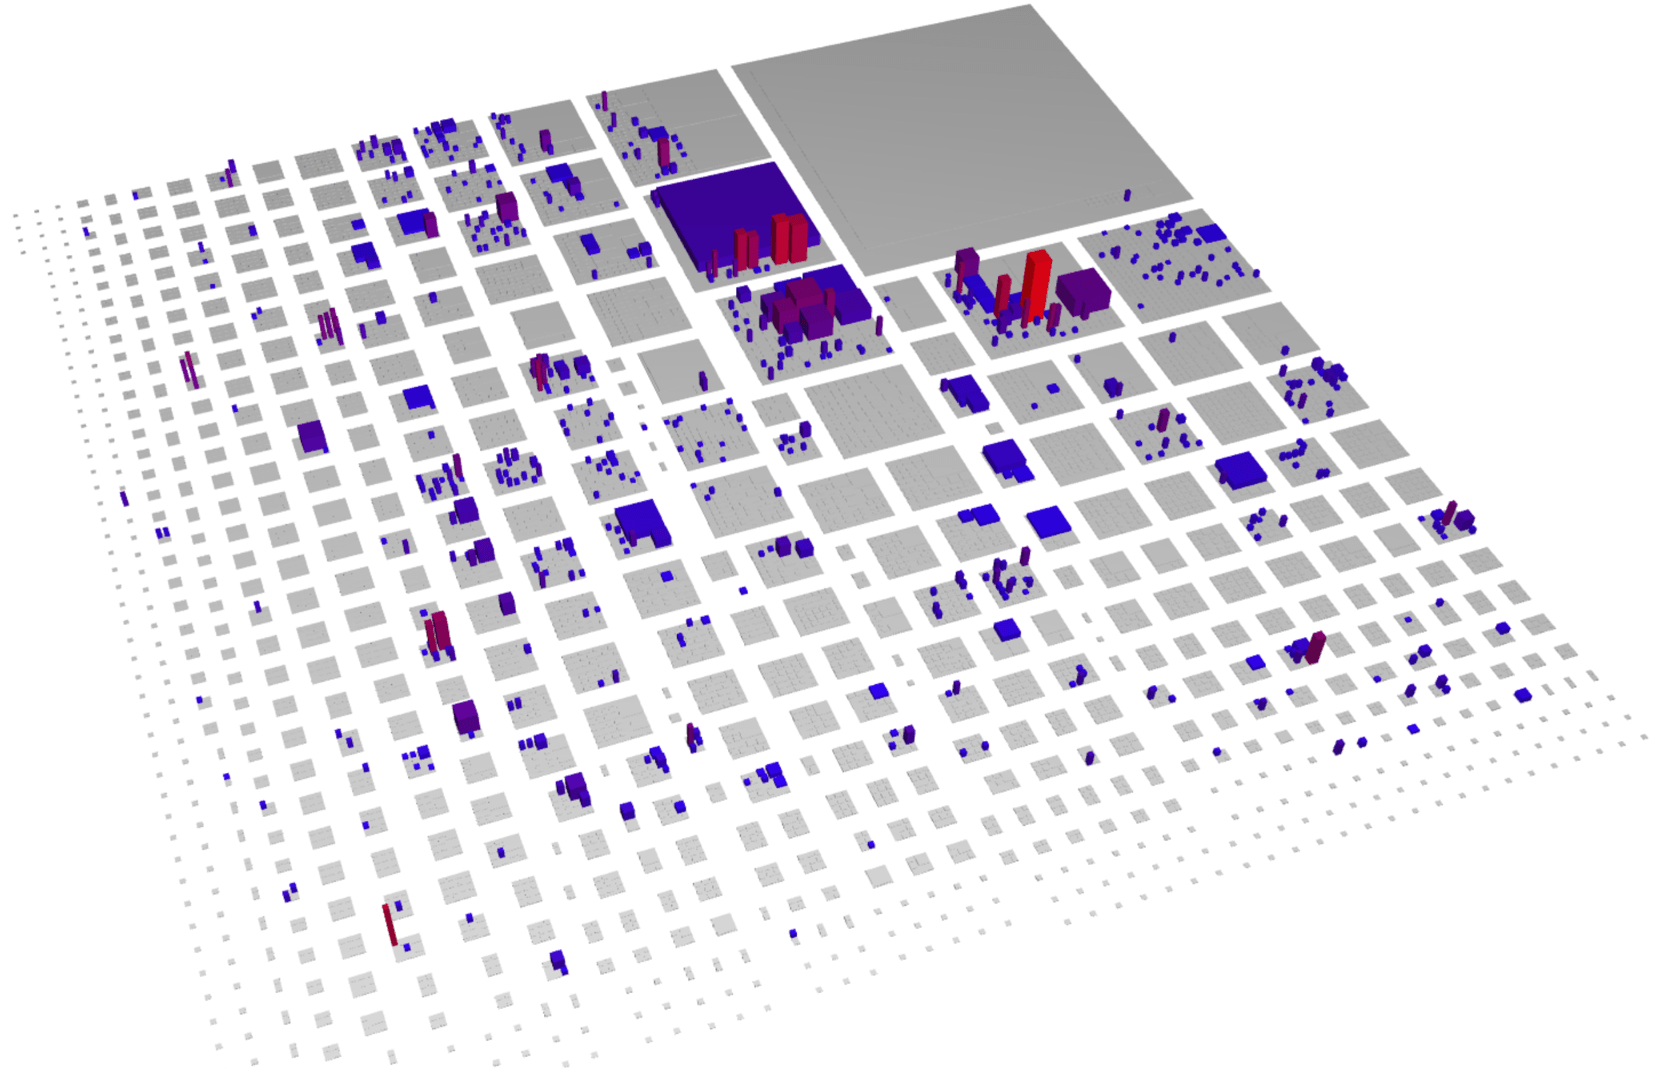
StORMeD: Stack Overflow Ready Made Data
Stack Overflow is the de facto Question and Answer (Q&A) website for developers, and it has been used in many approaches by software engineering researchers to mine useful data. However, the contents of a Stack Overflow discussion are inherently heterogeneous, mixing natural language, source code, stack traces and configuration files in XML or JSON format. We constructed a full island grammar capable of modeling the set of 700,000 Stack Overflow discussions talking about Java, building a heterogeneous abstract syntax tree (H-AST) of each post (question, answer or comment) in a discussion. The resulting dataset models every Stack Overflow discussion, providing a full H-AST for each type of structured fragment (i.e., JSON, XML, Java, Stack traces), and complementing this information with a set of basic meta-information like term frequency to enable natural language analyses. Our dataset allows the end-user to perform combined analyses of the Stack Overflow by visiting the H-AST of a discussion.
Summarizing Complex Development Artifacts by Mining Heterogeneous Data
Summarization is hailed as a promising approach to reduce the amount of information that must be taken in by the person who wants to understand development artifacts, such as pieces of code, bug reports, emails, etc. However, existing approaches treat artifacts as pure textual entities, disregarding the heterogeneous and partially structured nature of most artifacts, which contain intertwined pieces of distinct type, such as source code, diffs, stack traces, human language, etc. We present a novel approach to augment existing summarization techniques (such as LexRank) to deal with the heterogeneous and multidimensional nature of complex artifacts. Our preliminary results on heterogeneous artifacts suggest our approach outperforms the current text-based approaches.
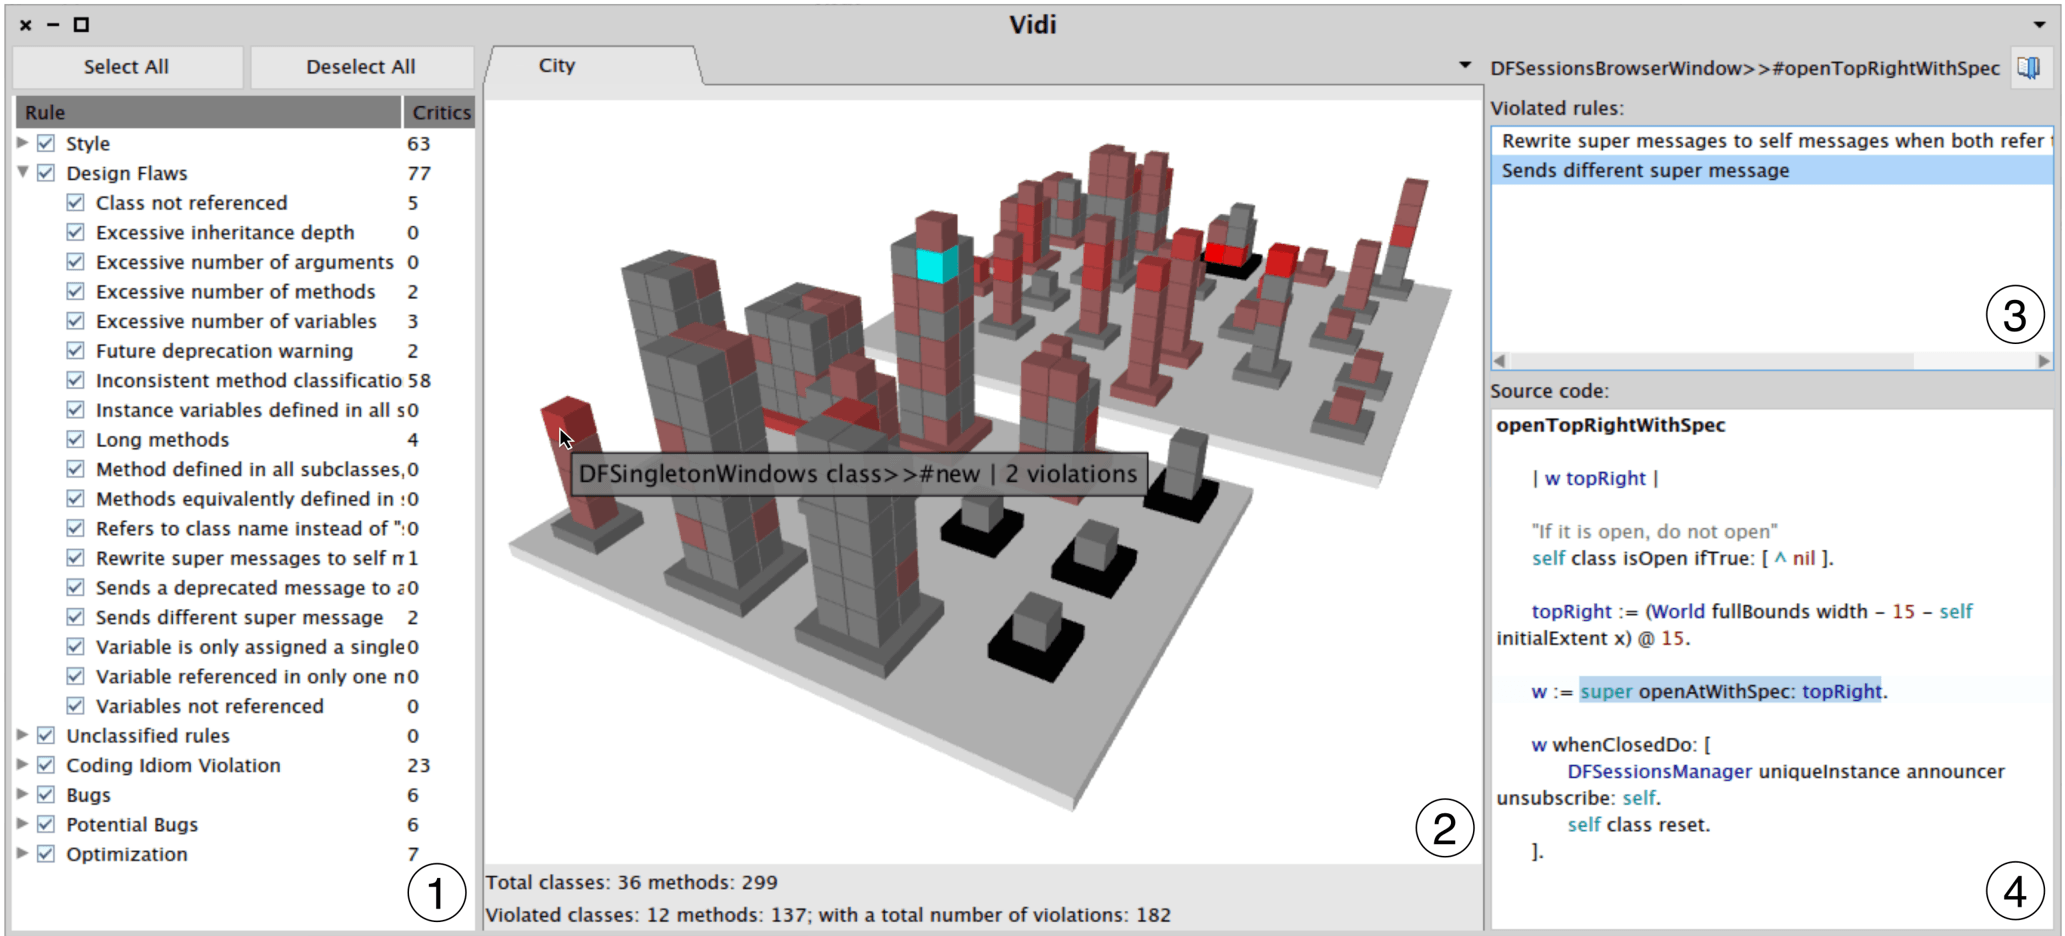
ViDI: The Visual Design Inspector
We present ViDI (Visual Design Inspector), a novel code review tool which focuses on quality concerns and design inspection as its cornerstones. It leverages visualization techniques to represent the reviewed software and augments the visualization with the results of quality analysis tools. To effectively understand the contribution of a reviewer in terms of the impact of her changes on the overall system quality, ViDI supports the recording and further inspection of reviewing sessions. ViDI is an advanced prototype which we will soon release to the Pharo open-source community.
StORMeD
Heterogeneous abstract syntax trees for Stack Overflow: a Scala development kit, a ready-made JSON dataset, and an island-parsing web service
March 2015 3
Misery Loves Company - CrowdStacking Traces to Aid Problem Detection
During software development, exceptions are by no means exceptional: Programmers repeatedly try and test their code to ensure that it works as expected. While doing so, runtime exceptions are raised, pointing out various issues, such as inappropriate usage of an API, convoluted code, as well as defects. Such failures result in stack traces, lists composed of the sequence of method invocations that led to the interruption of the program. Stack traces are useful to debug source code, and if shared also enhance the quality of bug reports. However, they are handled manually and individually, while we argue that they can be leveraged automatically and collectively to enable what we call crowdstacking, the automated collection of stack traces on the scale of a whole development community. We present our crowdstacking approach, supported by Shore-Line Reporter, a tool which seamlessly collects stack traces during program development and execution and stores them on a central repository. We illustrate how thousands of stack traces stemming from the IDEs of several developers can be leveraged to identify common hot spots in the code that are involved in failures, using this knowledge to retrieve relevant and related bug reports and to provide an effective, instant context of the problem to the developer.
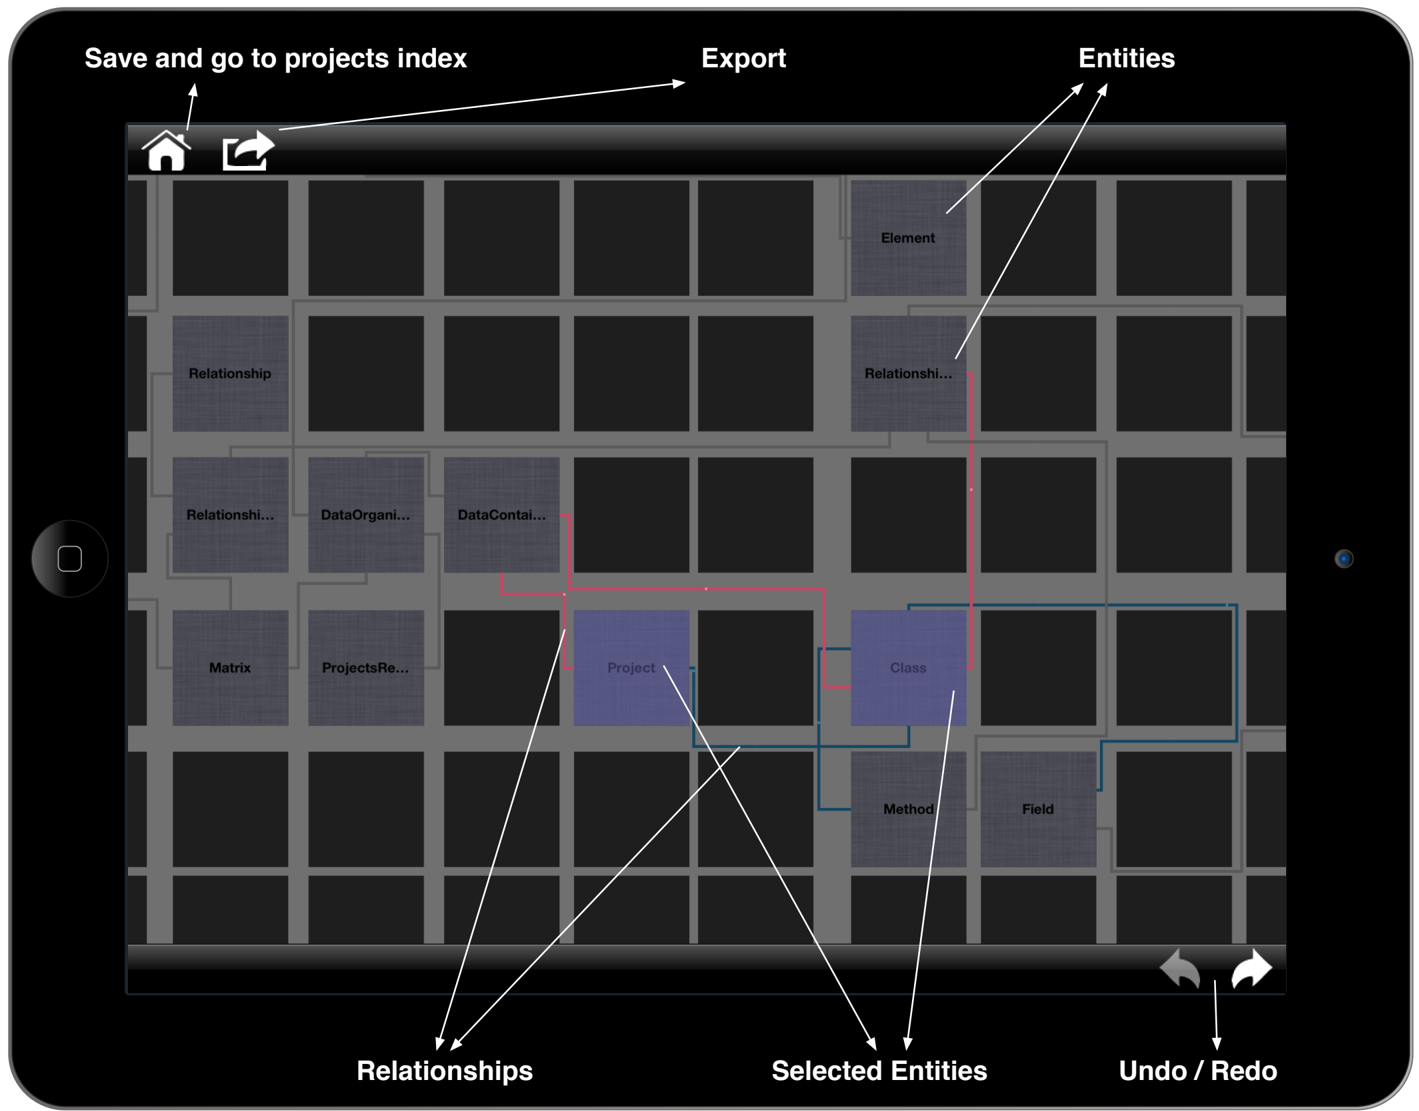
CEL - Touching Software Modeling in Essence
Understanding a problem domain is a fundamental prerequisite for good software design. In object-oriented systems design, modeling is the fundamental first phase that focuses on identifying core concepts and their relations. How to properly support modeling is still an open problem, and existing approaches and tools can be very different in nature. On the one hand, lightweight ones, such as pen & paper/whiteboard or CRC cards, are informal and support well the creative aspects of modeling, but produce artifacts that are difficult to store, process and reuse as documentation. On the other hand, more constrained and semi-formal ones, like UML, produce storable and processable structured artifacts with defined semantics, but this comes at the expense of creativity. We believe there exists a middle ground to investigate that maximizes the good of both worlds, that is, by supporting software modeling closer to its essence, with minimal constraints on the developer's creativity and still producing reusable structured artifacts. We also claim that modeling can be best treated by using the emerging technology of touch-based tablets. We present a novel gesture-based modeling approach based on a minimal set of constructs, and CEL, an iPad application, for rapidly creating, manipulating, and storing language agnostic object-oriented software models, which can be exported as skeleton source code in any language of choice. We assess our approach through a controlled qualitative study.
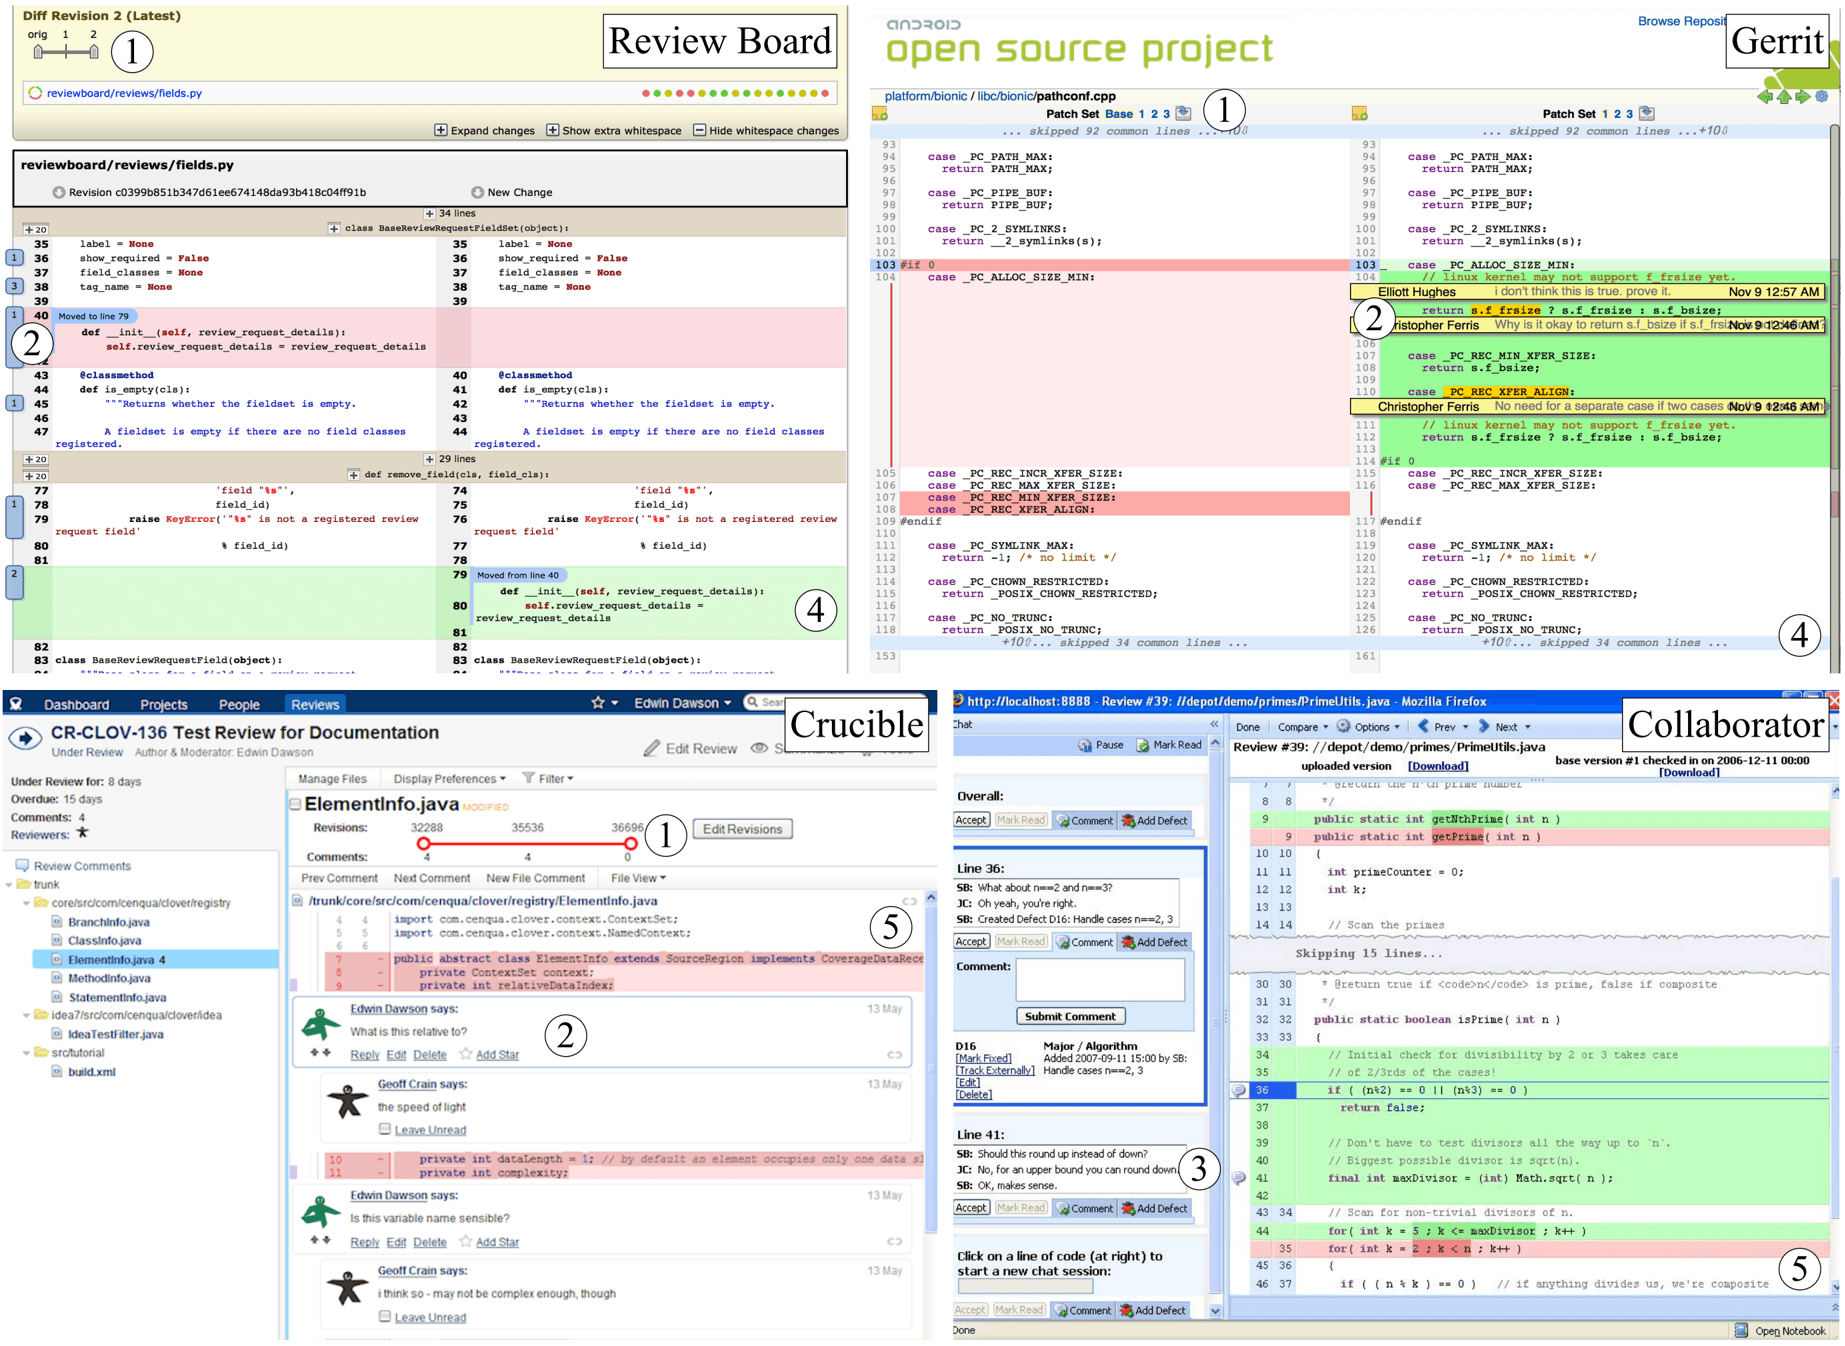
Code Review: Veni, ViDI, Vici
Modern software development sees code review as a crucial part of the process, because not only does it facilitate the sharing of knowledge about the system at hand, but it may also lead to the early detection of defects, ultimately improving the quality of the produced software. Although supported by numerous approaches and tools, code review is still in its infancy, and indeed researchers have pointed out a number of shortcomings in the state of the art. We present a critical analysis of the state of the art of code review tools and techniques, extracting a set of desired features that code review tools should possess. We then present our vision and initial implementation of a novel code review approach named Visual Design Inspection (ViDI), illustrated through a set of usage scenarios. ViDI is based on a combination of visualization techniques, design heuristics, and static code analysis techniques.
December 2014 2
Software Atelier 1: Fundamentals of Informatics (2014)
The first of the ateliers, which are a crucial part of our Bachelor curriculum is roughly divided into three main pieces. On the one hand the students will obtain first-hand experience with a variety of tools of the trade, such as LaTeX, HTML, Versioning, and the unix shell. Second, the students will get an overview of the history of computer science since its very beginning up to the present day. The third part of the atelier is dedicated to a group project, in which students will put into practice what they learned in the course.
Software Engineering (2014)
Software engineering is the discipline of engineering large software systems, that is developing software systems that are available in multiple versions and whose design, development and maintenance involve multiple people. Modern software engineering requires to manage methods, tools and techniques to develop systems on time and on schedule. The course provides the fundamental skills to engineer large software systems, manage a software process, elicit, specify and analyze software requirements, architect and design dependable and maintainable software, validate and verify software systems.
October 2014 3
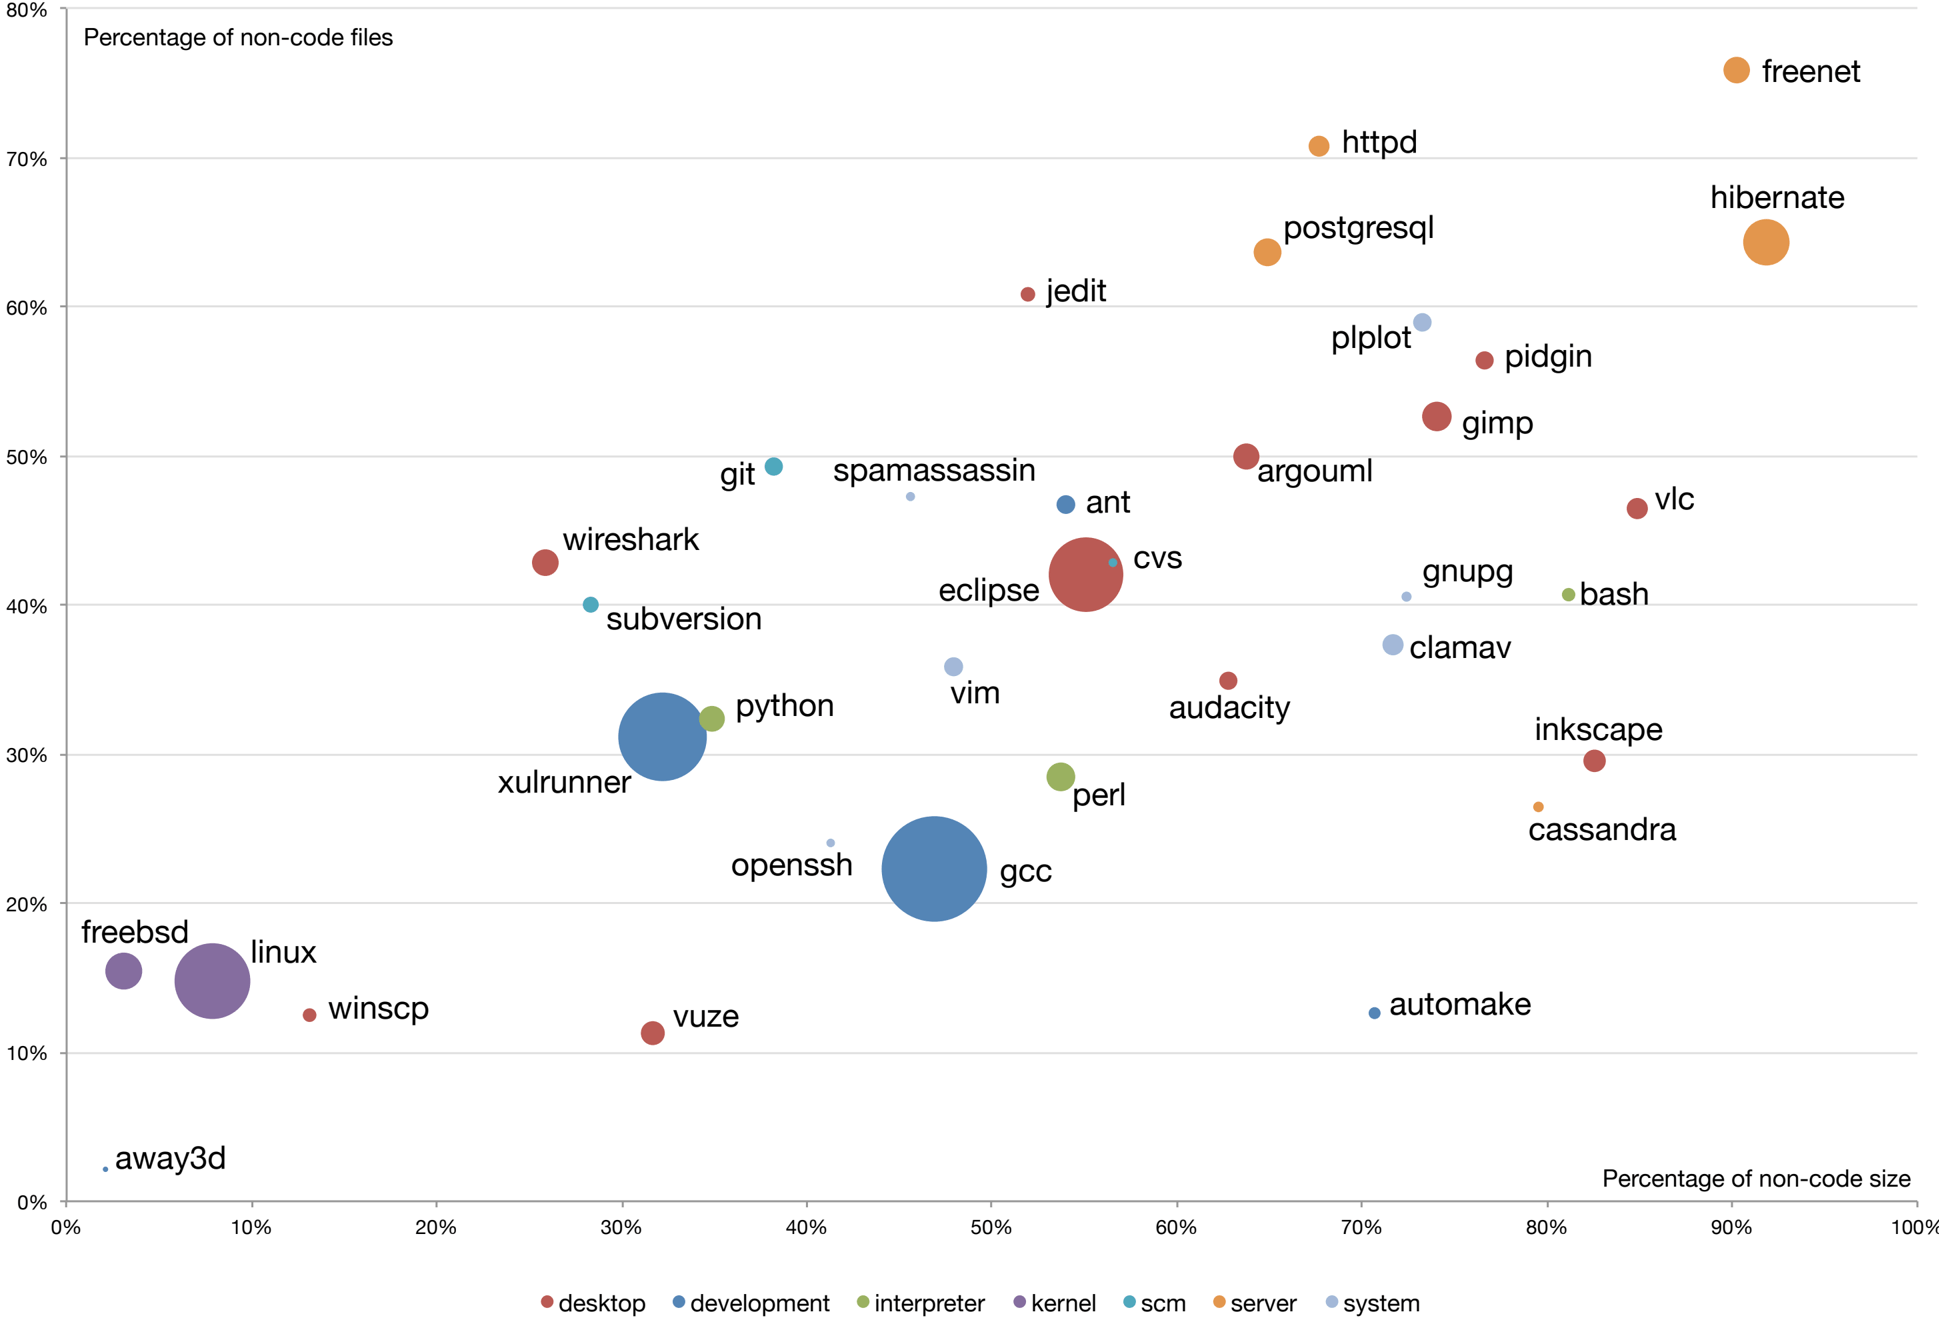
Quantitatively Exploring Non-code Software Artifacts
Most software engineering research focuses its analyses on source code, because correct, well designed, and efficient program code is the desired end output of software development. Nevertheless, source code is not the only constituent of software systems: Programs also comprise other types of artifacts, such as documentation, build system and configuration files, and graphics. These non-code artifacts only recently got the attention of researchers and are not yet investigated as a whole, but separately and with very specific aims. By taking a quantitative perspective, we look into non-code software artifacts to measure their role in software systems. We analyze 35 mature open-source software systems and we address exploratory questions such as: How many non-code software artifacts do software systems contain? How do they relate to source code? How much effort is put into producing and maintaining them? Our results show that a significant portion of systems is made of non-code artifacts, and that programmers spend a relevant part of their effort on non-code artifacts during the development process. Our analysis opens questions for future investigations.
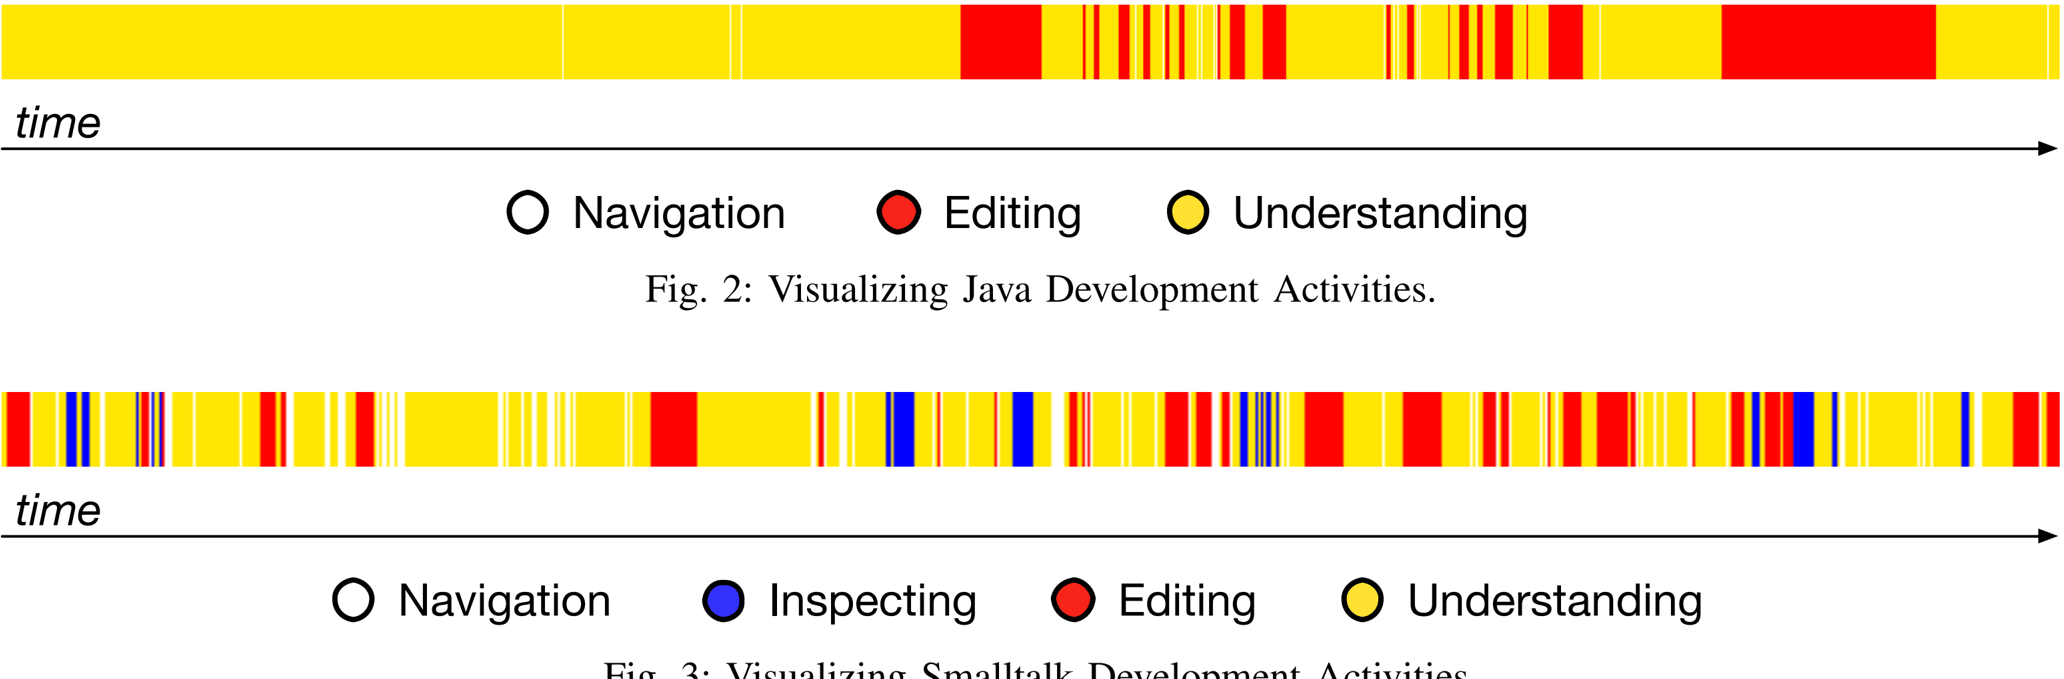
Quantifying Program Comprehension with Interaction Data
It is common knowledge that program comprehension takes up a substantial part of software development. This \"urban legend" is based on work that dates back decades, which throws up the question whether the advances in software development tools, techniques, and methodologies that have emerged since then may invalidate or confirm the claim. We present an empirical investigation which goal is to confirm or reject the claim, based on interaction data which captures the user interface activities of developers. We use interaction data to empirically quantify the distribution of different developer activities during software development: In particular, we focus on estimating the role of program comprehension. In addition, we investigate if and how different developers and session types influence the duration of such activities. We analyze interaction data from two different contexts: One comes from the ECLIPSE IDE on Java source code development, while the other comes from the PHARO IDE on Smalltalk source code development. We found evidence that code navigation and editing occupies only a small fraction of the time of developers, while the vast majority of the time is spent on reading & understanding source code. In essence, the importance of program comprehension was significantly underestimated by previous research.
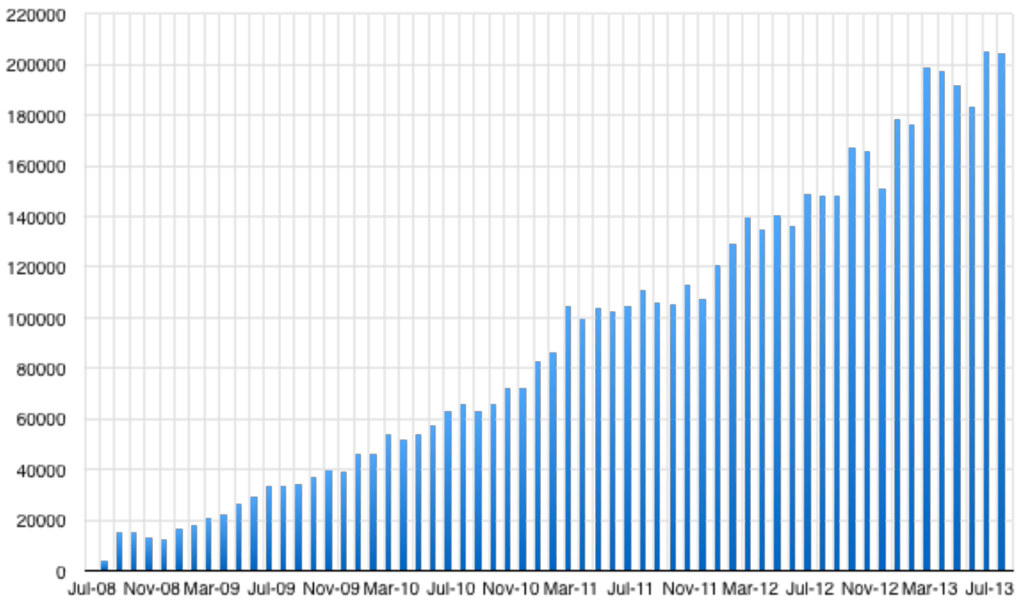
Understanding and Classifying the Quality of Technical Forum Questions
Technical questions and answers (Q&A) services have become a valuable resource for developers. A prominent example of technical Q&A website is StackOverflow (SO), which relies on a growing community of more than two millions of users who actively contribute by asking questions and providing answers. To maintain the value of this resource, poor quality questions - among the more than 6,000 asked daily - have to be filtered out. Currently, poor quality questions are manually identified and reviewed by selected users in SO, this costs considerable time and effort. Automating the process would save time and unload the review queue, improving the efficiency of SO as a resource for developers. We present an approach to automate the classification of questions according to their quality. We present an empirical study that investigates how to model and predict the quality of a question by considering as features both the contents of a post (e.g., from simple textual features to more complex readability metrics) and community-related aspects (e.g., popularity of a user in the community). Our findings show that there is indeed the possibility of at least a partial automation of the costly SO review process.
September 2014 3
Visualizing Developer Interactions
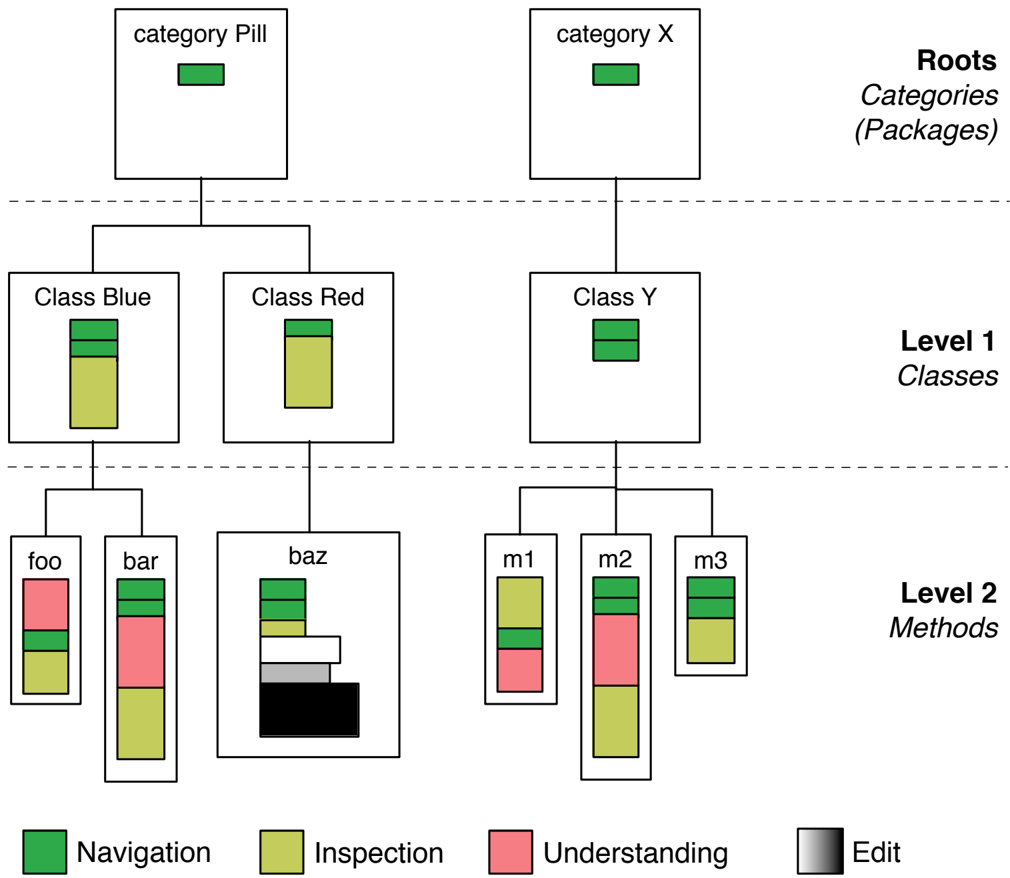
Integrated Development Environments (IDEs) have become the de facto standard vehicle to develop software systems. The user interface (UI) of an IDE offers a staggering amount of facilities to manipulate source code, such as inspectors, debuggers, recommenders, alternative viewers, etc. It is unclear how developers use the UI of an IDE and whether such UIs actually give appropriate support to the developers. We present a visual approach to understand and characterize development sessions from the UI perspective. The tool supporting our approach mines and processes the finest-grained UI-level events making up development sessions and presents them visually. We have collected, visualized, and analyzed hundreds of development sessions and report on our findings.
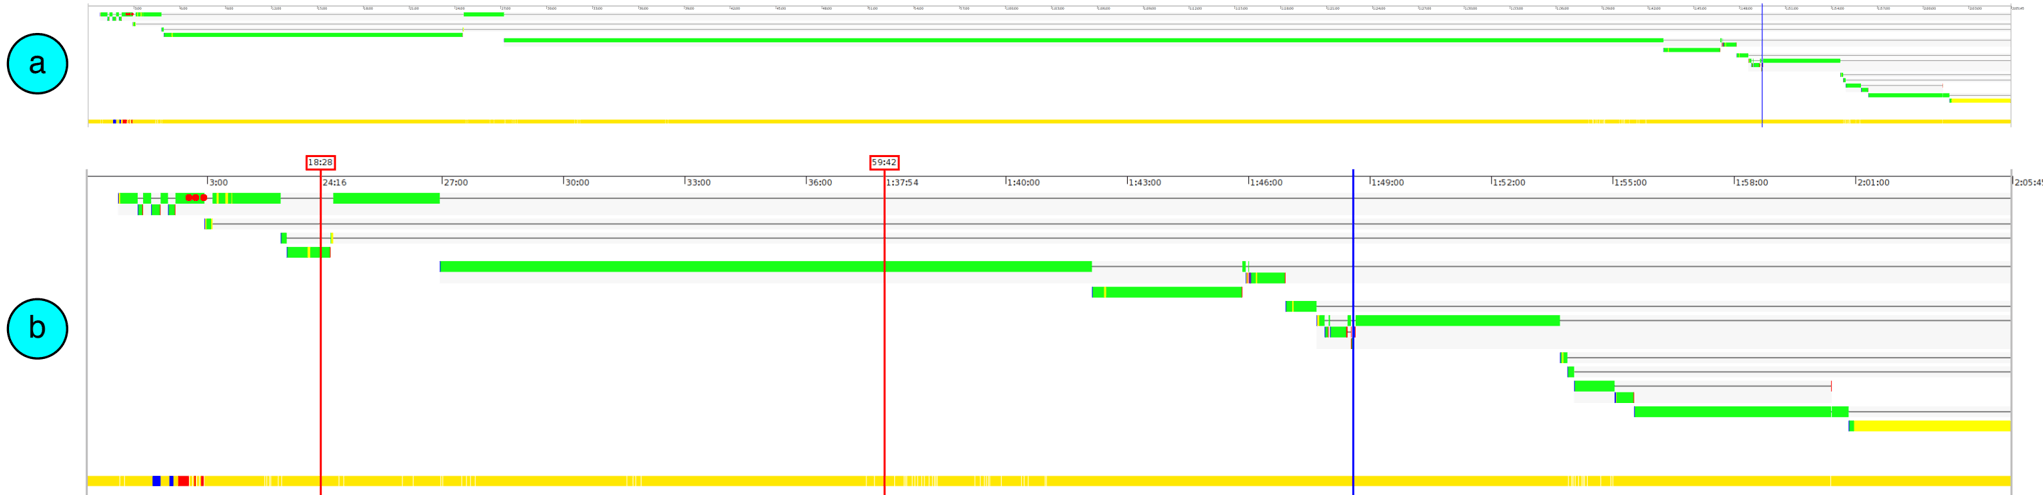
Visual Storytelling of Development Sessions
Most development activities, like program understanding, source code navigation and editing, are supported by Integrated Development Environments (IDEs). They provide different tools and user interfaces (UI) to interact with the source code, such as browsers, debuggers, and inspectors. It is uncertain how and when programmers use different UI elements of an IDE and to what extent they appropriately support development. Previously we developed DFLOW, a tool that seamlessly records and processes interaction data. Our long-term goal is to assess to what extent the UIs of IDEs support the workflow of developers and whether they can be improved. As a first step we present our approach to analyze development sessions in the form of visual storytelling. We illustrate our initial catalogue of visualizations through two development stories.
Improving Low Quality Stack Overflow Post Detection
Stack Overflow is a popular questions and answers (Q&A) website among software developers. It counts more than two millions of users who actively contribute by asking and answering thousands of questions daily. Identifying and reviewing low quality posts preserves the quality of site's contents and it is crucial to maintain a good user experience. In Stack Overflow the identification of poor quality posts is performed by selected users manually. The system also uses an automated identification system based on textual features. Low quality posts automatically enter a review queue maintained by experienced users. We present an approach to improve the automated system in use at Stack Overflow. It analyzes both the content of a post (e.g., simple textual features and complex readability metrics) and community-related aspects (e.g., popularity of a user in the community). Our approach reduces the size of the review queue effectively and removes misclassified good quality posts.
June 2014 2
Mining Unit Tests for Code Recommendation
Developers spend a significant portion of their time understanding and learning the correct usage of the APIs of libraries they want to integrate in their projects. However, learning how to effectively use APIs is complex and time consuming. Code recommendation systems play a crucial role facilitating developers in this task by providing to them relevant examples while they code. This paper proposes a novel approach to code recommendation in which code examples are automatically obtained by mining and manipulating unit tests. In this paper we discuss the theoretical and practical implications that underpin this idea. The discussion leads to a series of fascinating research challenges that we organized in a research agenda.
May 2014 1
Collaboration in Open-source Projects: Myth or Reality?
One of the fundamental principles of open-source projects is that they foster collaboration among developers, disregarding their geographical location or personal background. When it comes to software repositories collaboration is a rather ephemeral phenomenon which lacks a clear definition, and it must therefore be mined and modeled. This throws up the question whether what is mined actually maps to reality. In this paper we investigate collaboration by modeling it using a number of diverse approaches that we then compare to a ground truth obtained by surveying a substantial set of developers of the Pharo open-source community. Our findings indicate that the notion of collaboration must be revisited, as it is undermined by a number of factors that are often tackled in imprecise ways or not taken into account at all.
April 2014 2
Synthesis of Infinite-State Abstractions and Their Use for Software Validation
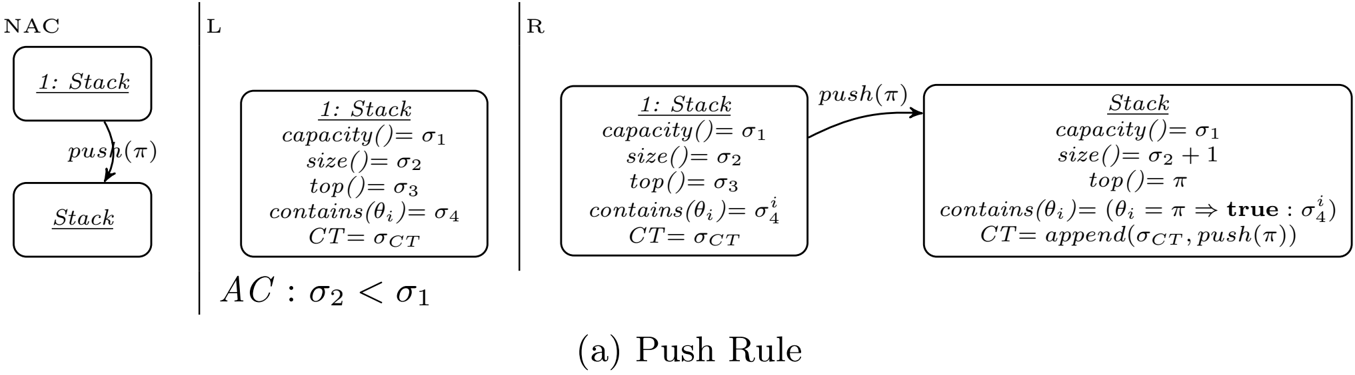
In the recent years, several research efforts have been devoted to developing approaches to synthesize specifications of software behavior. Most of the proposed approaches addressed the inference of finite-state abstractions. The synthesized abstractions have been integrated in different validation scenarios, such as testing. While finite-state models can be effectively used as models of a software component’s behavior for certain specific purposes, they can hardly be used as full-fledged specifications. Because of their very limited expressive power, they cannot represent some of the component behaviors and may lead to synthesizing too coarse abstractions. In this paper, we survey a set of approaches that instead infer infinite-state abstractions, which can be used to express richer sets of behaviors of a software component in a black-box manner. For such approaches, we also discuss the few existing applications to software validation. In particular, we discuss the limitations and identify how, in principle, they can be used in different validation scenarios and how this opens new research directions.
ESSENTIALS: People-centric Essentials for Software Evolution
Shifting the focus of software evolution research to the people-centric 'evolutionary essentials' that stakeholders need in their current working context.
November 2013 1
SMScom: Self-Managing Situated Computing
Methods and tools for the design, validation, and operation of dependable self-managing situated software.
September 2013 1
Detecting component changes at run time with behavior models
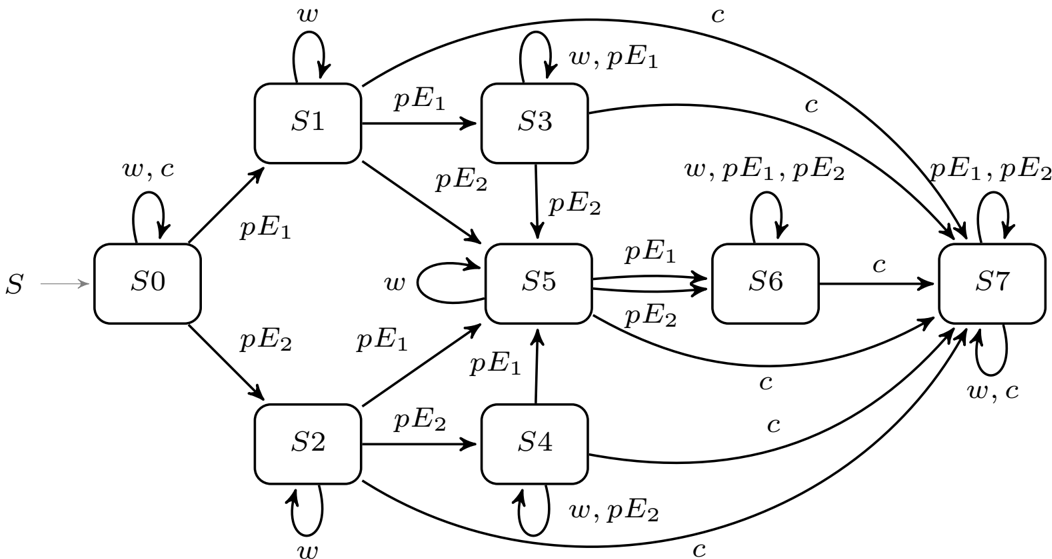
Modern software systems are composed of several services which may be developed and maintained by third parties and thus they can change independently and without notice during the system’s runtime execution. In such systems, changes may possibly be a threat to system functional correctness, and thus to its reliability. Hence, it is important to detect them as soon as they happen to enable proper reaction. Change detection can be done by monitoring system execution and comparing the observed execution traces against models of the services composing the application. Unfortunately, formal specifications for services are not usually provided and developers have to infer them. In this paper we propose a methodology which exactly addresses these issues by using software behavior models to monitor component execution and detect changes. In particular, we describe a technique to infer behavior model specifications with a dynamic black box approach, keep them up-to-date with run time observations and detect behavior changes. Finally, we present a case study to validate the effectiveness of the approach in component change detection for a component that implements a complex, real communication protocol.
April 2013 1
HI-SEA: Holistic Immersive Software Evolution Ambient
A holistic immersive ambient for software evolution, integrating the data around a project into a visual environment for analysis and intelligent recommendations.
June 2012 2
Behavioral validation of JFSL specifications through model synthesis
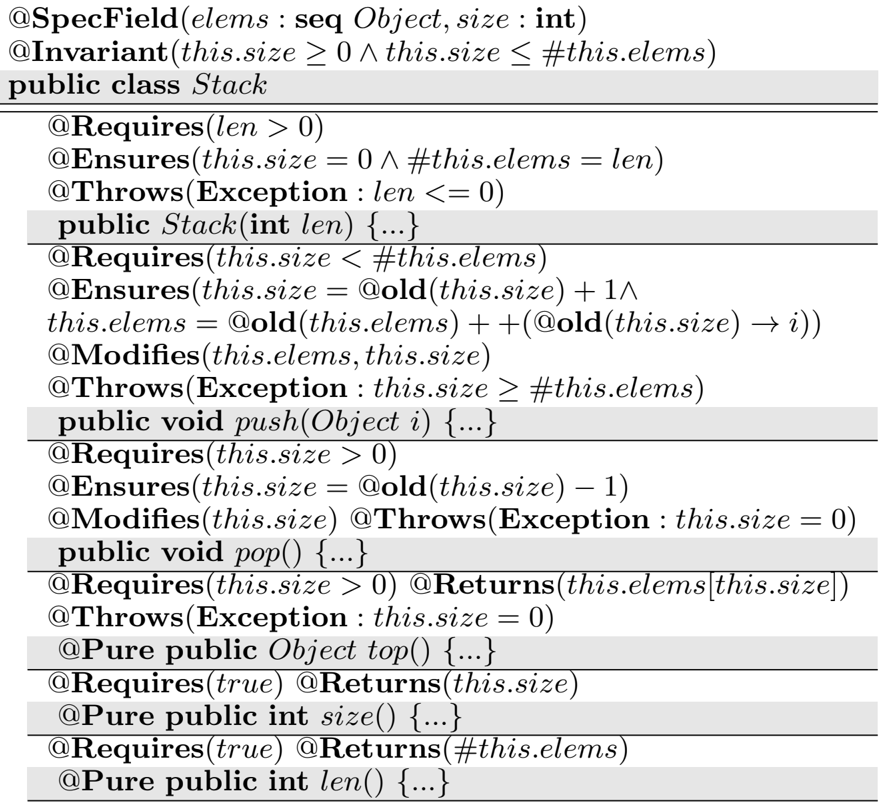
Contracts are a popular declarative specification technique to describe the behavior of stateful components in terms of pre/post conditions and invariants. Since each operation is specified separately in terms of an abstract implementation, it may be hard to understand and validate the resulting component behavior from contracts in terms of method interactions. In particular, properties expressed through algebraic axioms, which specify the effect of sequences of operations, require complex theorem proving techniques to be validated. In this paper, we propose an automatic small-scope based approach to synthesize incomplete behavioral abstractions for contracts expressed in the JFSL notation. The proposed abstraction technique enables the possibility to check that the contract behavior is coherent with behavioral properties expressed as axioms of an algebraic specifications. We assess the applicability of our approach by showing how the synthesis methodology can be applied to some classes of contract-based artifacts like specifications of data abstractions and requirement engineering models.
Runtime Monitoring of Component Changes with Spy@Runtime
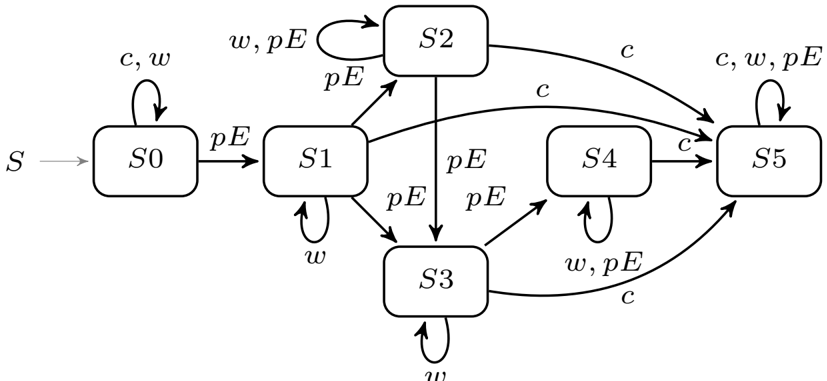
We present Spy@Runtime, a tool to infer and work with behavior models. Spy@Runtime generates models through a dynamic black box approach and is able to keep them updated with observations coming from actual system execution. We also show how to use models describing the protocol of interaction of a software component to detect and report functional changes as soon as they are discovered. Monitoring functional properties is particularly useful in an open environment in which there is a distributed ownership of a software system. Parts of the system may be changed independently and therefore it becomes necessary to monitor the component's behavior at run time.
November 2011 1
Extracting structured data from natural language documents with island parsing
The design and evolution of a software system leave traces in various kinds of artifacts. In software, produced by humans for humans, many artifacts are written in natural language by people involved in the project. Such entities contain structured information which constitute a valuable source of knowledge for analyzing and comprehending a system's design and evolution. However, the ambiguous and informal nature of narrative is a serious challenge in gathering such information, which is scattered throughout natural language text. We present an approach-based on island parsing-to recognize and enable the parsing of structured information that occur in natural language artifacts. We evaluate our approach by applying it to mailing lists pertaining to three software systems. We show that this approach allows us to extract structured data from emails with high precision and recall.
October 2011 1
Runtime Monitoring of Functional Component Changes with Behavior Models
We consider the problem of run-time discovery and continuous monitoring of new components that live in an open environment. We focus on extracting a formal model—which may not be available upfront—by observing the behavior of the running component. We show how the model built at run time can be enriched through new observations (dynamic model update). We also use the inferred model to perform run-time verification. That is, we try to identify if any changes are made to the component that modify its original behavior, contradict the previous observations, and invalidate the inferred model.
June 2011 1
Dynamic Synthesis of Program Invariants using Genetic Programming
Symbolic program manipulation plays a key role in program comprehension and verification. Logic formulae are used to represent the program' s state and transformation rules describe the effect of statement executions on the program's state. A well-known problem arises in the case of loops, since the number of iterations is generally unknown. The effect of a loop is therefore abstracted into a loop invariant, whose derivation cannot in general be automated and requires human ingenuity. In this paper, we present a preliminary approach that in tegrates genetic programming into the synthesis of invariant formula that describes the behavior of a loop. We present a specific representation of formulae that works well with loops manipulating arrays. The technique has been validated with a set of relevant examples with increasing complexity. The preliminary results are promising and show the feasibility of our approach.
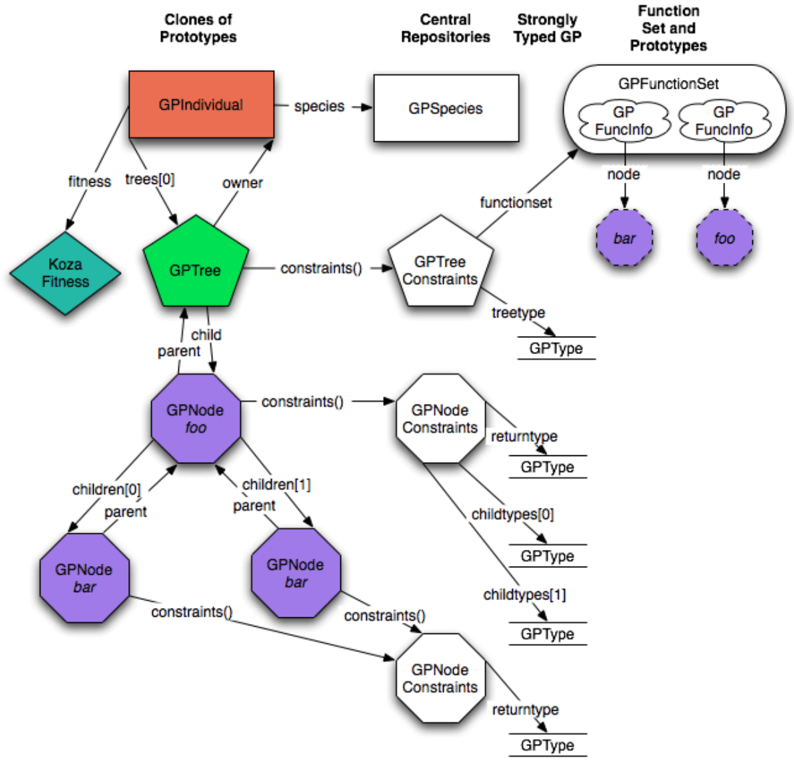
October 2010 1
Behavioral Modeling, Inference and Validation for Component Specifications
MIT CSAIL
May 2010 1
Behavior model based component search: an initial assessment
We focus on the problem of searching components based on semantic queries on their provided interface. Although semantics-based search has long been advocated as a key enabler in the context of component-based software development and, more recently, service-oriented computing, no practical and scalable approach has been proposed yet. This paper presents a promising model-based search technique for interface behaviors based on operational specifications, called behavioral equivalence models (Bems). Semantic queries are expressed equationally, following an algebraic specification style. The search engine tries to match specifications against queries. This can be done quite efficiently by encoding Bems into relational models and queries into relational logic formulae, whose satisfiability is checked with the SAT-based constraint solver KodKod. We can report on an initial very promising assessment of the proposed technique, which has been applied to searching components in Java libraries providing container functionalities.
March 2010 1
Automatic Cross Validation of Multiple Specifications: A Case Study
The problem of formal software specification has been addressed and discussed since the infancy of software engineering. However, among all the proposed solutions, none is universally accepted yet. Many different formal descriptions can in fact be given for the same software component; thus, the problem of determining the consistency relation among those descriptions becomes relevant and potentially critical. In this work, we propose a method for comparing two specific kinds of formal specifications of containers. In particular, we check the consistency of intensional behavior models with algebraic specifications. The consistency check is performed by generating a behavioral equivalence model from the intensional model, converting the algebraic axioms into temporal logic formulae, and then checking them against the model by using the NuSMV model checker. An automated software tool which encodes the problem as model checking has been implemented to check the consistency of recovered specifications of relevant Java classes.
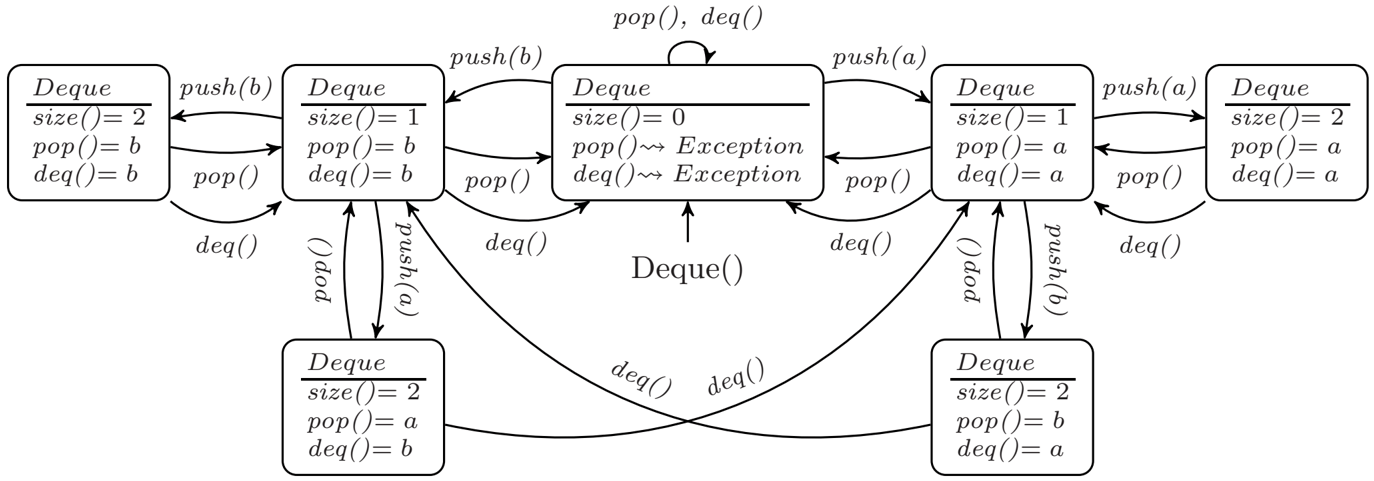
May 2009 1
Synthesizing intensional behavior models by graph transformation
This paper describes an approach (SPY) to recover the specification of a software component from the observation of its run-time behavior. It focuses on components that behave as data abstractions. Components are assumed to be black boxes that do not allow any implementation inspection. The inferred description may help understand what the component does when no formal specification is available. SPY works in two main stages. First, it builds a deterministic finite-state machine that models the partial behavior of instances of the data abstraction. This is then generalized via graph transformation rules. The rules can generate a possibly infinite number of behavior models, which generalize the description of the data abstraction under an assumption of “regularity” with respect to the observed behavior. The rules can be viewed as a likely specification of the data abstraction. We illustrate how SPY works on relevant examples and we compare it with competing methods.
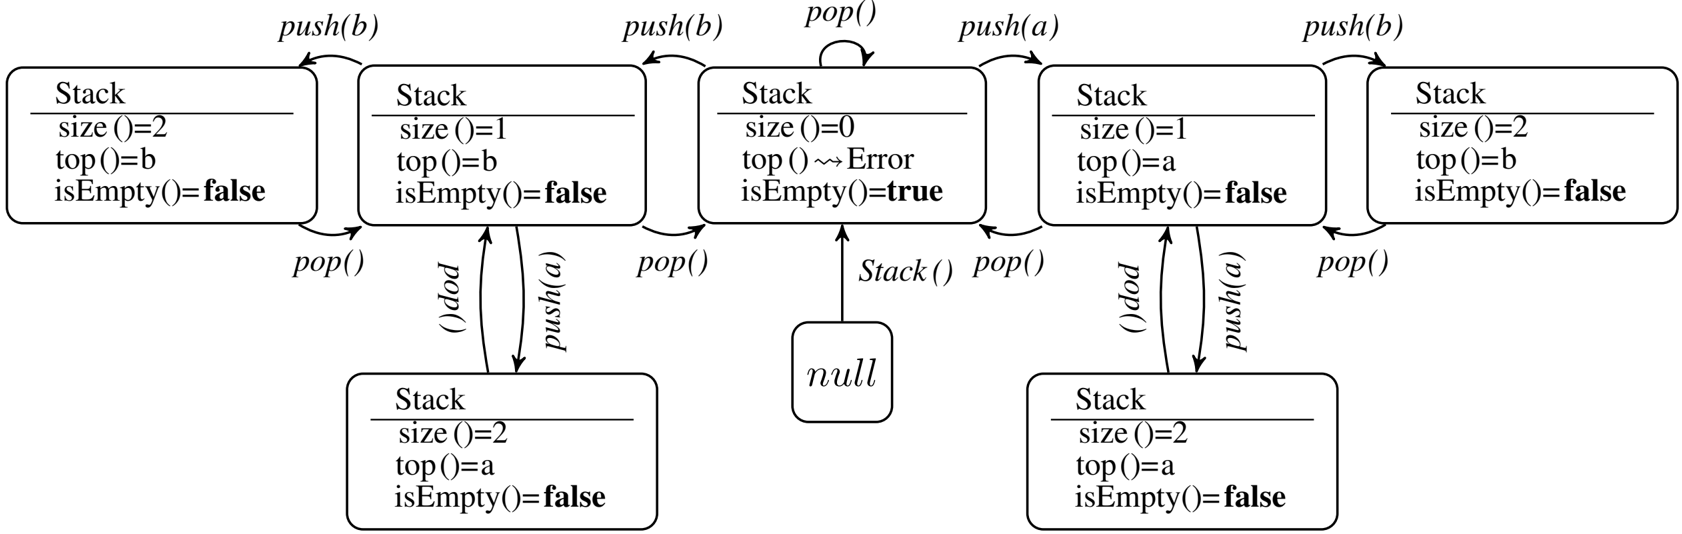
January 2009 1
SPY
SPecification RecoverY: inferring behavior models of stateful software components, and using them at run time to detect when a component's behavior changes
December 2008 1
SMScom: Self-Managing Situated Computing
Methods and tools for the design, validation, and operation of dependable self-managing situated software.
March 2008 1
Using graph transformation systems to specify and verify data abstractions
This paper proposes an approach for the specification of the behavior of software components that implement data abstractions. By generalizing the approach of behavior models using graph transformation, we provide a concise specification for data abstractions that describes the relationship between the internal state, represented in a canonical form, and the observers of the component. Graph transformation also supports the generation of behavior models that are amenable to verification. To this end, we provide a translation approach into an LTL model on which we can express useful properties that can be model-checked with a SAT solver.
September 2007 1
Efficient recovery of algebraic specifications for stateful components
Specification recovery is a necessary step of many reverse engineering and reuse efforts. This paper deals with recovering the semantic part of a component's interface. It focuses on stateful components that provide data abstractions. Recovery is achieved by following a black-box strategy, i.e. by observing the component's dynamic behavior. Among the published approaches, Heureka recovers algebraic specifications from Java classes. Another approach (Adabu) recovers behavioral models. The work we describe here adapts the latter, which provides an approximate semantic description for the class, to significantly optimize the former. The resulting approach, called Adiheu, is described in the paper with a preliminary assessment.