Conference
Browse all content in this category
Visual Storytelling of Development Sessions
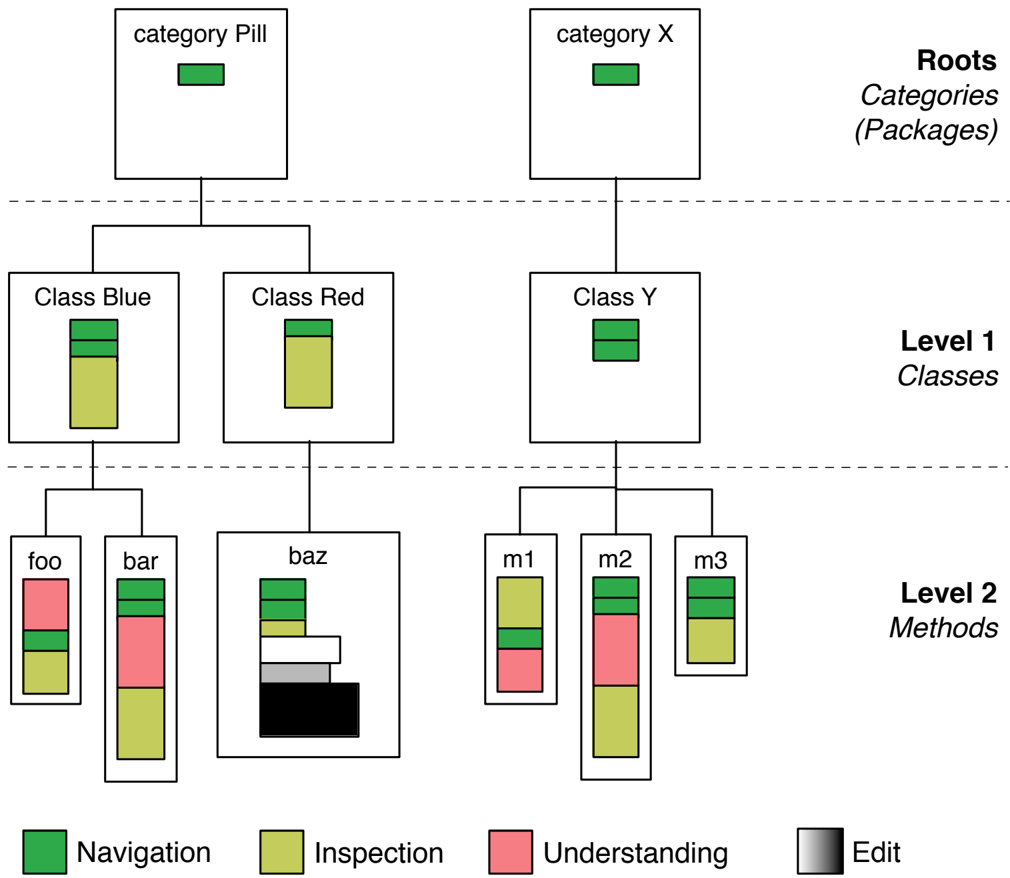
Most development activities, like program understanding, source code navigation and editing, are supported by Integrated Development Environments (IDEs). They provide different tools and user interfaces (UI) to interact with the source code, such as browsers, debuggers, and inspectors. It is uncertain how and when programmers use different UI elements of an IDE and to what extent they appropriately support development. Previously we developed DFLOW, a tool that seamlessly records and processes interaction data. Our long-term goal is to assess to what extent the UIs of IDEs support the workflow of developers and whether they can be improved. As a first step we present our approach to analyze development sessions in the form of visual storytelling. We illustrate our initial catalogue of visualizations through two development stories.
Improving Low Quality Stack Overflow Post Detection
Stack Overflow is a popular questions and answers (Q&A) website among software developers. It counts more than two millions of users who actively contribute by asking and answering thousands of questions daily. Identifying and reviewing low quality posts preserves the quality of site's contents and it is crucial to maintain a good user experience. In Stack Overflow the identification of poor quality posts is performed by selected users manually. The system also uses an automated identification system based on textual features. Low quality posts automatically enter a review queue maintained by experienced users. We present an approach to improve the automated system in use at Stack Overflow. It analyzes both the content of a post (e.g., simple textual features and complex readability metrics) and community-related aspects (e.g., popularity of a user in the community). Our approach reduces the size of the review queue effectively and removes misclassified good quality posts.
Mining Unit Tests for Code Recommendation
Developers spend a significant portion of their time understanding and learning the correct usage of the APIs of libraries they want to integrate in their projects. However, learning how to effectively use APIs is complex and time consuming. Code recommendation systems play a crucial role facilitating developers in this task by providing to them relevant examples while they code. This paper proposes a novel approach to code recommendation in which code examples are automatically obtained by mining and manipulating unit tests. In this paper we discuss the theoretical and practical implications that underpin this idea. The discussion leads to a series of fascinating research challenges that we organized in a research agenda.
Collaboration in Open-source Projects: Myth or Reality?
One of the fundamental principles of open-source projects is that they foster collaboration among developers, disregarding their geographical location or personal background. When it comes to software repositories collaboration is a rather ephemeral phenomenon which lacks a clear definition, and it must therefore be mined and modeled. This throws up the question whether what is mined actually maps to reality. In this paper we investigate collaboration by modeling it using a number of diverse approaches that we then compare to a ground truth obtained by surveying a substantial set of developers of the Pharo open-source community. Our findings indicate that the notion of collaboration must be revisited, as it is undermined by a number of factors that are often tackled in imprecise ways or not taken into account at all.
Synthesis of Infinite-State Abstractions and Their Use for Software Validation
In the recent years, several research efforts have been devoted to developing approaches to synthesize specifications of software behavior. Most of the proposed approaches addressed the inference of finite-state abstractions. The synthesized abstractions have been integrated in different validation scenarios, such as testing. While finite-state models can be effectively used as models of a software component’s behavior for certain specific purposes, they can hardly be used as full-fledged specifications. Because of their very limited expressive power, they cannot represent some of the component behaviors and may lead to synthesizing too coarse abstractions. In this paper, we survey a set of approaches that instead infer infinite-state abstractions, which can be used to express richer sets of behaviors of a software component in a black-box manner. For such approaches, we also discuss the few existing applications to software validation. In particular, we discuss the limitations and identify how, in principle, they can be used in different validation scenarios and how this opens new research directions.
Behavioral validation of JFSL specifications through model synthesis
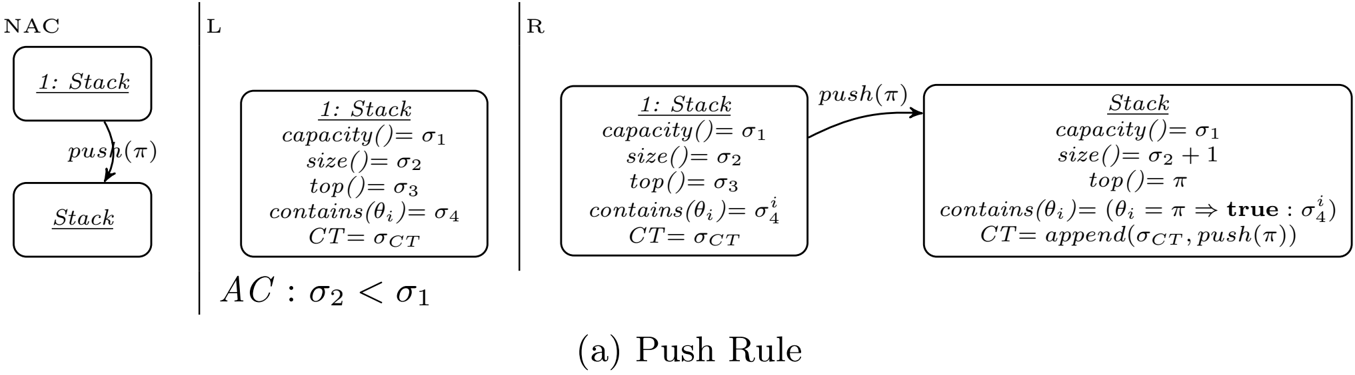
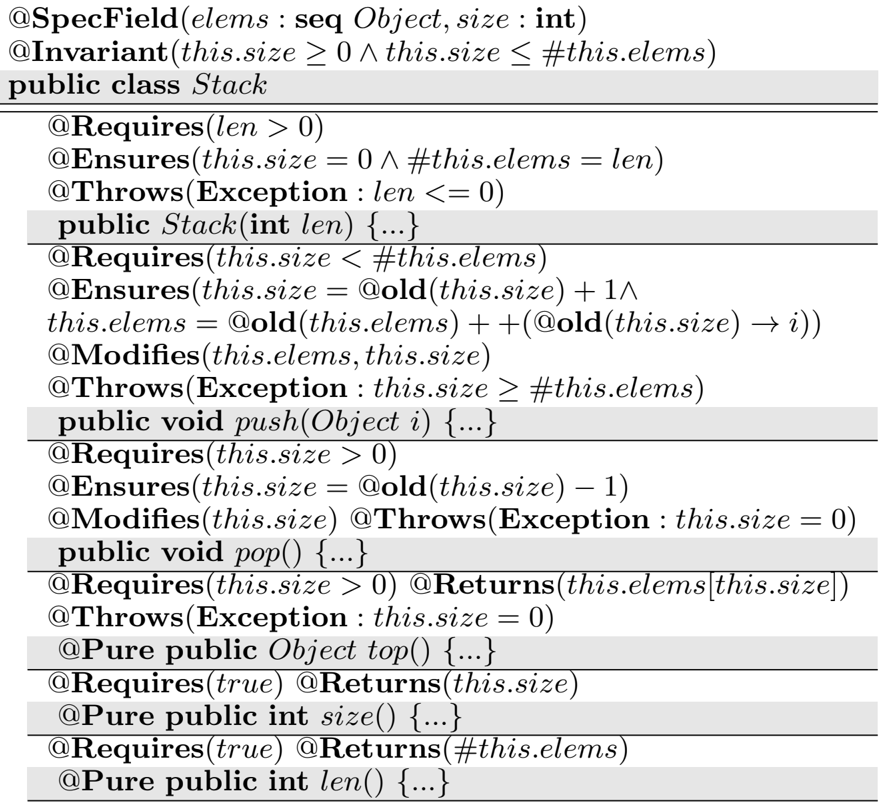
Contracts are a popular declarative specification technique to describe the behavior of stateful components in terms of pre/post conditions and invariants. Since each operation is specified separately in terms of an abstract implementation, it may be hard to understand and validate the resulting component behavior from contracts in terms of method interactions. In particular, properties expressed through algebraic axioms, which specify the effect of sequences of operations, require complex theorem proving techniques to be validated. In this paper, we propose an automatic small-scope based approach to synthesize incomplete behavioral abstractions for contracts expressed in the JFSL notation. The proposed abstraction technique enables the possibility to check that the contract behavior is coherent with behavioral properties expressed as axioms of an algebraic specifications. We assess the applicability of our approach by showing how the synthesis methodology can be applied to some classes of contract-based artifacts like specifications of data abstractions and requirement engineering models.
Runtime Monitoring of Component Changes with Spy@Runtime
We present Spy@Runtime, a tool to infer and work with behavior models. Spy@Runtime generates models through a dynamic black box approach and is able to keep them updated with observations coming from actual system execution. We also show how to use models describing the protocol of interaction of a software component to detect and report functional changes as soon as they are discovered. Monitoring functional properties is particularly useful in an open environment in which there is a distributed ownership of a software system. Parts of the system may be changed independently and therefore it becomes necessary to monitor the component's behavior at run time.
Extracting structured data from natural language documents with island parsing
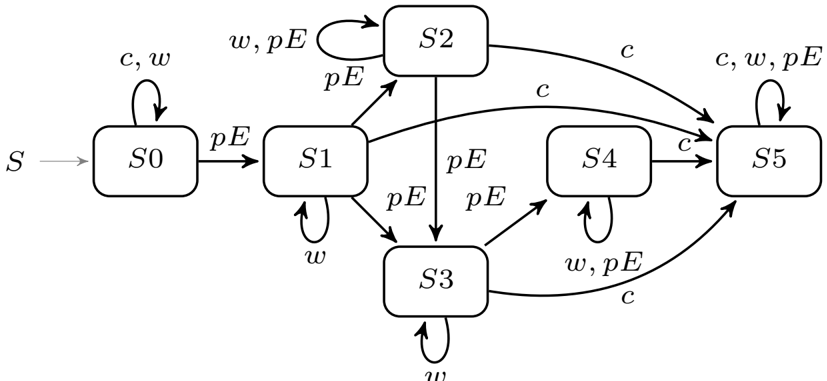
The design and evolution of a software system leave traces in various kinds of artifacts. In software, produced by humans for humans, many artifacts are written in natural language by people involved in the project. Such entities contain structured information which constitute a valuable source of knowledge for analyzing and comprehending a system's design and evolution. However, the ambiguous and informal nature of narrative is a serious challenge in gathering such information, which is scattered throughout natural language text. We present an approach-based on island parsing-to recognize and enable the parsing of structured information that occur in natural language artifacts. We evaluate our approach by applying it to mailing lists pertaining to three software systems. We show that this approach allows us to extract structured data from emails with high precision and recall.