Document Engineering
Browse all content with this tag
Mining a Century of Swiss Trademark Data
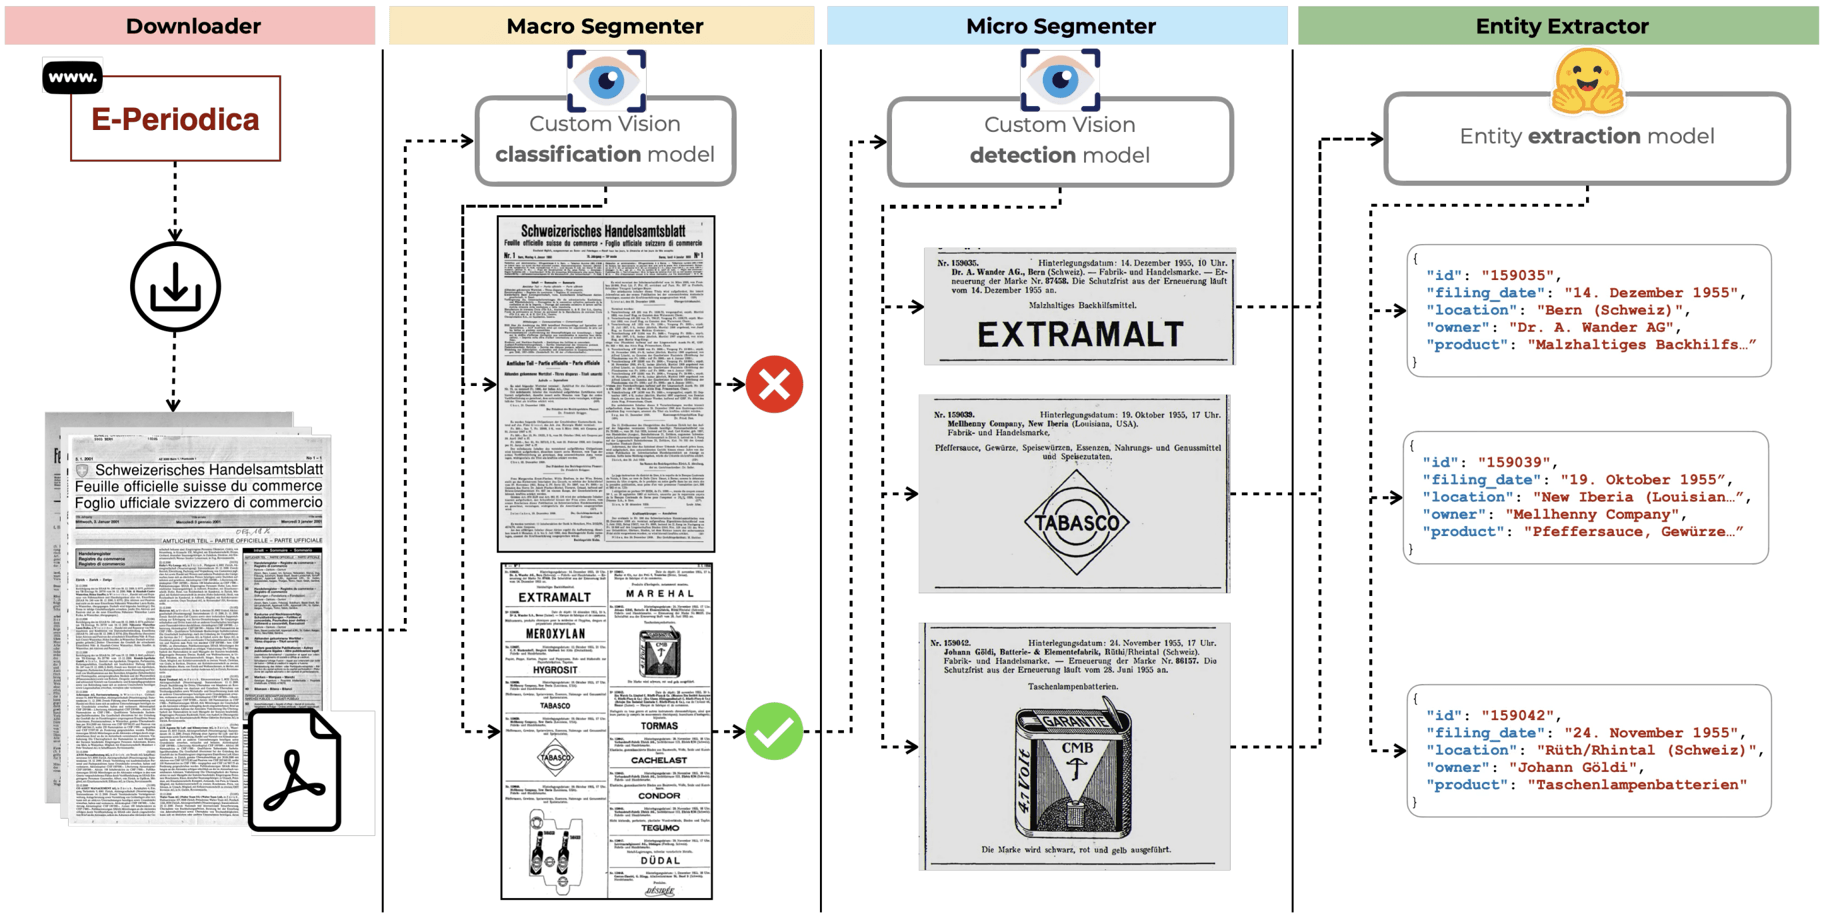
This paper presents an approach for extracting trademark registration events from the Swiss Official Gazette of Commerce (SOGC), an official daily journal published by the Swiss Confederation since January 1883. Until 2001, the data is only available as scanned documents, which constitute the target dataset of this study. Our approach is composed of a chain of three steps based on state-of-the-art deep learning techniques. We leverage image classification to identify pages containing trademarks (macro segmentation); we apply object detection to identify the portion of the page corresponding to a registration event (micro segmentation); last, we perform information extraction using a document AI technique. We obtain a dataset of ca. 500,000 trademark registration events, extracted from a corpus of 430,000 pages. Each step of our workflow has relatively high accuracy: the macro and micro segmentation steps show precision and recall greater than 95% on a manually constructed dataset. The dataset offers a unique historical perspective on trademark registrations in Switzerland that is not available from any other source. Showcasing what can be achieved with the extracted information, we provide answers to a set of preliminary economics questions.
Mining A Century of Swiss Trademarks
Daniel Travaglia · Master of Science in Software & Data Engineering
Institutional Foundations of Industrialization, Financialization, and Globalization of the Swiss Economy
Leveraging NLP and ML to transform historical corpora into structured geocoded data
REFLEX Data Pipeline & REFLEXplorer
The software backbone of the REFLEX project: a document-AI and NLP pipeline turning 140 years of scanned Swiss commercial registry into structured, geocoded data, and a web platform to explore it