Projects
Firms and tax competition in the digital economy: a data platform for geo-temporal network analysis
Building a data platform on the network of firms that supports geo and temporal analysis
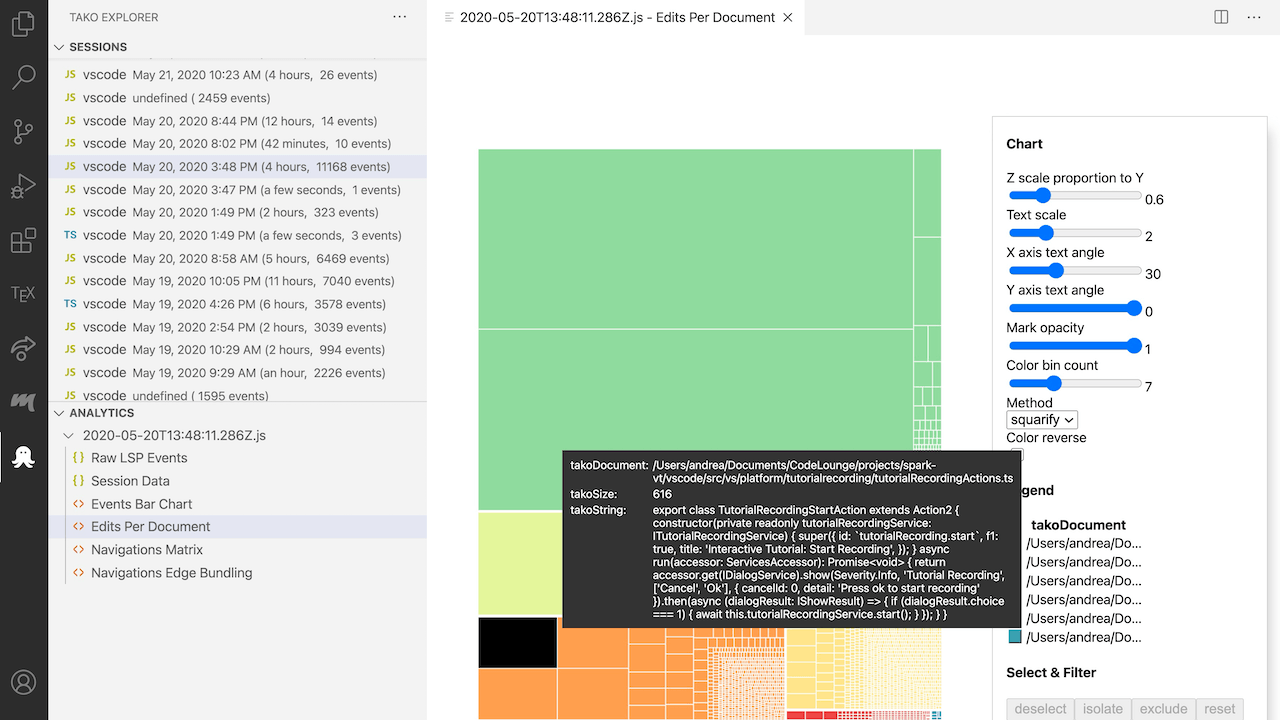
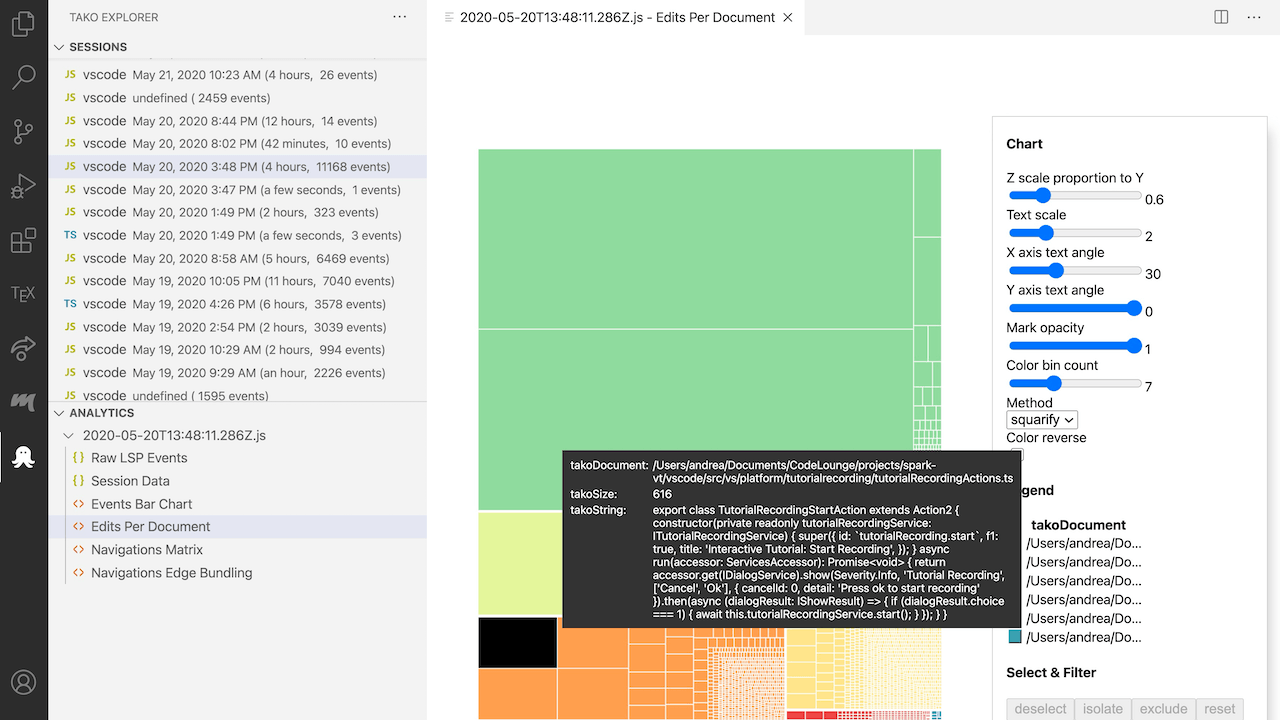
Collecting and Visualizing Development Activities in Visual Studio Code
Tracking low-level IDE interaction events and transforming them into meaningful data to understand our own productivity
myUSI Research & Teaching Support Platform
Management and analytics for the University
ESSENTIALS: People-centric Essentials for Software Evolution
Shifting the focus of software evolution research to the people-centric 'evolutionary essentials' that stakeholders need in their current working context.
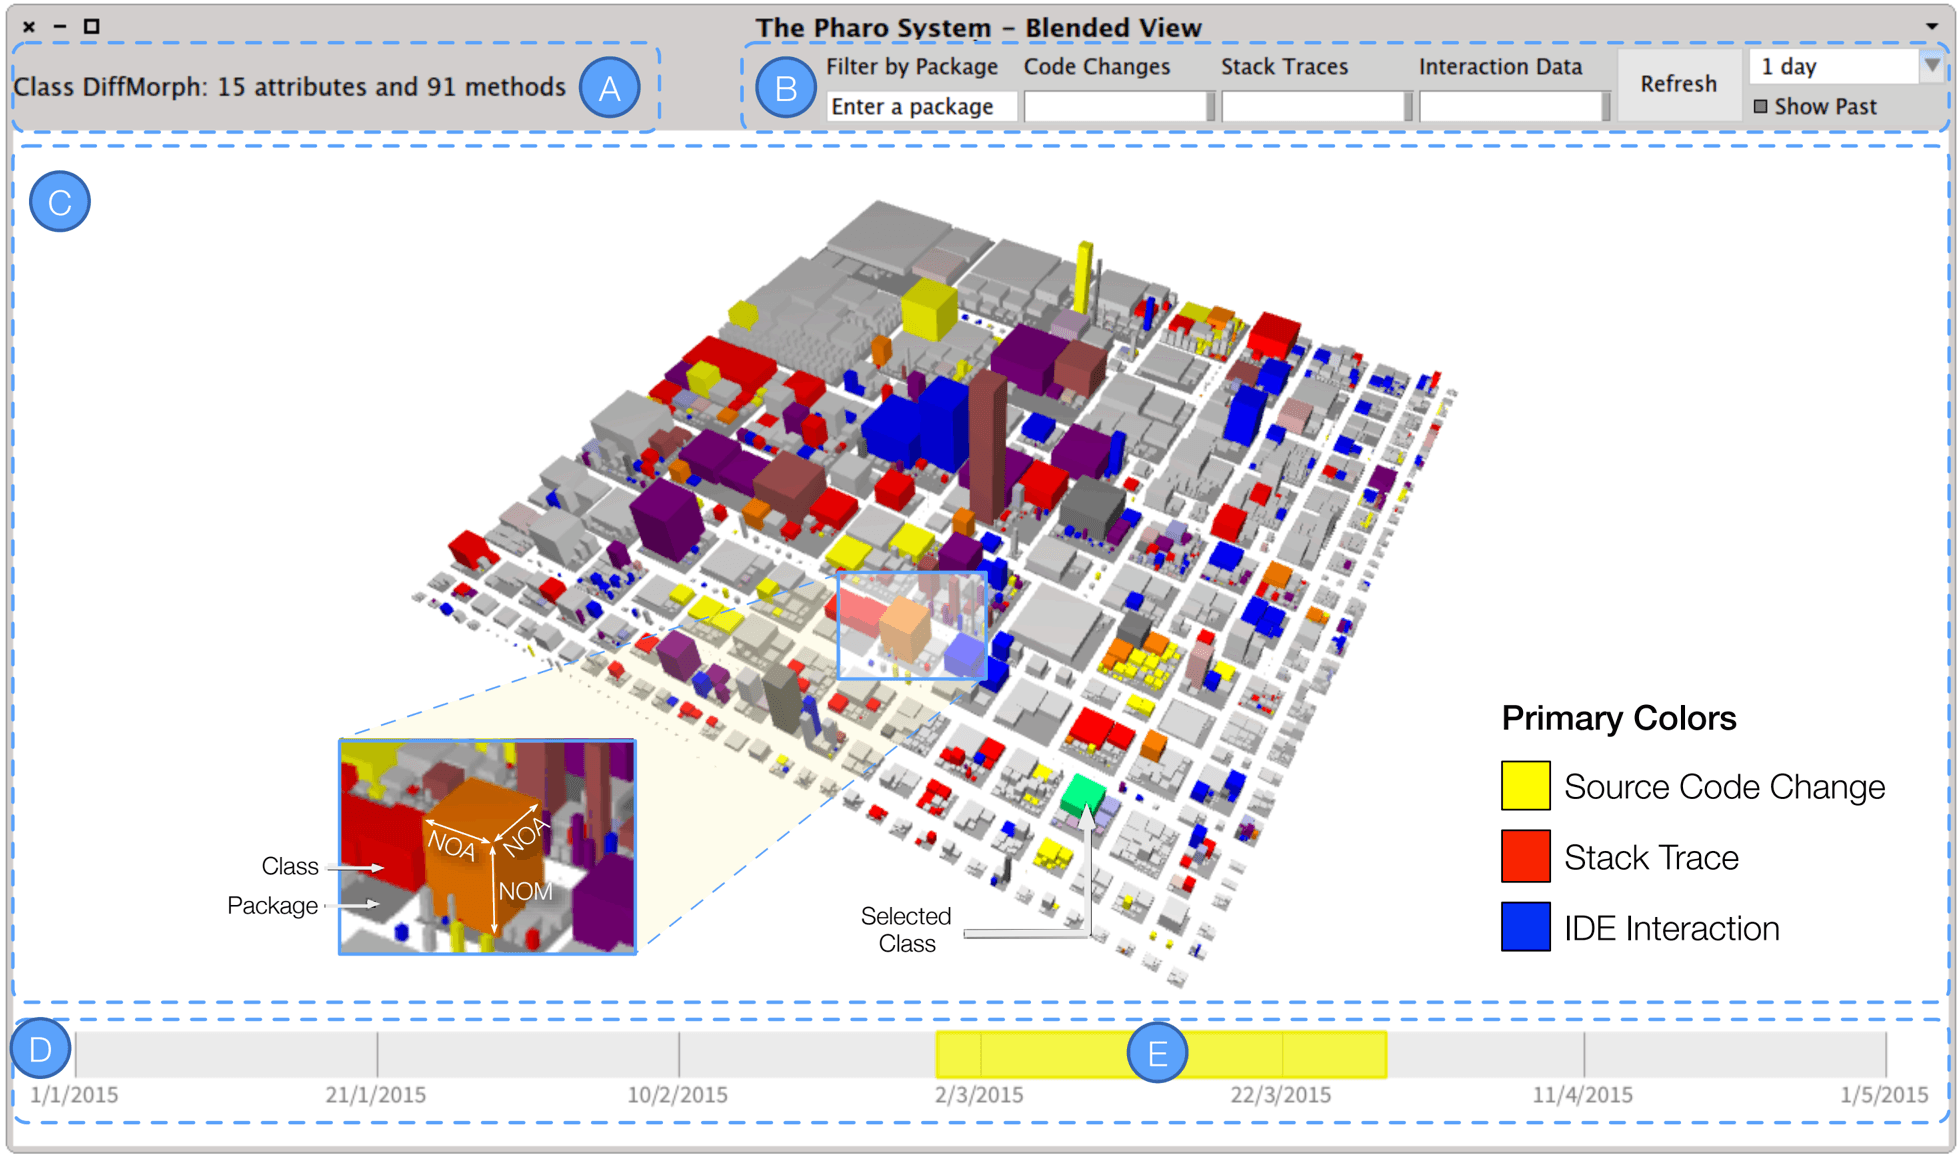
HI-SEA: Holistic Immersive Software Evolution Ambient
A holistic immersive ambient for software evolution, integrating the data around a project into a visual environment for analysis and intelligent recommendations.
Teaching and Training Activities
Software Atelier 4: Software Engineering Project (2018-2020)
Programming skills are essential but not enough to develop large and complex software systems that require the coordination of a team of specialists. Software engineering is about the development of such moderns software systems. Students will learn to go beyond programming, to coordinate a team, to apply modern methodologies and techniques.
USI Hackathon 2019: Making Data Alive
A three-day hackathon held from 15 to 17 November 2019 in the Aula Magna of the [USI](https://www.usi.ch) campus in Lugano, organized by [CodeLounge](https://codelounge.si.usi.ch), the research and development group of the [Software Institute](https://si.usi.ch), with the support of [Ated4Kids](https://www.ated.ch/progetto_ated4kids.php) and [Lugano Living Lab](https://luganolivinglab.ch). I was part of the organizing team, led by Marco D'Ambros and Michele Lanza together with Mauro Prevostini and Elisa Larghi from the Faculty of Informatics, and with my CodeLounge colleagues Luca Ponzanelli, Davide Paolo Tua, Jesper Findahl, and Roberto Minelli. I also took the pictures of the event, collected in the [Flickr album](https://www.flickr.com/photos/185754239@N08/albums/72157711974256596/). All the details are on the [event website](https://hackathon.usi.ch).
Mining and Modelling Unstructured Data
Artifacts containing natural language, like Q&A websites (e.g., Stack Overflow), tutorials, and development emails, are essential to support software development. They have become a popular subject for software engineering research. The analysis of such artifacts is particularly challenging because of their heterogeneity: These resources consist of natural language interleaved with fragments of multiple programming and markup languages. Our tutorial is aimed at overcoming the challenge, by first discussing the state of the art of methodologies to analyze unstructured data, and their current limitations and challenges. Then, it focuses on our efforts towards a systematic approach to model contents of such artifacts. This in turn enables novel holistic analyses that fully exploit their intrinsic heterogeneous nature. We describe the theoretical foundations of our StORMeD framework, how it can be used to extract a full-fledged model of a development artifacts, and how it can be leveraged to construct various types of analyses, such as summarization.
Software
Tako
A Visual Studio Code extension that records, aggregates, and visualizes IDE interaction data — entirely on the developer's own machine
MyUSI Platform
A modular platform for managing the academic life of a university: a GraphQL-based, actor-oriented backend and a component-based frontend, piloted on the research service
StORMeD
Heterogeneous abstract syntax trees for Stack Overflow: a Scala development kit, a ready-made JSON dataset, and an island-parsing web service
Theses & Projects
Automatic Classification of Development Artifact Contents
Alexander Fischer · Master of Science in Software & Data Engineering
Research Data Visual Analytics
Lorenzo Ferri · Bachelor of Science in Informatics
University timetable scheduling
Aron Fiechter · Bachelor of Science in Informatics
Assessing Software Documents by Comprehension Effort
Talal El Afchal · Master of Science in Informatics
WebDistiller
Lucas Pennati · Bachelor of Science in Informatics
Holistic Recommender Systems for Software Engineering
Luca Ponzanelli · Doctor of Philosophy in Informatics
CSI:Cub8
Marco Bedulli · Bachelor of Science in Informatics
Co-Authored Publications
Automatic Identification and Classification of Software Development Video Tutorial Fragments
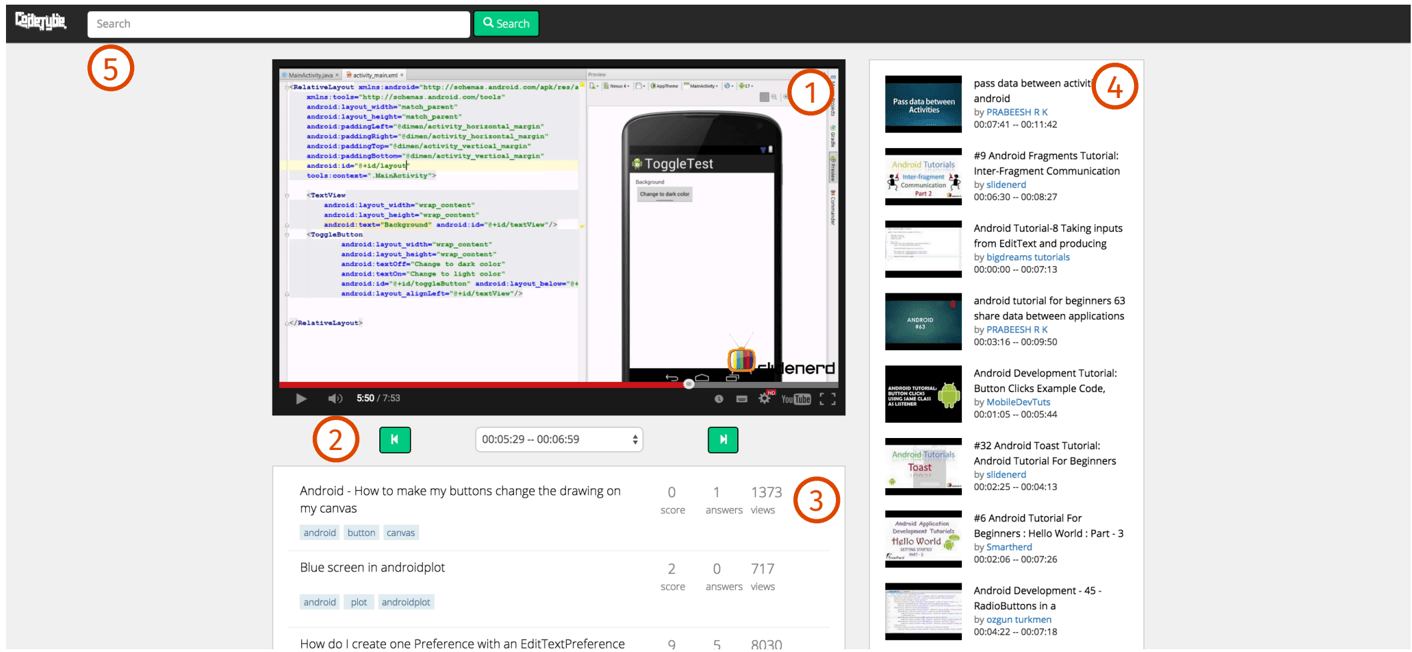
Software development video tutorials have seen a steep increase in popularity in recent years. Their main advantage is that they thoroughly illustrate how certain technologies, programming languages, etc. are to be used. However, they come with a caveat: there is currently little support for searching and browsing their content. This makes it difficult to quickly find the useful parts in a longer video, as the only options are watching the entire video, leading to wasted time, or fast-forwarding through it, leading to missed information. We present an approach to mine video tutorials found on the web and enable developers to query their contents as opposed to just their metadata. The video tutorials are processed and split into coherent fragments, such that only relevant fragments are returned in response to a query. Moreover, fragments are automatically classified according to their purpose, such as introducing theoretical concepts, explaining code implementation steps, or dealing with errors. This allows developers to set filters in their search to target a specific type of video fragment they are interested in. In addition, the video fragments in CodeTube are complemented with information from other sources, such as Stack Overflow discussions, giving more context and useful information for understanding the concepts.
On the Uniqueness of Code Redundancies
Code redundancy widely occurs in software projects. Researchers have investigated the existence, causes, and impacts of code redundancy, showing that it can be put to good use, for example in the context of code completion. When analyzing source code redundancy, previous studies considered software projects as sequences of tokens, neglecting the role of the syntactic structures enforced by programming languages. However, differences in the redundancy of such structures may jeopardize the performance of applications leveraging code redundancy. We present a study of the redundancy of several types of code constructs in a large-scale dataset of active Java projects mined from GitHub, unveiling that redundancy is not uniform and mainly resides in specific code constructs. We further investigate the implications of the locality of redundancy by analyzing the performance of language models when applied to code completion. Our study discloses the perils of exploiting code redundancy without taking into account its strong locality in specific code constructs.
How Developers Document Pull Requests with External References
Online resources of formal and informal documentation-such as reference manuals, forum discussions and tutorials-have become an asset to software developers, as they allow them to tackle problems and to learn about new tools, libraries, and technologies. This study investigates to what extent and for which purpose developers refer to external online resources when they contribute changes to a repository by raising a pull request. Our study involved (i) a quantitative analysis of over 150k URLs occurring in pull requests posted in GitHub, (ii) a manual coding of the kinds of software evolution activities performed in commits related to a statistically significant sample of 2,130 pull requests referencing external documentation resources, (iii) a survey with 69 participants, who provided feedback on how they use online resources and how they refer to them when filing a pull request. Results of the study indicate that, on the one hand, developers find external resources useful to learn something new or to solve specific problems, and they perceive useful referring such resources to better document changes. On the other hand, both interviews and repository mining suggest that external resources are still rarely referred in document changes.
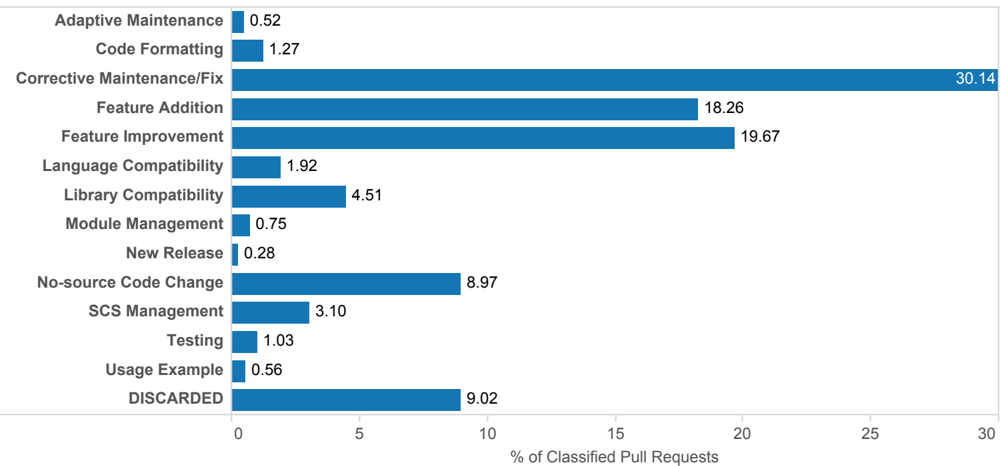
Supporting Software Developers with a Holistic Recommender System
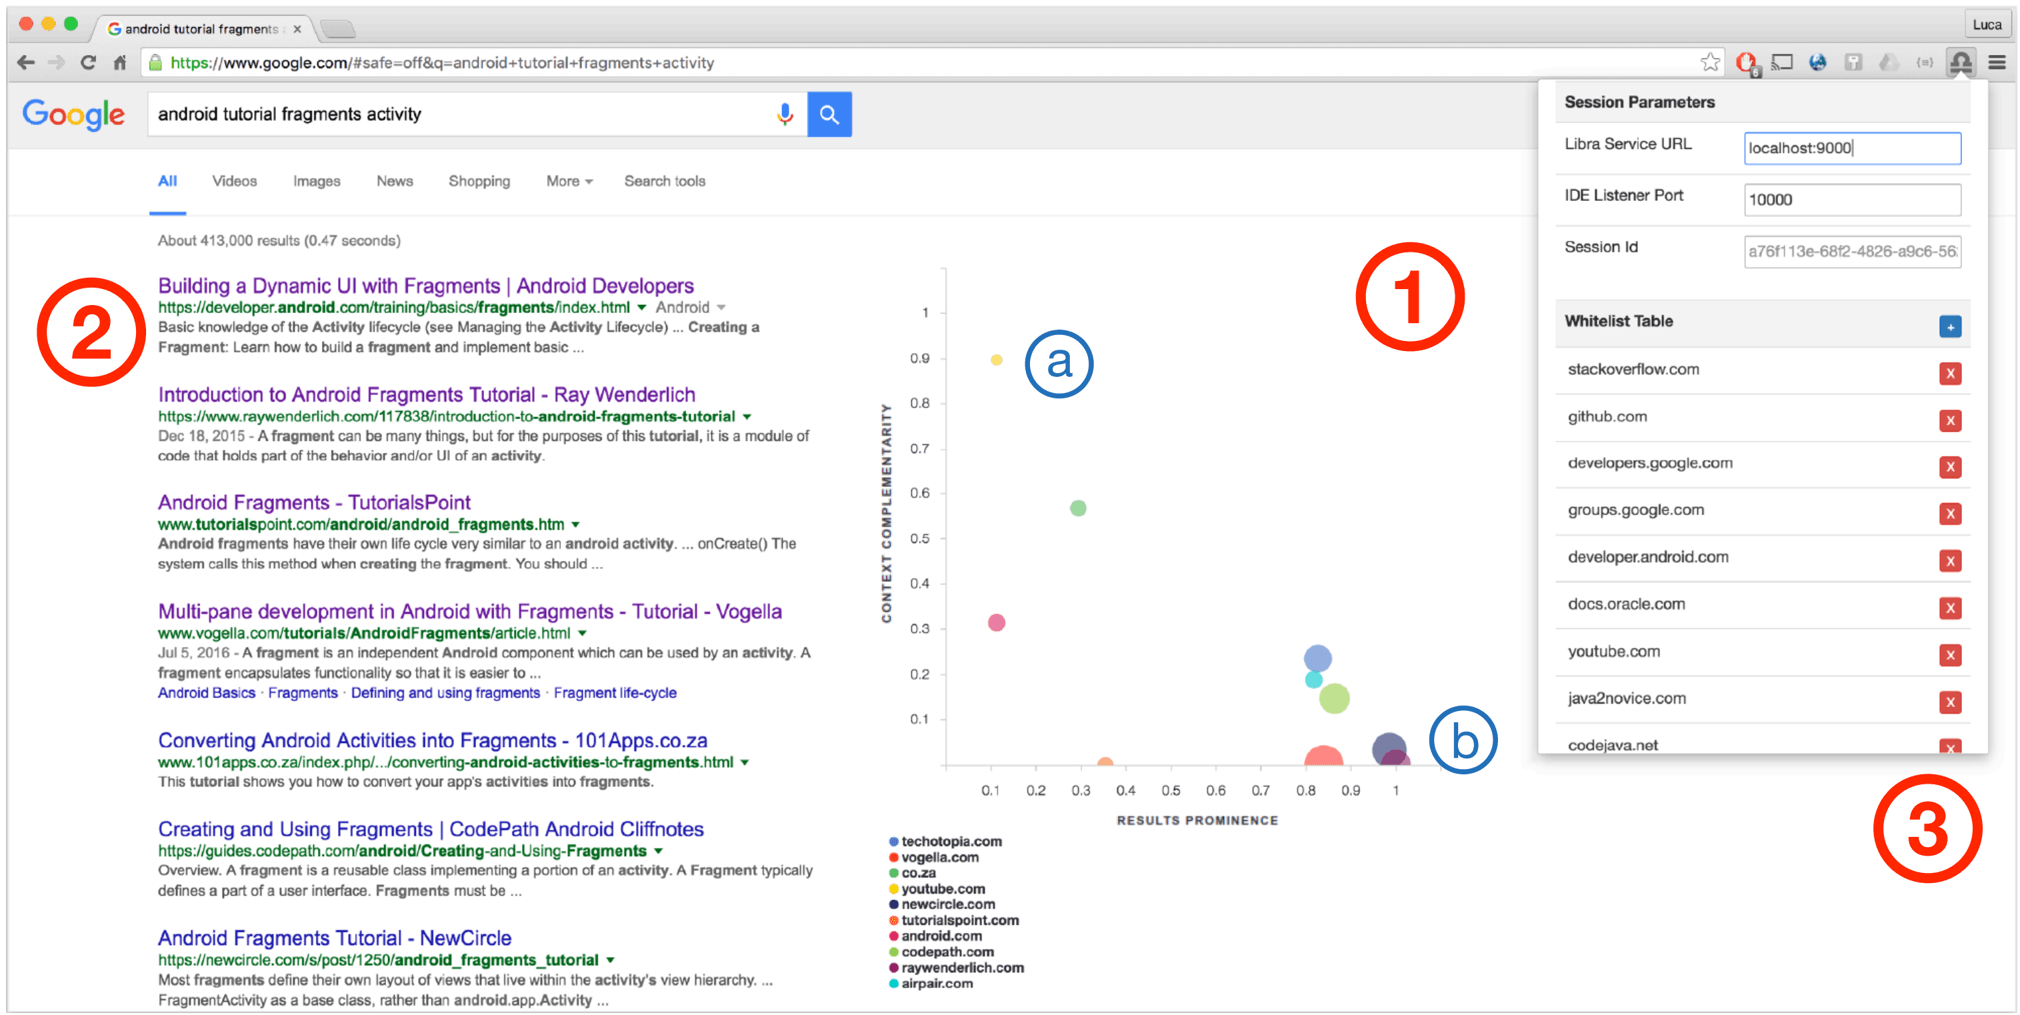
The promise of recommender systems is to provide intelligent support to developers during their programming tasks. Such support ranges from suggesting program entities to taking into account pertinent QnA pages. However, current recommender systems limit the context analysis to change history and developers' activities in the IDE, without considering what a developer has already consulted or perused, e.g., by performing searches from the Web browser. Given the faceted nature of many programming tasks, and the incompleteness of the information provided by a single artifact, several heterogeneous resources are required to obtain the broader picture needed by a developer to accomplish a task. We present Libra, a holistic recommender system. It supports the process of searching and navigating the information needed by constructing a holistic meta-information model of the resources perused by a developer, analyzing their semantic relationships, and augmenting the web browser with a dedicated interactive navigation chart. The quantitative and qualitative evaluation of Libra provides evidence that a holistic analysis of a developer's information context can indeed offer comprehensive and contextualized support to information navigation and retrieval during software development.
The Tragedy of Defect Prediction, Prince of Empirical Software Engineering Research
If measured by the number of published papers, defect prediction has become an important research field over the past decade, with many researchers continuously proposing novel approaches to predict defects in software systems. However, most of these approaches have had a noticeable lack of impact on industrial practice. This lack of impact is because something is intrinsically wrong in how defect prediction approaches are evaluated.
Too Long; Didn't Watch! Extracting Relevant Fragments from Software Development Video Tutorials
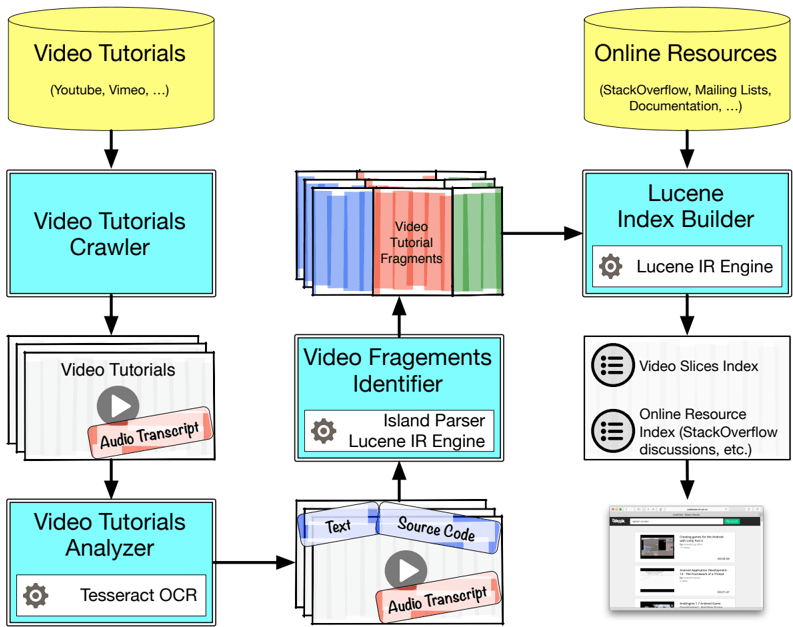
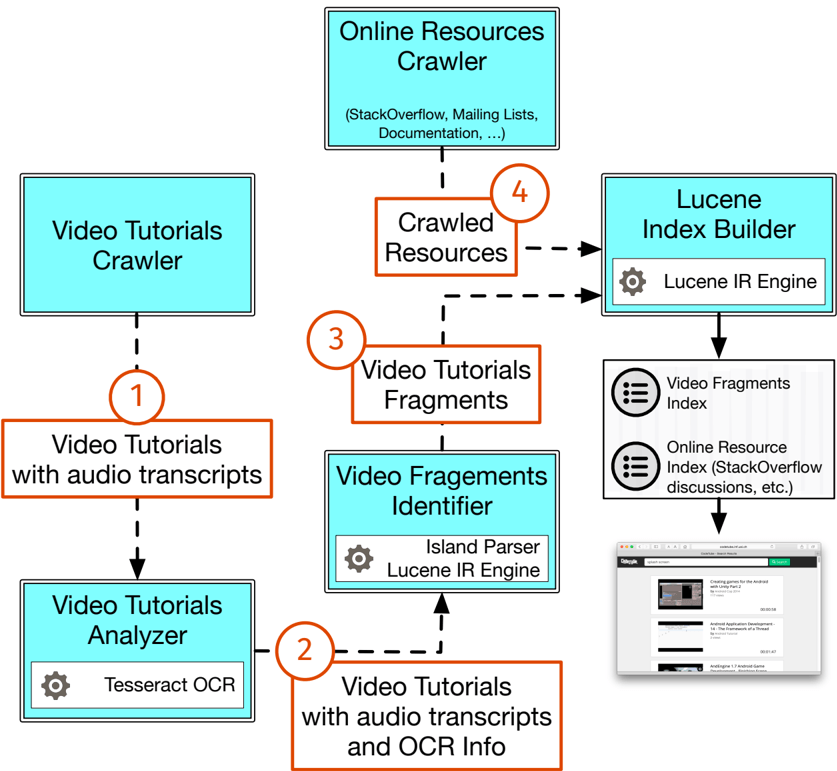
When knowledgeable colleagues are not available, developers resort to offline and online resources, e.g. tutorials, mailing lists, and Q&A websites. These, however, need to be found, read, and understood, which takes its toll in terms of time and mental energy. A more immediate and accessible resource are video tutorials found on the web, which in recent years have seen a steep increase in popularity. Nonetheless, videos are an intrinsically noisy data source, and finding the right piece of information might be even more cumbersome than using the previously mentioned resources. We present CodeTube, an approach which mines video tutorials found on the web, and enables developers to query their contents. The video tutorials are split into coherent fragments, to return only fragments related to the query. These are complemented with information from additional sources, such as Stack Overflow discussions. The results of two studies to assess CodeTube indicate that video tutorials - if appropriately processed - represent a useful, yet still under-utilized source of information for software development.
CodeTube: Extracting Relevant Fragments from Software Development Video Tutorials
Nowadays developers heavily rely on sources of informal documentation. Examples include Q&A forums, slides, or video tutorials, the latter being particularly useful to provide introductory notions for a piece of technology. The current practice is that developers have to browse sources individually, which in the case of video tutorials is cumbersome, as they are lengthy and cannot be searched based on their contents. We present CodeTube, a Web-based recommender system that analyzes the contents of video tutorials and is able to provide, given a query, cohesive and self-contained video fragments, along with links to relevant Stack Overflow discussions. CodeTube relies on a combination of textual analysis and image processing applied on video tutorial frames and speech transcripts to split videos into cohesive fragments, index them and identify related Stack Overflow discussions.
Use at Your Own Risk: The Java Unsafe API in the Wild
Java is a safe language. Its runtime environment provides strong safety guarantees that any Java application can rely on. Or so we think. We show that the runtime actually does not provide these guarantees—for a large fraction of today's Java code. Unbeknownst to many application developers, the Java runtime includes a \"backdoor" that allows expert library and framework developers to circumvent Java's safety guarantees. This backdoor is there by design, and is well known to experts, as it enables them to write high-performance systems-level code in Java. For much the same reasons that safe languages are preferred over unsafe languages, these powerful but unsafe capabilities in Java should be restricted. They should be made safe by changing the language, the runtime system, or the libraries. At the very least, their use should be restricted. This paper is a step in that direction. We analyzed 74 GB of compiled Java code, spread over 86,479 Java archives, to determine how Java’s unsafe capabilities are used in real-world libraries and applications. We found that 25% of Java bytecode archives depend on un- safe third-party Java code, and thus Java's safety guarantees cannot be trusted. We identify 14 different usage patterns of Java’s unsafe capabilities, and we provide supporting evidence for why real-world code needs these capabilities. Our long-term goal is to provide a foundation for the design of new language features to regain safety in Java.
SODA: The Stack Overflow Dataset Almanac
Stack Overflow has become a fundamental resource for developers, becoming the de facto Question and Answer (Q&A) website, and one of the standard unstructured data sources for software engineering research to mine knowledge about development. We present SODA, the Stack Overflow Dataset Almanac, a tool that helps researchers and developers to better understand the trends of discussion topics in Stack Overflow, based on the available tagging system. SODA provides an effective visualization to support the analysis of topics in different time intervals and frames, leveraging single or co-occurrent tags. We show, through simple usage scenarios, how SODA can be used to find interesting peculiar moments in the evolution of Stack Overflow discussions that closely match specific recent events in the area of software development. SODA is available at http://rio.inf.usi.ch/soda/
StORMeD: Stack Overflow Ready Made Data
Stack Overflow is the de facto Question and Answer (Q&A) website for developers, and it has been used in many approaches by software engineering researchers to mine useful data. However, the contents of a Stack Overflow discussion are inherently heterogeneous, mixing natural language, source code, stack traces and configuration files in XML or JSON format. We constructed a full island grammar capable of modeling the set of 700,000 Stack Overflow discussions talking about Java, building a heterogeneous abstract syntax tree (H-AST) of each post (question, answer or comment) in a discussion. The resulting dataset models every Stack Overflow discussion, providing a full H-AST for each type of structured fragment (i.e., JSON, XML, Java, Stack traces), and complementing this information with a set of basic meta-information like term frequency to enable natural language analyses. Our dataset allows the end-user to perform combined analyses of the Stack Overflow by visiting the H-AST of a discussion.
Summarizing Complex Development Artifacts by Mining Heterogeneous Data
Summarization is hailed as a promising approach to reduce the amount of information that must be taken in by the person who wants to understand development artifacts, such as pieces of code, bug reports, emails, etc. However, existing approaches treat artifacts as pure textual entities, disregarding the heterogeneous and partially structured nature of most artifacts, which contain intertwined pieces of distinct type, such as source code, diffs, stack traces, human language, etc. We present a novel approach to augment existing summarization techniques (such as LexRank) to deal with the heterogeneous and multidimensional nature of complex artifacts. Our preliminary results on heterogeneous artifacts suggest our approach outperforms the current text-based approaches.
Understanding and Classifying the Quality of Technical Forum Questions
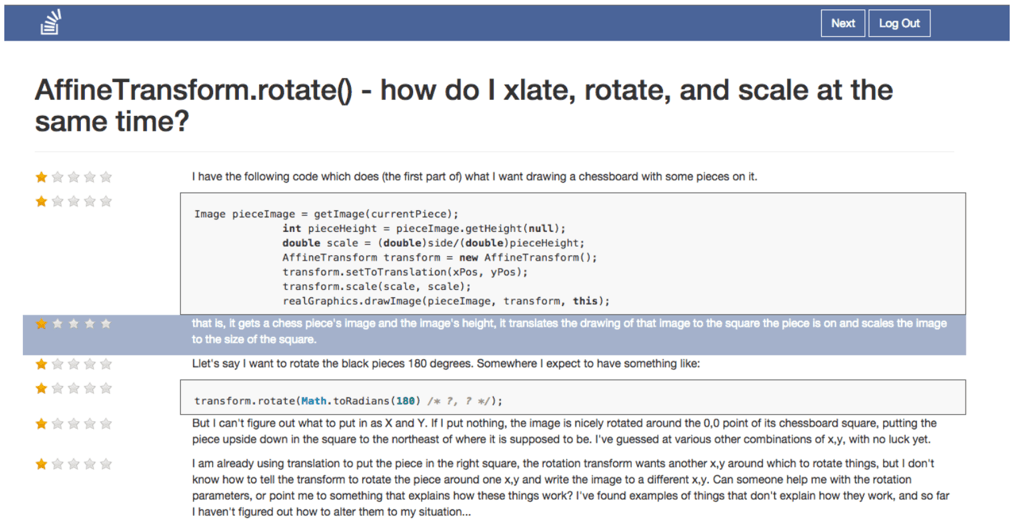
Technical questions and answers (Q&A) services have become a valuable resource for developers. A prominent example of technical Q&A website is StackOverflow (SO), which relies on a growing community of more than two millions of users who actively contribute by asking questions and providing answers. To maintain the value of this resource, poor quality questions - among the more than 6,000 asked daily - have to be filtered out. Currently, poor quality questions are manually identified and reviewed by selected users in SO, this costs considerable time and effort. Automating the process would save time and unload the review queue, improving the efficiency of SO as a resource for developers. We present an approach to automate the classification of questions according to their quality. We present an empirical study that investigates how to model and predict the quality of a question by considering as features both the contents of a post (e.g., from simple textual features to more complex readability metrics) and community-related aspects (e.g., popularity of a user in the community). Our findings show that there is indeed the possibility of at least a partial automation of the costly SO review process.
Improving Low Quality Stack Overflow Post Detection
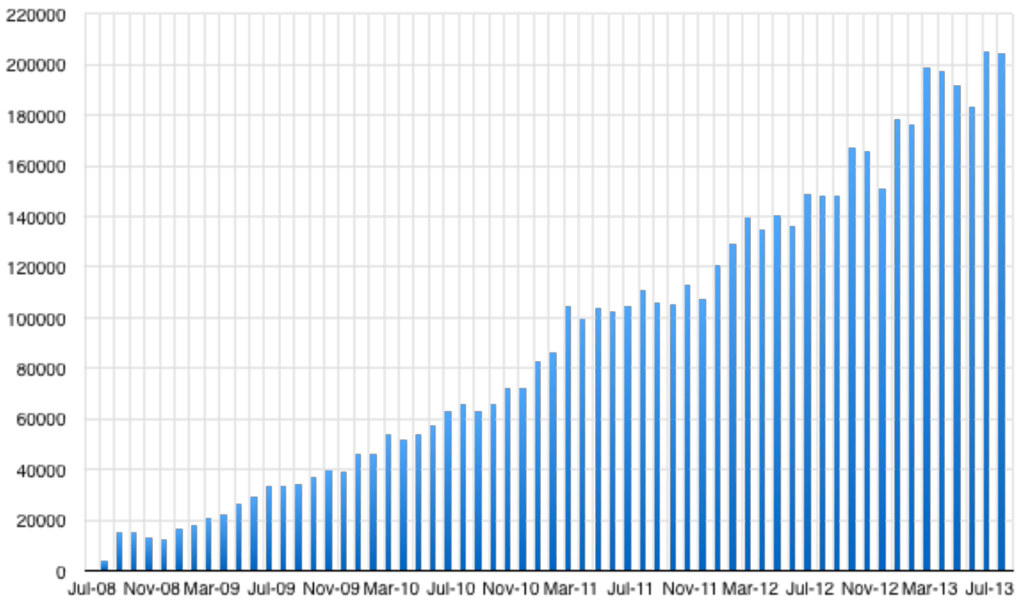
Stack Overflow is a popular questions and answers (Q&A) website among software developers. It counts more than two millions of users who actively contribute by asking and answering thousands of questions daily. Identifying and reviewing low quality posts preserves the quality of site's contents and it is crucial to maintain a good user experience. In Stack Overflow the identification of poor quality posts is performed by selected users manually. The system also uses an automated identification system based on textual features. Low quality posts automatically enter a review queue maintained by experienced users. We present an approach to improve the automated system in use at Stack Overflow. It analyzes both the content of a post (e.g., simple textual features and complex readability metrics) and community-related aspects (e.g., popularity of a user in the community). Our approach reduces the size of the review queue effectively and removes misclassified good quality posts.