
Co-Authored Publications
Automatic Identification and Classification of Software Development Video Tutorial Fragments
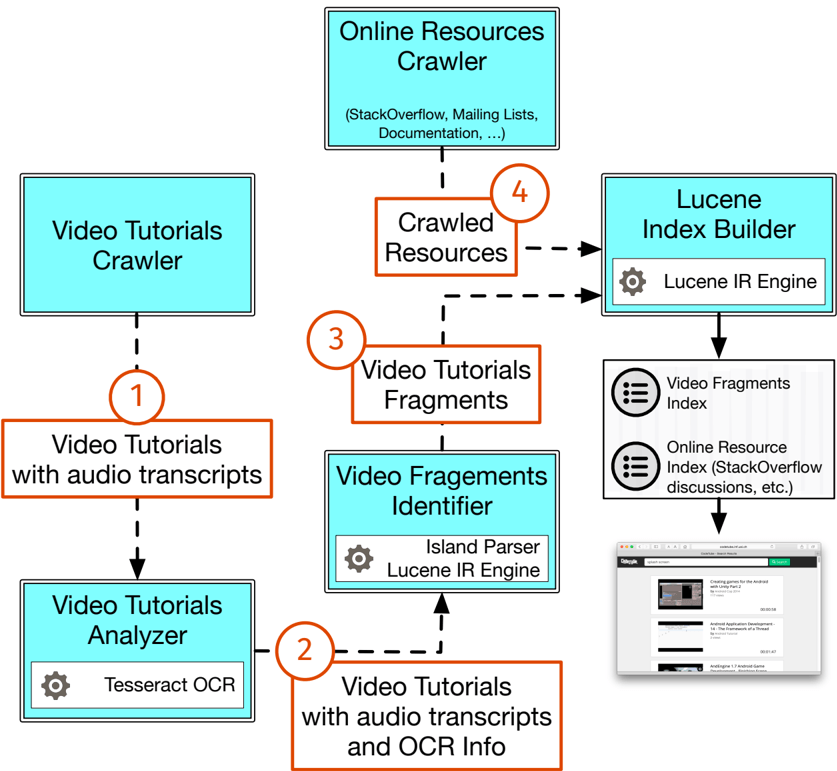
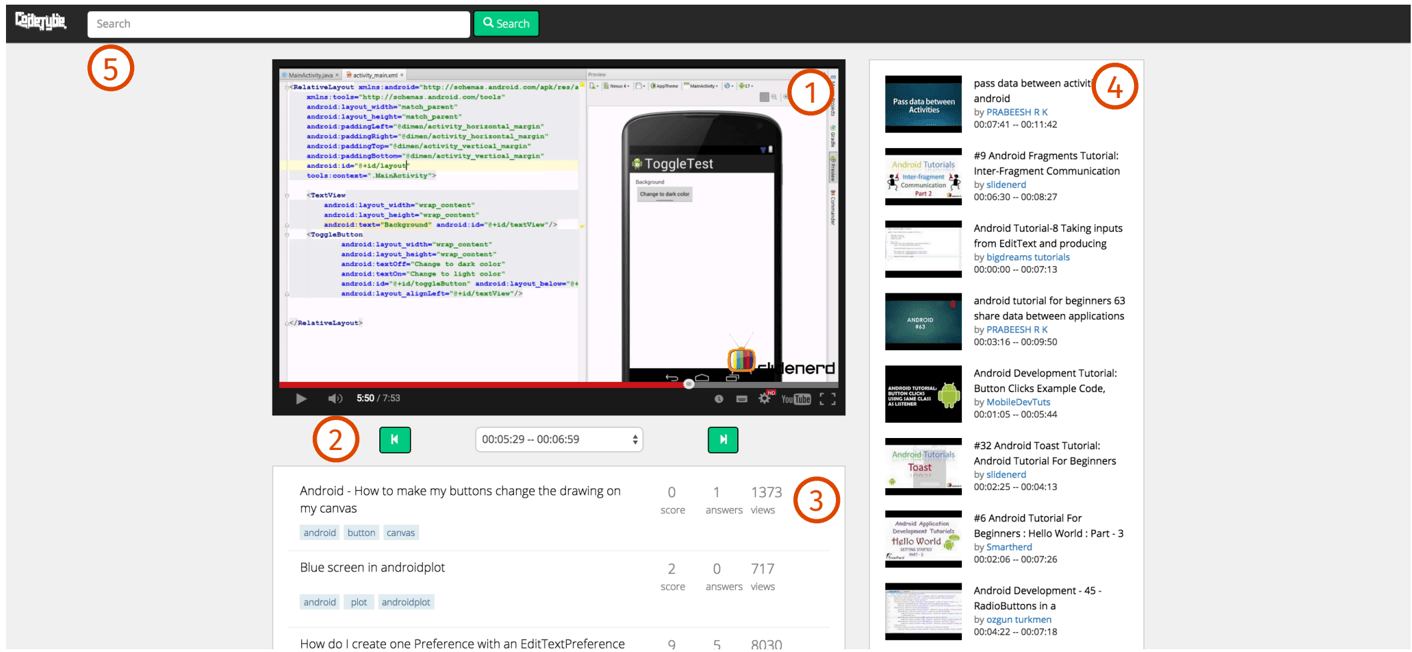
Software development video tutorials have seen a steep increase in popularity in recent years. Their main advantage is that they thoroughly illustrate how certain technologies, programming languages, etc. are to be used. However, they come with a caveat: there is currently little support for searching and browsing their content. This makes it difficult to quickly find the useful parts in a longer video, as the only options are watching the entire video, leading to wasted time, or fast-forwarding through it, leading to missed information. We present an approach to mine video tutorials found on the web and enable developers to query their contents as opposed to just their metadata. The video tutorials are processed and split into coherent fragments, such that only relevant fragments are returned in response to a query. Moreover, fragments are automatically classified according to their purpose, such as introducing theoretical concepts, explaining code implementation steps, or dealing with errors. This allows developers to set filters in their search to target a specific type of video fragment they are interested in. In addition, the video fragments in CodeTube are complemented with information from other sources, such as Stack Overflow discussions, giving more context and useful information for understanding the concepts.
Investigating the Use of Code Analysis and NLP to Promote a Consistent Usage of Identifiers
Meaningless identifiers as well as inconsistent use of identifiers in the source code might hinder code readability and result in increased software maintenance efforts. Over the past years, effort has been devoted to promoting a consistent usage of identifiers across different parts of a system through approaches exploiting static code analysis and Natural Language Processing (NLP). These techniques have been evaluated in small-scale studies, but it is unclear how they compare to each other and how they complement each other. Furthermore, a full-fledged larger empirical evaluation is still missing.,,We aim at bridging this gap. We asked developers of five projects to assess the meaningfulness of the recommendations generated by three techniques, two already existing in the literature (one exploiting static analysis, one using NLP) and a novel one we propose. With a total of 922 rename refactorings evaluated, this is, to the best of our knowledge, the largest empirical study conducted to assess and compare rename refactoring tools promoting a consistent use of identifiers. Our study sheds light on the current state-of-the-art in rename refactoring recommenders, and indicates directions for future work.
Supporting Software Developers with a Holistic Recommender System
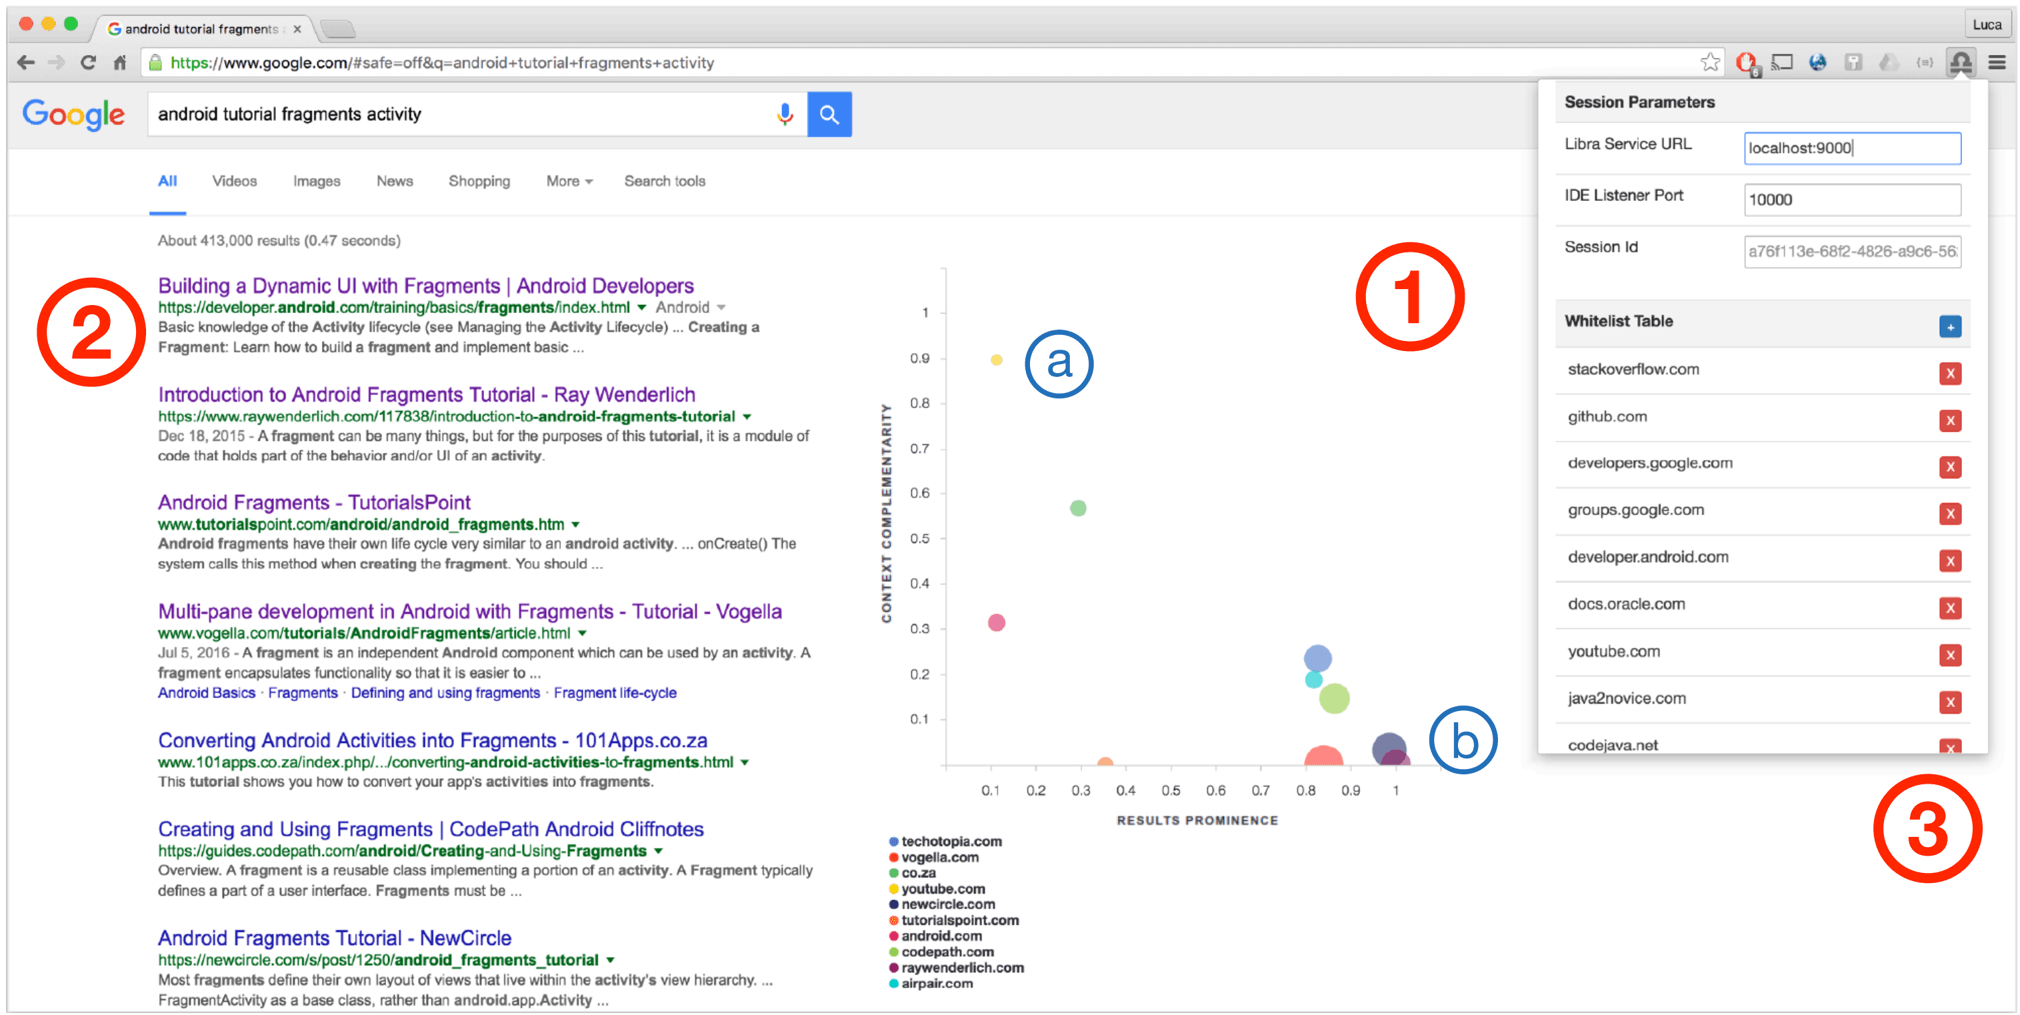
The promise of recommender systems is to provide intelligent support to developers during their programming tasks. Such support ranges from suggesting program entities to taking into account pertinent QnA pages. However, current recommender systems limit the context analysis to change history and developers' activities in the IDE, without considering what a developer has already consulted or perused, e.g., by performing searches from the Web browser. Given the faceted nature of many programming tasks, and the incompleteness of the information provided by a single artifact, several heterogeneous resources are required to obtain the broader picture needed by a developer to accomplish a task. We present Libra, a holistic recommender system. It supports the process of searching and navigating the information needed by constructing a holistic meta-information model of the resources perused by a developer, analyzing their semantic relationships, and augmenting the web browser with a dedicated interactive navigation chart. The quantitative and qualitative evaluation of Libra provides evidence that a holistic analysis of a developer's information context can indeed offer comprehensive and contextualized support to information navigation and retrieval during software development.
Too Long; Didn't Watch! Extracting Relevant Fragments from Software Development Video Tutorials
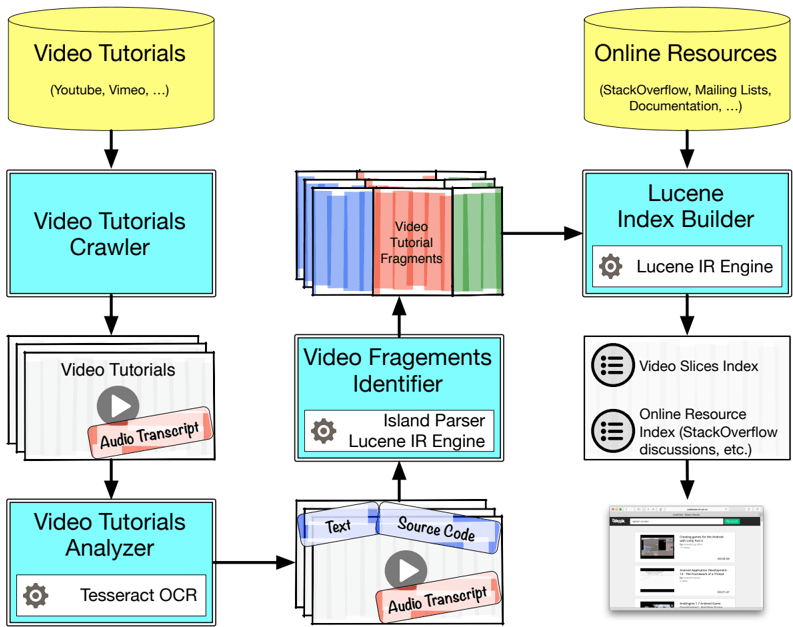
When knowledgeable colleagues are not available, developers resort to offline and online resources, e.g. tutorials, mailing lists, and Q&A websites. These, however, need to be found, read, and understood, which takes its toll in terms of time and mental energy. A more immediate and accessible resource are video tutorials found on the web, which in recent years have seen a steep increase in popularity. Nonetheless, videos are an intrinsically noisy data source, and finding the right piece of information might be even more cumbersome than using the previously mentioned resources. We present CodeTube, an approach which mines video tutorials found on the web, and enables developers to query their contents. The video tutorials are split into coherent fragments, to return only fragments related to the query. These are complemented with information from additional sources, such as Stack Overflow discussions. The results of two studies to assess CodeTube indicate that video tutorials - if appropriately processed - represent a useful, yet still under-utilized source of information for software development.
CodeTube: Extracting Relevant Fragments from Software Development Video Tutorials
Nowadays developers heavily rely on sources of informal documentation. Examples include Q&A forums, slides, or video tutorials, the latter being particularly useful to provide introductory notions for a piece of technology. The current practice is that developers have to browse sources individually, which in the case of video tutorials is cumbersome, as they are lengthy and cannot be searched based on their contents. We present CodeTube, a Web-based recommender system that analyzes the contents of video tutorials and is able to provide, given a query, cohesive and self-contained video fragments, along with links to relevant Stack Overflow discussions. CodeTube relies on a combination of textual analysis and image processing applied on video tutorial frames and speech transcripts to split videos into cohesive fragments, index them and identify related Stack Overflow discussions.