Publications
A Taxonomy of Design Quality in Super Mario Maker 2
Thanks to its popularity, Super Mario Maker 2 (SMM2) features myriad user-designed platforming levels that span a broad range of styles, genres, difficulty, and quality. This paper is a first attempt at charting out this vast landscape of levels, with the goal of exploring the main concepts that characterize design quality. To this end, we first selected 500 videos by popular YouTube streamers that play SMM2 levels. With the help of an LLM, we extracted and clustered by topic segments where the streamer comments about the design of the level they are playing. Then, we applied a grounded theory coding process to extract the concepts emerging in these segments, and we combined and organized them hierarchically. The resulting taxonomy identifies the main abstract concepts that pertain to the design of a level in SMM2 and its resulting quality, as well as several concrete elements of the game that belong to each abstract category. Besides illustrating the underlying dimensions that characterize design quality in SMM2, our results also illuminate the diverse landscape of player-designed levels in the game.
Mining a Century of Swiss Trademark Data
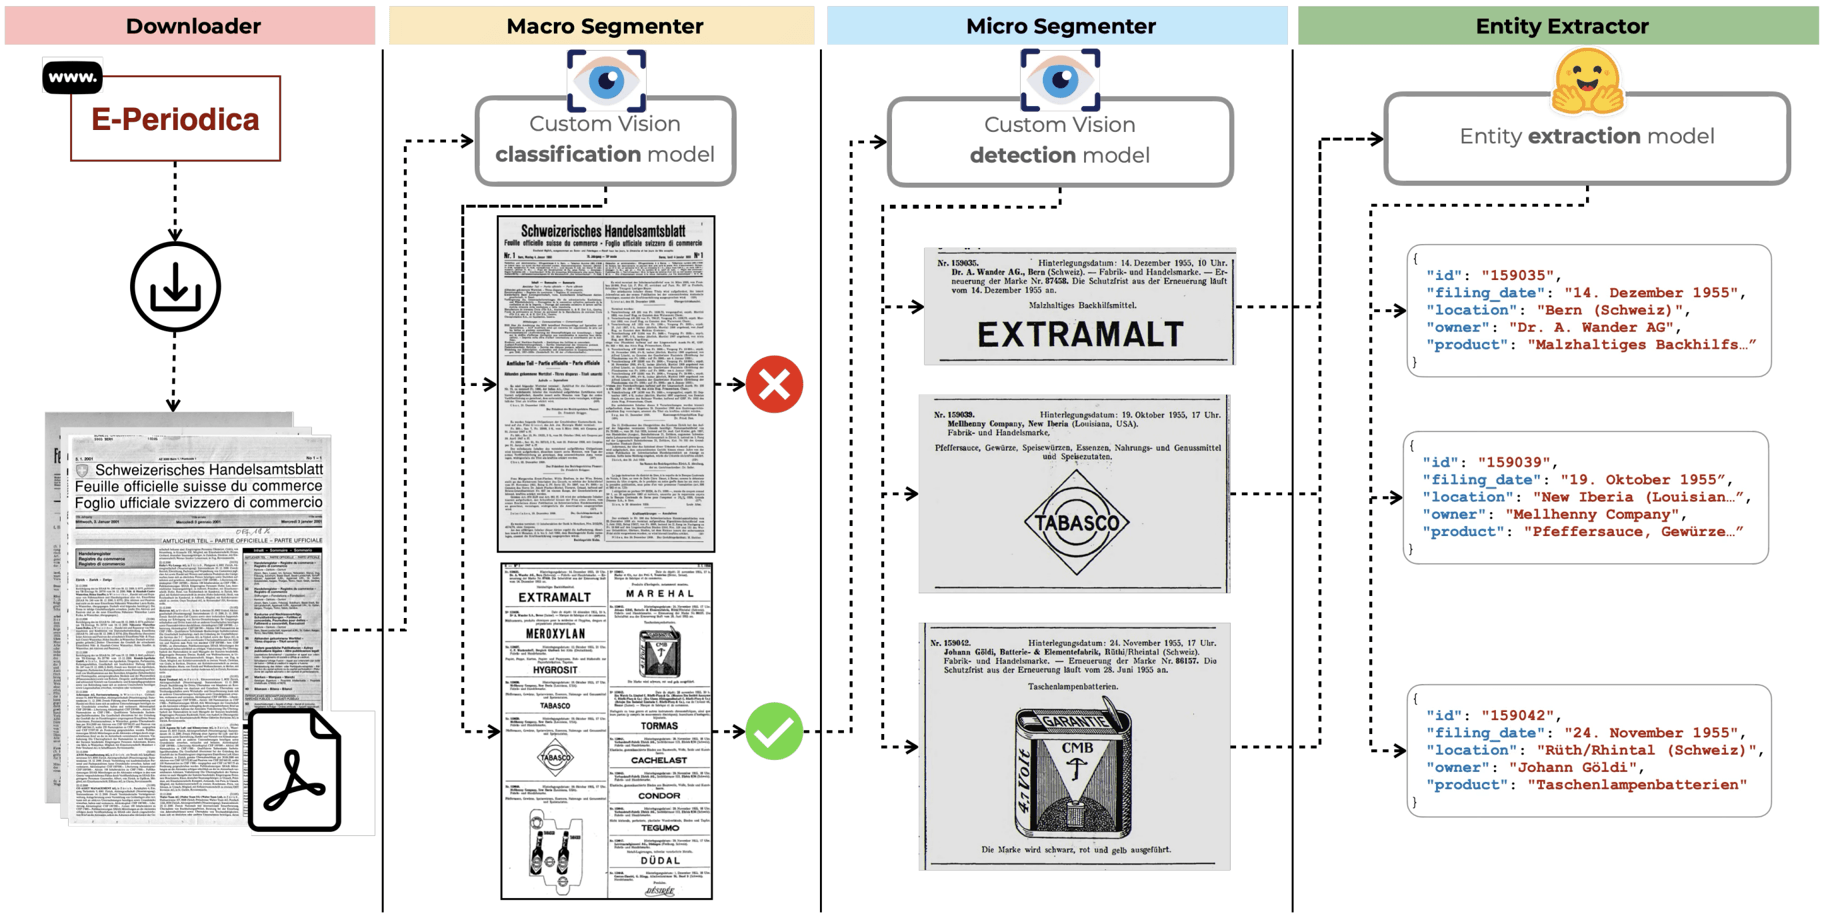
This paper presents an approach for extracting trademark registration events from the Swiss Official Gazette of Commerce (SOGC), an official daily journal published by the Swiss Confederation since January 1883. Until 2001, the data is only available as scanned documents, which constitute the target dataset of this study. Our approach is composed of a chain of three steps based on state-of-the-art deep learning techniques. We leverage image classification to identify pages containing trademarks (macro segmentation); we apply object detection to identify the portion of the page corresponding to a registration event (micro segmentation); last, we perform information extraction using a document AI technique. We obtain a dataset of ca. 500,000 trademark registration events, extracted from a corpus of 430,000 pages. Each step of our workflow has relatively high accuracy: the macro and micro segmentation steps show precision and recall greater than 95% on a manually constructed dataset. The dataset offers a unique historical perspective on trademark registrations in Switzerland that is not available from any other source. Showcasing what can be achieved with the extracted information, we provide answers to a set of preliminary economics questions.
What Makes a Level Hard in Super Mario Maker 2?
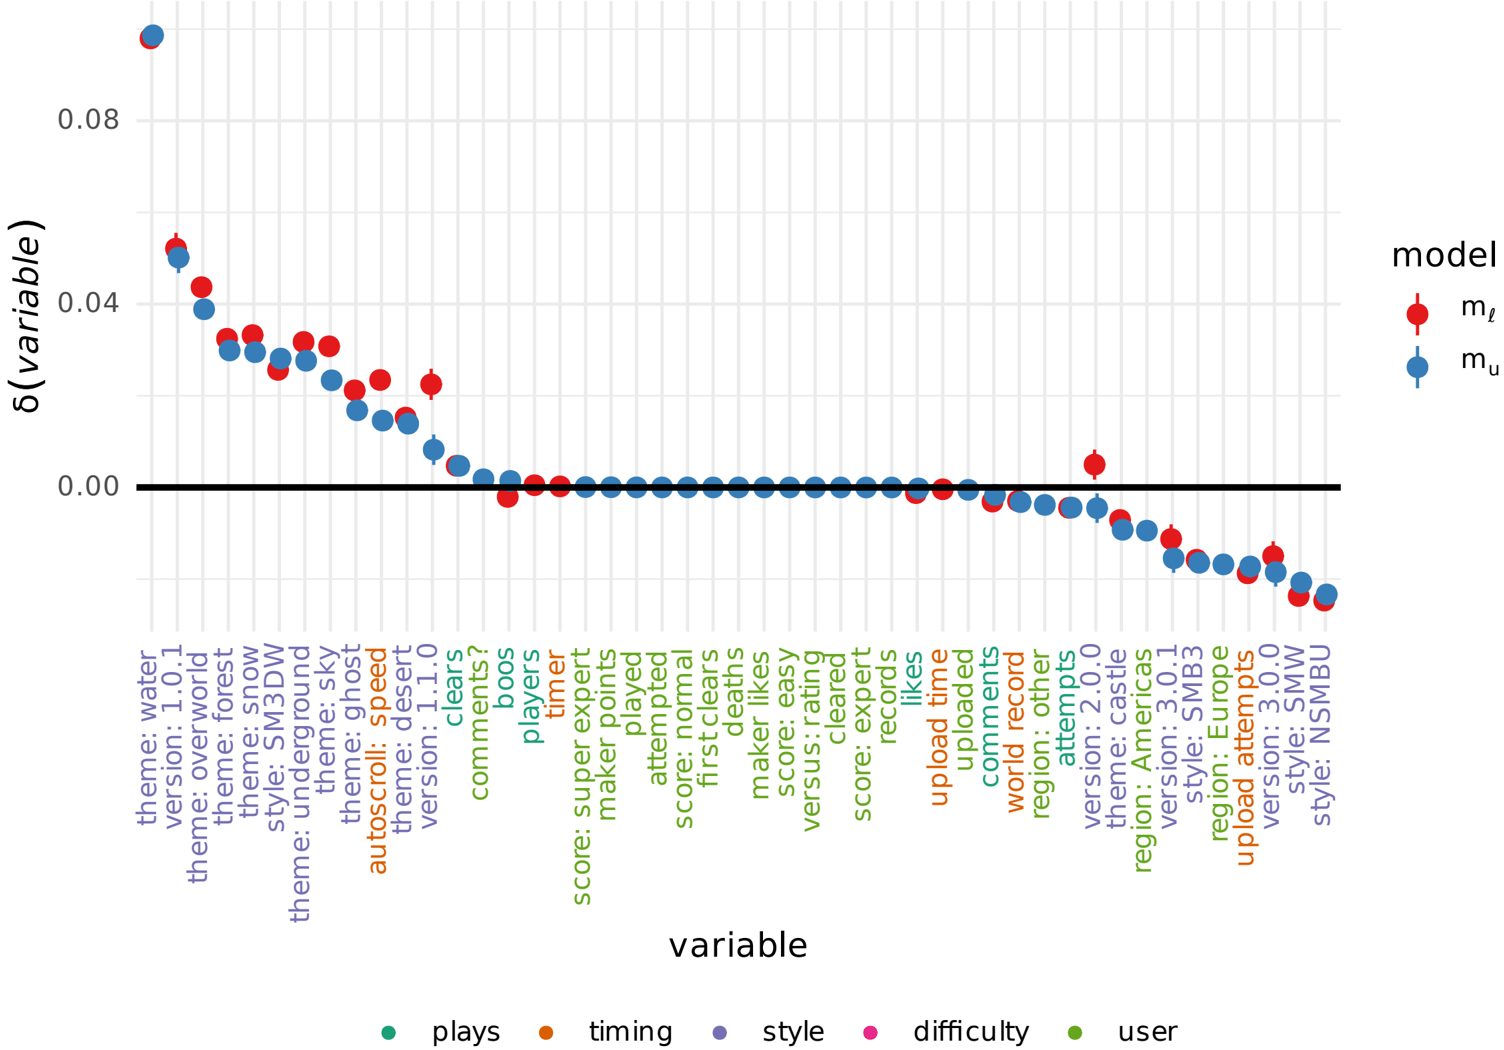
Games like Super Mario Maker 2 (SMM2) lower the barrier for casual users to become level designers. In this paper, we set out to analyze a vast amount of data about SMM2 user-written levels, in order to understand what factors affect a level's difficulty as experienced by other users. To this end, we perform two kinds of analyses: one based on regression models and one using natural language processing techniques. The main results shed light on which level characteristics (e.g., its style, popularity, timing) and which topics and sentiments have a consistent association with easier or harder levels. While none of our findings are startling, they help distill some key differences between easy and hard SMM2 levels, which, in turn, can pave the way for a better understanding of end-user level design.
Visualizing Interaction Data Inside & Outside the IDE to Characterize Developer Productivity
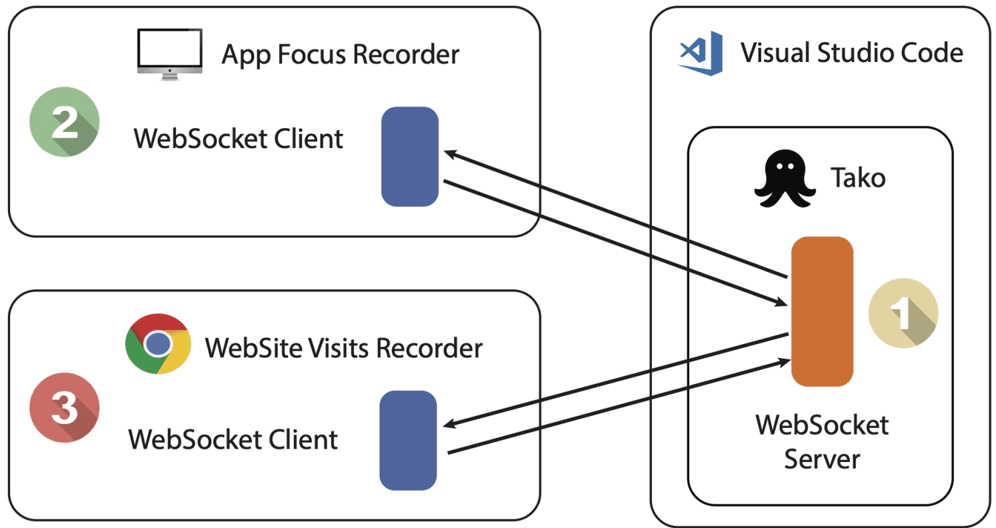
Work fragmentation is a common phenomenon in the workspace, and is detrimental to the actual work taking place. To measure and study the impact of work fragmentation in software development, several studies exploited interaction data, i.e., the data generated by the events performed by the developers in the IDE. However, the absence of information on activities performed outside the IDE could lead to a misclassification of development time. In fact, sometimes leaving the IDE is not an interruption of the task at hand, e.g., when consulting API documentation, or when discussing with colleagues in ad-hoc collaboration applications. In this paper, we propose Ferax, a data analytics platform that developers can leverage for retrospection and possibly to improve their productivity. The capabilities of Ferax are twofold: First, it extends Tako, a profiler to record IDE interaction data for Visual Studio Code, with information about which applications were used and which websites were visited. Second, to enable the understanding of productivity and interruptions on developer sessions, Ferax provides interactive visualizations that show the detailed sequence of events inside and outside the IDE, the switches the developer performs by classifying them as productive or possible interruptions, and the time distribution for application usage. As a preliminary evaluation of Ferax we have collected and analyzed real development sessions from a set of master students and two professional developers. We illustrate how a developer can leverage Ferax to characterize her usual habits, to elicit the impact of interruptions, and to better characterize sessions which were only apparently unproductive.
Automatic Identification and Classification of Software Development Video Tutorial Fragments
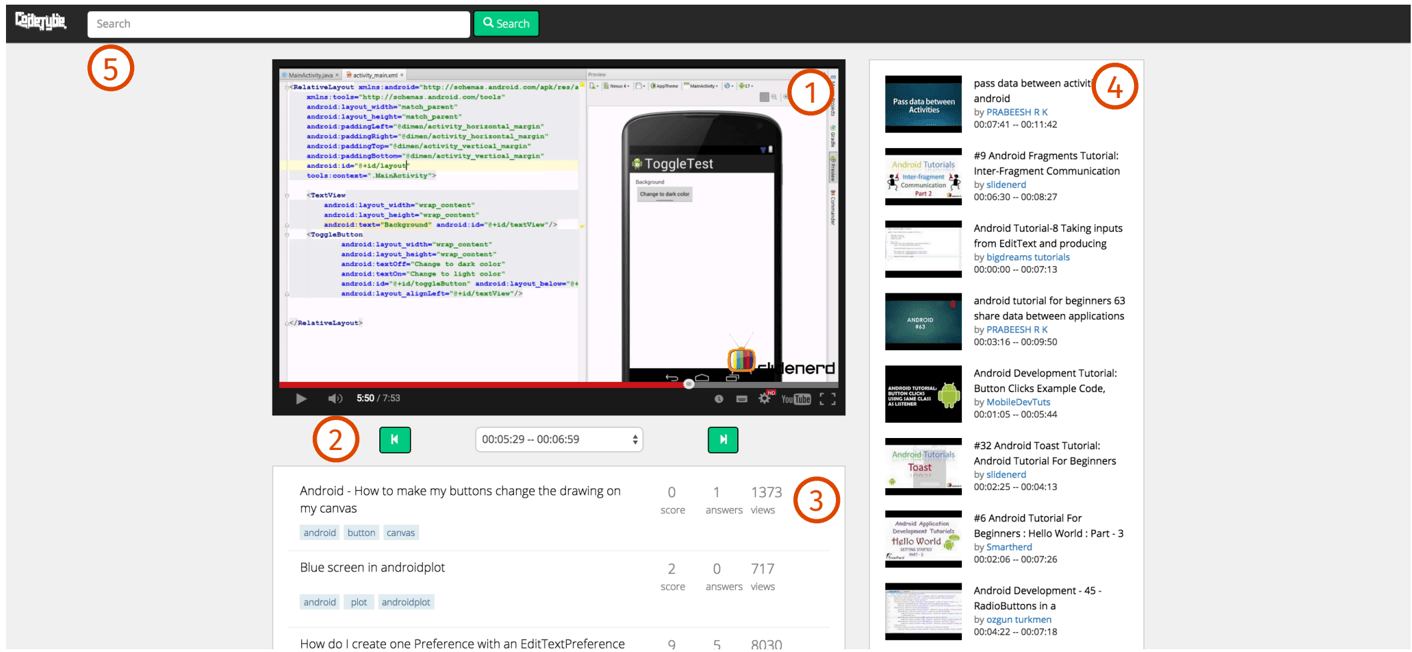
Software development video tutorials have seen a steep increase in popularity in recent years. Their main advantage is that they thoroughly illustrate how certain technologies, programming languages, etc. are to be used. However, they come with a caveat: there is currently little support for searching and browsing their content. This makes it difficult to quickly find the useful parts in a longer video, as the only options are watching the entire video, leading to wasted time, or fast-forwarding through it, leading to missed information. We present an approach to mine video tutorials found on the web and enable developers to query their contents as opposed to just their metadata. The video tutorials are processed and split into coherent fragments, such that only relevant fragments are returned in response to a query. Moreover, fragments are automatically classified according to their purpose, such as introducing theoretical concepts, explaining code implementation steps, or dealing with errors. This allows developers to set filters in their search to target a specific type of video fragment they are interested in. In addition, the video fragments in CodeTube are complemented with information from other sources, such as Stack Overflow discussions, giving more context and useful information for understanding the concepts.
Mining structured data in natural language artifacts with island parsing
Software repositories typically store data composed of structured and unstructured parts. Researchers mine this data to empirically validate research ideas and to support practitioners' activities. Structured data (e.g., source code) has a formal syntax and is straightforward to analyze; unstructured data (e.g., documentation) is a mix of natural language, noise, and snippets of structured data, and it is harder to analyze. Especially the structured content (e.g., code snippets) in unstructured data contains valuable information. Researchers have proposed several approaches to recognize, extract, and analyze structured data embedded in natural language. We analyze these approaches and investigate their drawbacks. Subsequently, we present two novel methods, based on scannerless generalized LR (SGLR) and Parsing Expression Grammars (PEGs), to address these drawbacks and to mine structured fragments within unstructured data. We validate and compare these approaches on development emails and Stack Overflow posts with Java code fragments. Both approaches achieve high precision and recall values, but the PEG-based one achieves better computational performances and simplicity in engineering.
Investigating the Use of Code Analysis and NLP to Promote a Consistent Usage of Identifiers
Meaningless identifiers as well as inconsistent use of identifiers in the source code might hinder code readability and result in increased software maintenance efforts. Over the past years, effort has been devoted to promoting a consistent usage of identifiers across different parts of a system through approaches exploiting static code analysis and Natural Language Processing (NLP). These techniques have been evaluated in small-scale studies, but it is unclear how they compare to each other and how they complement each other. Furthermore, a full-fledged larger empirical evaluation is still missing.,,We aim at bridging this gap. We asked developers of five projects to assess the meaningfulness of the recommendations generated by three techniques, two already existing in the literature (one exploiting static analysis, one using NLP) and a novel one we propose. With a total of 922 rename refactorings evaluated, this is, to the best of our knowledge, the largest empirical study conducted to assess and compare rename refactoring tools promoting a consistent use of identifiers. Our study sheds light on the current state-of-the-art in rename refactoring recommenders, and indicates directions for future work.
Sympathy for the Devil: Reified Collection of Runtime Errors
Software development involves iterations of writing, running, testing, and debugging code. When fixing a defect, developers construct a mental model of the system that explains the defect and eventually identifies its cause. However, filtering complete, coherent, and reliable information from a running system is not an easy task: Using a simple approach, like generic logging, is often ineffective because it deconstructs and flattens the state into textual data, thus requiring ad-hoc understanding and processing. On the other hand, collecting structured information in form of objects to observe and understand a precise property of the system requires specialized ad-hoc code, decoupled from the system's domain, and usually not reusable. We present ShoreLine, a domain-specific data collection framework that enables the developers to extract selected information about a running system. The developer is able to take a snapshot of all the information deemed relevant about a piece of code by writing few lines of code, thus enabling structured and effective logging and reporting of errors. We detail our framework in the context of a bug reporting platform, and illustrate how such an approach can be used to create in-depth and reliable domain-specific bug reports.