Overview
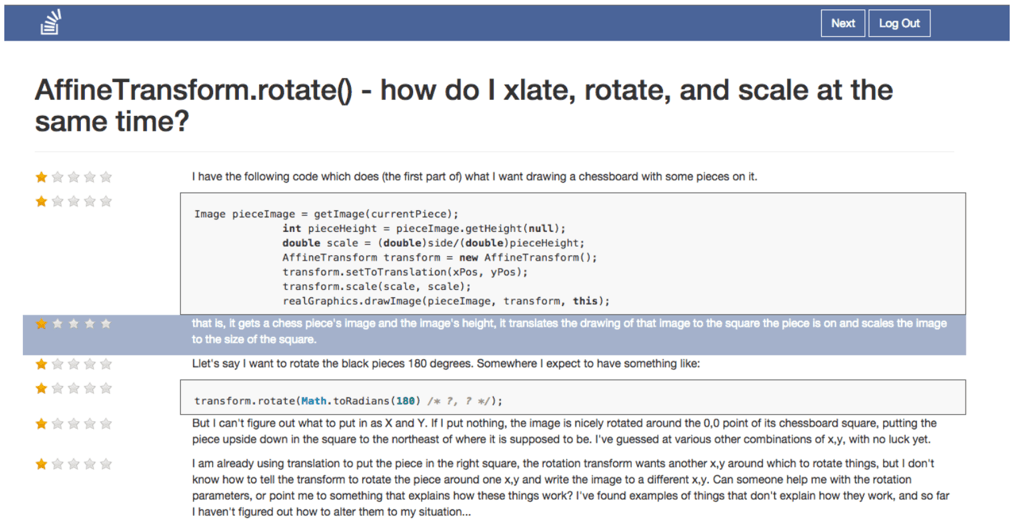
The contents of a Stack Overflow discussion are inherently heterogeneous: natural language, source code, stack traces, and configuration files in XML or JSON, all intertwined in the same post. StORMeD — Stack Overflow Ready Made Data — models that mixture with a full-fledged heterogeneous island grammar, turning every discussion tagged with java into a Heterogeneous Abstract Syntax Tree (H-AST) that can be navigated across all of those languages at once, complemented with basic meta-information such as term frequency for natural language analyses.
StORMeD was released in three parts: the ready-made dataset, the development kit that reads and visits it, and a web service that exposes the island parser itself.
The Dataset
The dataset provides one H-AST per discussion in JSON format, so that the heterogeneous structure of a post — its Java fragments, JSON and XML snippets, and stack traces — is available without building an island parser or running the analysis infrastructure needed to produce one. It is built from the Stack Exchange Data Dump published on the Internet Archive, and the last published version covers discussions up to June 2017.
The Development Kit
The DevKit is a Scala library exposing the same H-AST model used to generate the dataset, so that discussions can be analyzed directly from the JSON files rather than loaded into a database first. Deserializing an artifact takes three lines, and the H-AST is then visited programmatically: the kit ships collecting visitors for identifiers, types, method invocations and declarators, imports, variable declarators, classes, interfaces, and enums, each of which accepts a filtering function (Visitable => Boolean) to skip parts of the tree — excluding identifiers declared inside method bodies, for instance. Custom collectors for node types without a built-in visitor are written by extending NodeAccumulatorVisitor with an extractor for the nodes of interest.
The kit was published for Scala 2.12 as ch.usi.inf.reveal.parsing:stormed-devkit and consumed from Maven or sbt through StORMeD’s own artifact repository. That repository no longer answers, so the DevKit is in practice only usable from a copy already in hand.
The Island Parsing Service
The island parsing technology behind the dataset is also exposed as a REST service, for callers who need to parse arbitrary text rather than the pre-parsed discussions. It offers two methods, both taking a JSON POST body carrying the text and a service key:
/parsereturns the list ofHASTNodeobjects produced by parsing the submitted text — the same H-AST nodes found in the dataset./taggerreturns the submitted text with its code elements wrapped in<code>tags, either from plain text or from an already partially tagged input, in which case existing tags are preserved.
Both answer with a status of OK or ERROR: an error carries a message, and a success carries the parsing result along with quotaRemaining. Access is keyed: registration with a valid email address yields one personal key, good for a daily quota of 1000 requests that resets at midnight, with a recovery page for keys that get lost. The keying exists to identify callers and prevent abuse, not to charge for the service — it is free.